
Downloads · 30 days
22
8% of all-time downloads
GXMZU/Qwen3-14B-ai-expert
Qwen3-14B-ai-expert is a text generation model from GXMZU. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
<p align="center" 🤗 <a href="https://huggingface.co/GXMZU/Qwen3-14B-ai-expert"Hugging Face</a   |   🤖 <a href="https://www.modelscope.cn/models/GXMZU/Qwen3-14B-ai-expert"ModelScope</a </p
Downloads · 30 days
22
8% of all-time downloads
All-time downloads
267
Public
Parameters
14.8B
29.5 GB on disk
Likes
2
Public
Click a slice to open those files.
.safetensors29.5 GB · 100%
From the Hugging Face model README
This model is a specialized expert on core Artificial Intelligence concepts, developed by performing Instruction Supervised Fine-Tuning (SFT) on the Qwen/Qwen3-14B model.
The fine-tuning was conducted using Low-Rank Adaptation (LoRA), a parameter-efficient technique, on a custom-built dataset. This process adapted the model to provide high-quality, detailed responses specifically within the domains of:
The model was fine-tuned with LlaMA-Factory.
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "GXMZU/Qwen3-14B-ai-expert"

# Load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype="auto",
    device_map="auto"
)

# Prepare the model input
prompt = "What is MCP Protocol?"
messages = [
    {"role": "system", "content": "You are an AI expert assistant (Focus on LLM, RAG, and Agent Domain) to help with technical questions. You should provide clear, accurate, and helpful responses."},
    {"role": "user", "content": prompt}
]

text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True,
    enable_thinking=False  # Switches between thinking and non-thinking modes. Default is True.
)

model_inputs = tokenizer([text], return_tensors="pt").to(model.device)

# Conduct text completion
generated_ids = model.generate(
    **model_inputs,
    max_new_tokens=512
)

output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()

# Parse thinking content (if enabled)
try:
    # rindex finding 151668 (</think>)
    index = len(output_ids) - output_ids[::-1].index(151668)
except ValueError:
    index = 0

thinking_content = tokenizer.decode(output_ids[:index], skip_special_tokens=True).strip("\n")
content = tokenizer.decode(output_ids[index:], skip_special_tokens=True).strip("\n")

if thinking_content:
    print("Thinking content:", thinking_content)
print("Response:", content)
The primary objective of this fine-tuning is to adapt the model to a specialized domain, enhancing its performance on specific tasks by injecting relevant knowledge and terminology while preserving its foundational generalist capabilities.
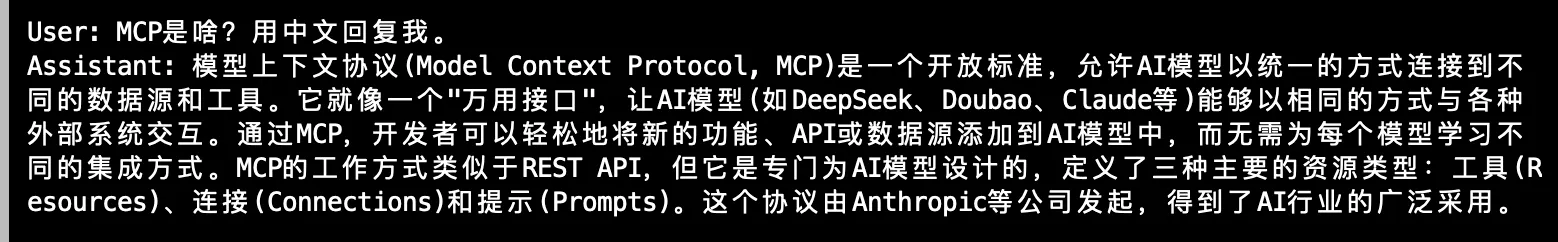
The model demonstrates significant improvements in domain-specific tasks related to LLM, RAG, and AI Agents, as shown in the example below:
The model was fine-tuned on a custom, high-quality dataset. The dataset was carefully curated to cover three core areas:
If you use this model in your work, please cite it as:
@misc{Qwen3-14B-AI-Expert,
  author = {real-jiakai},
  title = {Qwen3-14B-AI-Expert},
  year = 2025,
  url = {https://huggingface.co/GXMZU/Qwen3-14B-ai-expert},
  publisher = {Hugging Face}
}

@misc{qwen3technicalreport,
  title={Qwen3 Technical Report},
  author={Qwen Team},
  year={2025},
  eprint={2505.09388},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2505.09388}
}

@inproceedings{zheng2024llamafactory,
  title={LlamaFactory: Unified Efficient Fine-Tuning of 100+ Language Models},
  author={Yaowei Zheng and Richong Zhang and Junhao Zhang and Yanhan Ye and Zheyan Luo and Zhangchi Feng and Yongqiang Ma},
  booktitle={Proceedings of the 62nd Annual Meeting of the Association for Computational Linguistics (Volume 3: System Demonstrations)},
  address={Bangkok, Thailand},
  publisher={Association for Computational Linguistics},
  year={2024},
  url={http://arxiv.org/abs/2403.13372}
}