Downloads · 30 days
29
3% of all-time downloads
FremyCompany/xls-r-2b-nl-v2_lm-5gram-os2_hunspell
xls-r-2b-nl-v2_lm-5gram-os2_hunspell is a automatic speech recognition model from FremyCompany. Use it when you need speech turned into text. It is set up for transformers.
This model is a version of facebook/wav2vec2-xls-r-2b-22-to-16 fine-tuned mainly on the CGN dataset, as well as the MOZILLA-FOUNDATION/COMMONVOICE80 - NL dataset (see details below), on which a large 5-gram language m…
Downloads · 30 days
29
3% of all-time downloads
All-time downloads
1.1K
Public
Repo size
25.5 GB
Likes
4
Public
Click a slice to open those files.
.bin16.9 GB · 100%
From the Hugging Face model README
This model is a version of facebook/wav2vec2-xls-r-2b-22-to-16 fine-tuned mainly on the CGN dataset, as well as the MOZILLA-FOUNDATION/COMMON_VOICE_8_0 - NL dataset (see details below), on which a large 5-gram language model is added based on the Open Subtitles Dutch corpus. This model achieves the following results on the evaluation set (of Common Voice 8.0):
IMPORTANT NOTE: The
hunspelltypo fixer is not enabled on the website, which returns raw CTC+LM results. Hunspell reranking is only available in theeval.pydecoding script. For best results, please use the code in that file while using the model locally for inference.
IMPORTANT NOTE: Evaluating this model requires
apt install libhunspell-devand a pip install ofhunspellin addition to pip installs ofpipy-kenlmandpyctcdecode(seeinstall_requirements.sh); in addition, the chunking lengths and strides were optimized for the model as12sand2srespectively (seeeval.sh).
QUICK REMARK: The "Robust Speech Event" set does not contain cleaned transcription text, so its WER/CER are vastly over-estimated. For instance
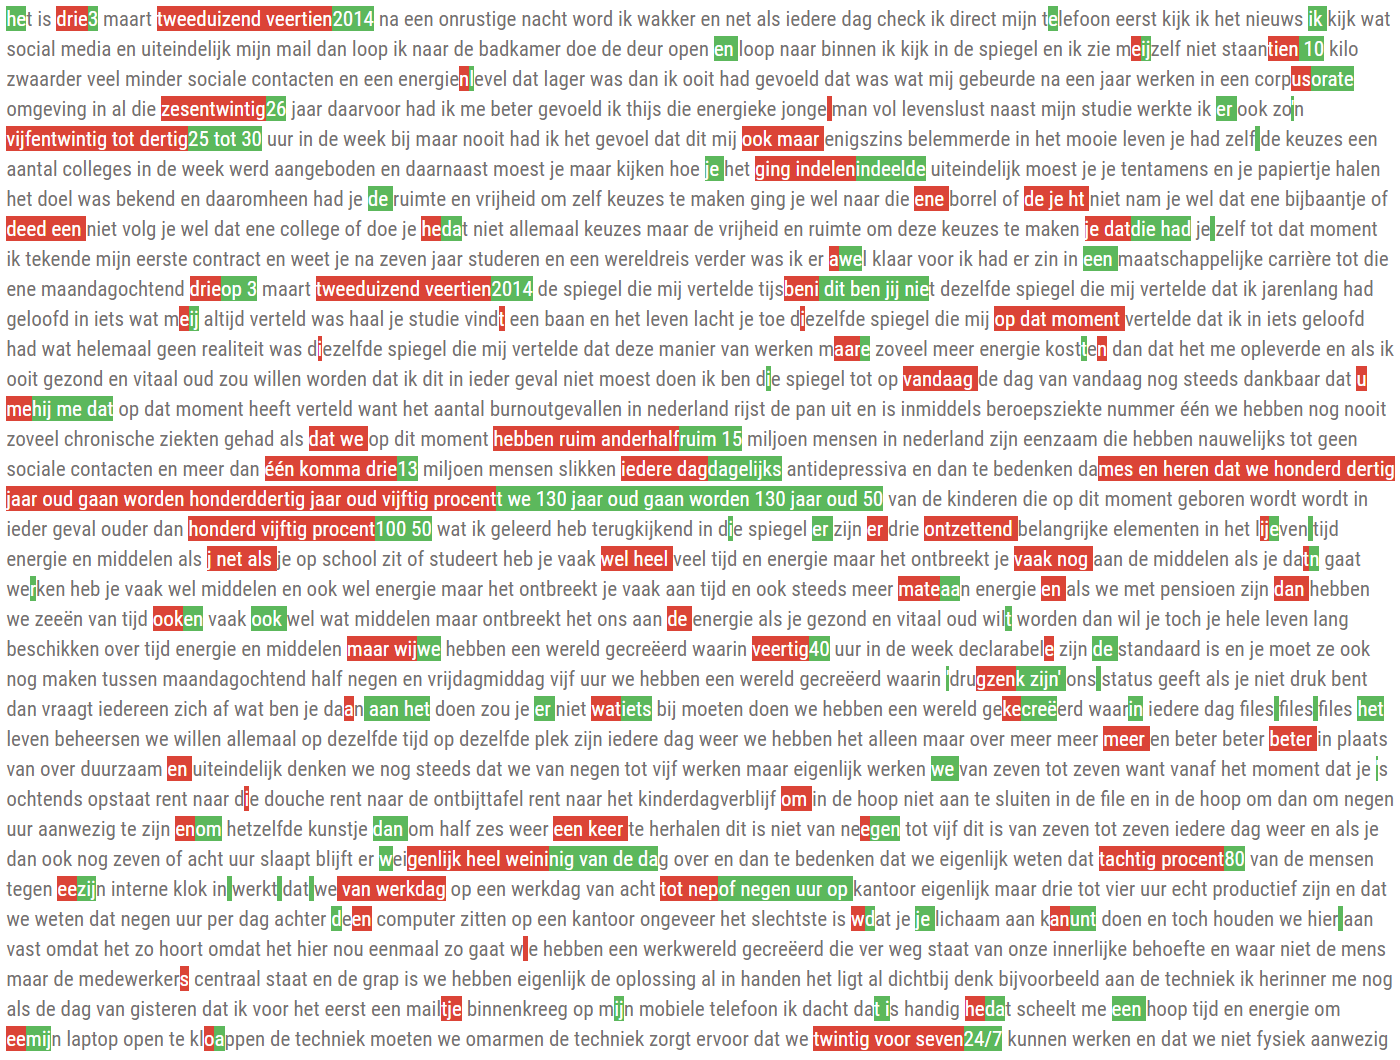
2014in the dev set is left as a number but will be recognized astweeduizend veertien, which counts as 3 mistakes (2014missing, and bothtweeduizendandveertienwrongly inserted). Other normalization problems in the dev set include the presence of single quotes around some words, that then end up as non-match despite being the correct word (but without quotes), and the removal of some speech words in the final transcript (ja, etc...). As a result, our real error rate on the dev set is significantly lower than reported.
You can compare the predictions with the targets on the validation dev set yourself, for example using this diffing tool.
WE DO SPEECH RECOGNITION: Hello reader! If you are considering using this (or another) model in production, but would benefit from a model fine-tuned specifically for your use case (using text and/or labelled speech), feel free to contact our team. This model was developped during the Robust Speech Recognition challenge event by François REMY (twitter) and Geoffroy VANDERREYDT.
We would like to thank OVH for providing us with a V100S GPU.
The model takes 16kHz sound input, and uses a Wav2Vec2ForCTC decoder with 48 letters to output the letter-transcription probabilities per frame.
To improve accuracy, a beam-search decoder based on pyctcdecode is then used; it reranks the most promising alignments based on a 5-gram language model trained on the Open Subtitles Dutch corpus.
To further deal with typos, hunspell is used to propose alternative spellings for words not in the unigrams of the language model. These alternatives are then reranked based on the language model trained above, and a penalty proportional to the levenshtein edit distance between the alternative and the recognized word. This for examples enables to correct collegas into collega's or gogol into google.
This model can be used to transcribe Dutch or Flemish spoken dutch to text (without punctuation).
The model was:
5 epochs (6000 iterations of batch size 32) on the cv8/nl dataset.1 epoch (36000 iterations of batch size 32) on the cgn dataset.5 epochs (6000 iterations of batch size 32) on the cv8/nl dataset.