Downloads · 30 days
13.1K
3% of all-time downloads
FredZhang7/distilgpt2-stable-diffusion-v2
distilgpt2-stable-diffusion-v2 is a text generation model from FredZhang7. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as creativeml-openrail-m.
<style .container { padding-left: 20px; border-left: 5px solid gray; } </style
Downloads · 30 days
13.1K
3% of all-time downloads
All-time downloads
492K
Public
Parameters
88.2M
669 MB on disk
Likes
102
Public
Click a slice to open those files.
.bin334 MB · 50%
How the weights are stored.
F3281.9M · 93%
From the Hugging Face model README
This model was trained on 2,470,000 descriptive stable diffusion prompts on the FredZhang7/distilgpt2-stable-diffusion checkpoint for another 4,270,000 steps.
Compared to other prompt generation models using GPT2, this one runs with 50% faster forwardpropagation and 40% less disk space & RAM.
Major improvements from v1 are:
See the Prompt Generator tab of Paint Journey Demo.
pip install --upgrade transformers
from transformers import GPT2Tokenizer, GPT2LMHeadModel
tokenizer = GPT2Tokenizer.from_pretrained('distilgpt2')
tokenizer.add_special_tokens({'pad_token': '[PAD]'})
model = GPT2LMHeadModel.from_pretrained('FredZhang7/distilgpt2-stable-diffusion-v2')

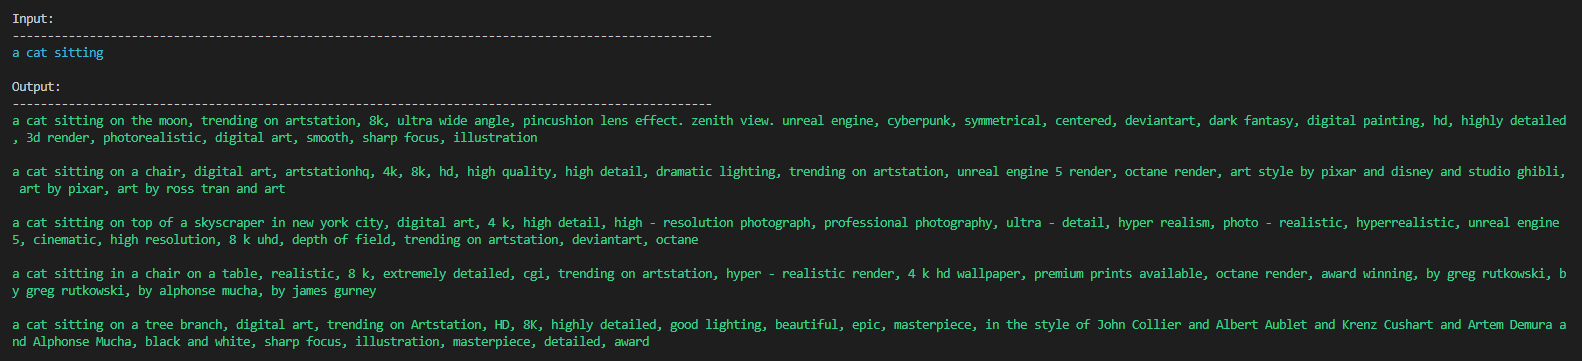
prompt = r'a cat sitting'     # the beginning of the prompt
temperature = 0.9             # a higher temperature will produce more diverse results, but with a higher risk of less coherent text
top_k = 8                     # the number of tokens to sample from at each step
max_length = 80               # the maximum number of tokens for the output of the model
repitition_penalty = 1.2      # the penalty value for each repetition of a token
num_return_sequences=5        # the number of results to generate

# generate the result with contrastive search
input_ids = tokenizer(prompt, return_tensors='pt').input_ids
output = model.generate(input_ids, do_sample=True, temperature=temperature, top_k=top_k, max_length=max_length, num_return_sequences=num_return_sequences, repetition_penalty=repitition_penalty, penalty_alpha=0.6, no_repeat_ngram_size=1, early_stopping=True)

print('\nInput:\n' + 100 * '-')
print('\033[96m' + prompt + '\033[0m')
print('\nOutput:\n' + 100 * '-')
for i in range(len(output)):
    print('\033[92m' + tokenizer.decode(output[i], skip_special_tokens=True) + '\033[0m\n')
No comma style:
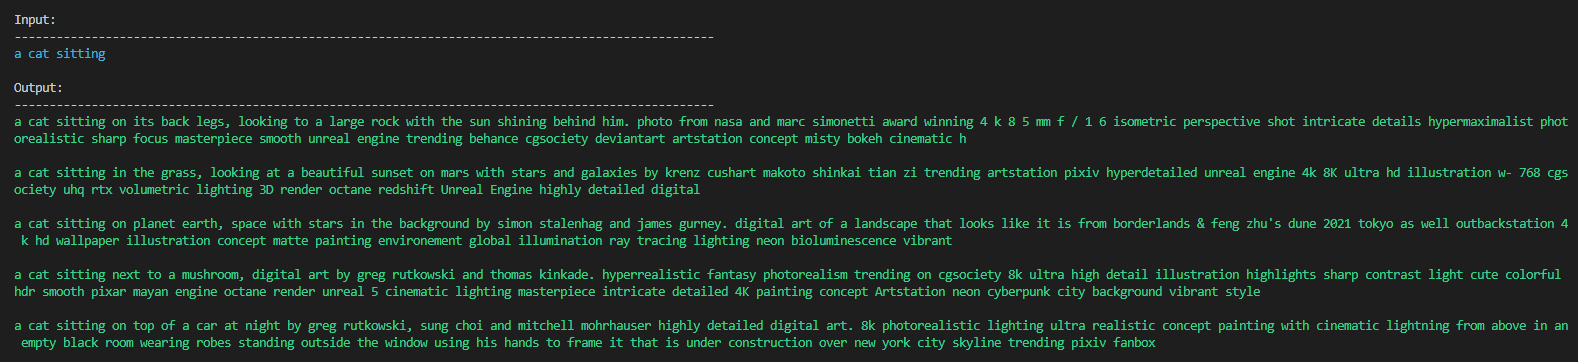
To bring back the commas, assign output without penalty_alpha and no_repeat_ngram_size:
output = model.generate(input_ids, do_sample=True, temperature=temperature, top_k=top_k, max_length=max_length, num_return_sequences=num_return_sequences, repetition_penalty=repitition_penalty, early_stopping=True)