
Downloads · 30 days
8
22% of all-time downloads
EmbeddingStudio/query-parser-saiga-mistral-7b-lora
query-parser-saiga-mistral-7b-lora is a text generation model from EmbeddingStudio. Use it when you need the model to write or continue text. It is set up for peft. The card lists the license as apache-2.0.
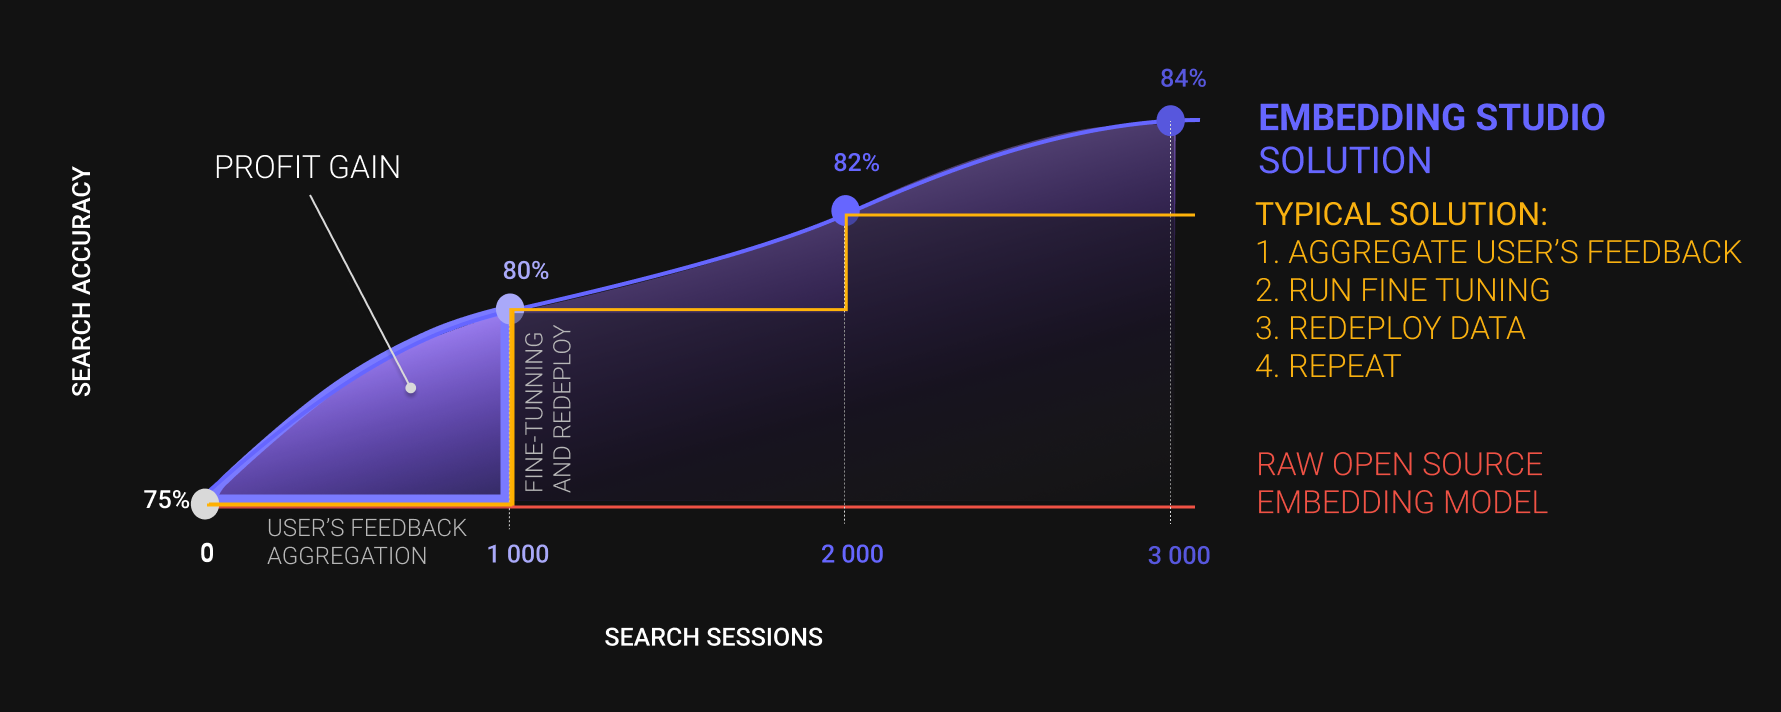
EmbeddingStudio is the open-source framework, that allows you transform a joint "Embedding Model + Vector DB" into a full-cycle search engine: collect clickstream - improve search experience- adapt embedding model and…
Downloads · 30 days
8
22% of all-time downloads
All-time downloads
36
Public
Repo size
55.1 MB
Likes
1
Public
Click a slice to open those files.
.safetensors54.6 MB · 99%
From the Hugging Face model README
EmbeddingStudio is the open-source framework, that allows you transform a joint "Embedding Model + Vector DB" into a full-cycle search engine: collect clickstream -> improve search experience-> adapt embedding model and repeat out of the box.
It's a highly rare case when a company will use unstructured search as is. And by searching brick red houses san francisco area for april
user definitely wants to find some houses in San Francisco for a month-long rent in April, and then maybe brick-red houses.
Unfortunately, for the 15th January 2024 there is no such accurate embedding model. So, companies need to mix structured and unstructured search.
The very first step of mixing it - to parse a search query. Usual approaches are:
It takes some time to do, but at the end you can get controllable and very accurate query parser.
EmbeddingStudio team decided to dive into LLM instruct fine-tuning for Zero-Shot query parsing task
to close the first gap while a company doesn't have any rules and data being collected, or even eliminate exhausted rules implementation, but in the future.
The main idea is to align an LLM to being to parse short search queries knowing just a company market and a schema of search filters. Moreover, being oriented on applied NLP,
we are trying to serve only light-weight LLMs a.k.a not heavier than 7B parameters.
This is only IlyaGusev/saiga_mistral_7b_lora aligned to follow instructions like:
<s>system: Эксперт по разбору поисковых запросов</s>
<s>user: Преобразование запросов в JSON, соответствие схеме, обеспечение правильного написания.
Категория: Mobile App Development
Схема: ```[{"Name": "Project-Budget", "Representations": [{"Name": "Budget-in-USD", "Type": "float", "Examples": [1000.0, 5000.0, 10000.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}, {"Name": "Budget-in-EUR", "Type": "float", "Examples": [850.0, 4250.0, 8500.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}, {"Name": "Budget-in-JPY", "Type": "float", "Examples": [110000.0, 550000.0, 1100000.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}, {"Name": "Budget-in-AUD", "Type": "float", "Examples": [1300.0, 6500.0, 13000.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}]}, {"Name": "Project-Duration", "Representations": [{"Name": "Duration-in-Minutes", "Type": "int", "Examples": [43200, 259200, 525600, 5, 5, 5]}]}, {"Name": "Project-End-Date", "Representations": [{"Name": "Day-Month-Year", "Type": "str", "Examples": ["01 January 2022", "15 February 2023", "31 December 2024", "01 января 2022 года", "15 февраля 2023 года", "31 декабря 2024"], "Pattern": ["dd Month YYYY", "дд Месяц ГГГГ"]}]}, {"Name": "Project-Start-Date", "Representations": [{"Name": "Day-Month-Year", "Type": "str", "Examples": ["01 January 2022", "15 February 2023", "31 December 2024", "01 января 2022 года", "15 февраля 2023 года", "31 декабря 2024"], "Pattern": ["dd Month YYYY", "дд Месяц ГГГГ"]}, {"Name": "Month-Day-Year", "Type": "str", "Examples": ["January 01 2022", "February 15 2023", "December 31 2024", "01 января 2022 года", "15 февраля 2023", "31 декабря 2024"], "Pattern": ["Month dd YYYY", "Месяц dd ГГГГ"]}, {"Name": "Month-Day-Year", "Type": "str", "Examples": ["01-01-2022", "02-15-2023", "12-31-2024", "01.01.2022", "15-02-2023", "31-12-2024"], "Pattern": ["mm-dd-YYYY", "mm-dd-YYYY"]}]}]```
Запрос: приложение для новогодней акции, дедлайн 31 декабря</s>
<s>bot:
[{"Value": "приложение для новогодней акции, дедлайн 31 декабря", "Name": "Correct"}, {"Name": "Project-End-Date.Day-Month-Year", "Value": "31 декабря текущего года"}]</s>
Important: Additionally, we are trying to fine-tune the Large Language Model (LLM) to not only parse unstructured search queries but also to correct spelling.
max_seq_length = 2048Disclaimer: As a small startup, this direction forms a part of our Minimum Viable Product (MVP). It's more of an attempt to test the 'product-market fit' rather than a well-structured scientific endeavor. Once we check it and go with a round, we definitely will:
We acknowledge the complexity involved in utilizing Large Language Models, particularly in the context
of Zero-Shot search query parsing and AI Alignment. Given the intricate nature of this technology, we emphasize the importance of rigorous verification.
Until our work is thoroughly reviewed, we recommend being cautious and critical of the results.
We strongly recommend only the direct usage of this fine-tuned version of IlyaGusev/saiga_mistral_7b_lora:
For any other needs the behaviour of the model in unpredictable, please utilize the IlyaGusev/saiga_mistral_7b_lora or fine-tune your own.
<s>system: Эксперт по разбору поисковых запросов</s>
<s>user: Преобразование запросов в JSON, соответствие схеме, обеспечение правильного написания.
Категория: {your_company_category}
Схема: ```{filters_schema}```
Запрос: {query}
<s>bot:
Filters schema is JSON-readable line in the format (we highly recommend you to use it): List of filters (dict):
Example:
[{"Name": "Customer_Ratings", "Representations": [{"Name": "Exact_Rating", "Type": "float", "Examples": [4.5, 3.2, 5.0, "4.5", "Unstructured"]}, {"Name": "Minimum_Rating", "Type": "float", "Examples": [4.0, 3.0, 5.0, "4.5"]}, {"Name": "Star_Rating", "Type": "int", "Examples": [4, 3, 5], "Enum": [1, 2, 3, 4, 5]}]}, {"Name": "Date", "Representations": [{"Name": "Day_Month_Year", "Type": "str", "Examples": ["01.01.2024", "15.06.2023", "31.12.2022", "25.12.2021", "20.07.2024", "15.06.2023"], "Pattern": "dd.mm.YYYY"}, {"Name": "Day_Name", "Type": "str", "Examples": ["Понедельник", "Вторник", "пн", "вт", "Среда", "Четверг"], "Enum": ["Понедельник", "Вторник", "Среда", "Четверг", "Пятница", "Суббота", "Воскресенье"]}]}, {"Name": "Date_Period", "Representations": [{"Name": "Specific_Period", "Type": "str", "Examples": ["01.01.2024 - 31.01.2024", "01.06.2023 - 30.06.2023", "01.12.2022 - 31.12.2022"], "Pattern": "dd.mm.YYYY - dd.mm.YYYY"}, {"Name": "Month", "Type": "str", "Examples": ["Январь", "Янв", "Декабрь"], "Enum": ["Январь", "Февраль", "Март", "Апрель", "Май", "Июнь", "Июль", "Август", "Сентябрь", "Октябрь", "Ноябрь", "Декабрь"]}, {"Name": "Quarter", "Type": "str", "Examples": ["Q1", "Q2", "Q3"], "Enum": ["Q1", "Q2", "Q3", "Q4"]}, {"Name": "Season", "Type": "str", "Examples": ["Winter", "Summer", "Autumn"], "Enum": ["Winter", "Spring", "Summer", "Autumn"]}]}, {"Name": "Destination_Country", "Representations": [{"Name": "Country_Name", "Type": "str", "Examples": ["United States", "Germany", "China"]}, {"Name": "Country_Code", "Type": "str", "Examples": ["US", "DE", "CN"]}, {"Name": "Country_Abbreviation", "Type": "str", "Examples": ["USA", "GER", "CHN"]}]}]
As the result, response will be JSON-readable line in the format:
[{"Value": "Corrected search phrase", "Name": "Correct"}, {"Name": "filter-name.representation", "Value": "some-value"}]
Field and representation names will be aligned with the provided schema. Example:
[{"Value": "приложение для новогодней акции, дедлайн 31 декабря", "Name": "Correct"}, {"Name": "Project-End-Date.Day-Month-Year", "Value": "31 декабря текущего года"}]
Used for fine-tuning system phrases:
[
    "Эксперт по разбору поисковых запросов",
    "Мастер анализа поисковых запросов",
    "Первоклассный интерпретатор поисковых запросов",
    "Продвинутый декодер поисковых запросов",
    "Гений разбора поисковых запросов",
    "Волшебник разбора поисковых запросов",
    "Непревзойденный механизм разбора запросов",
    "Виртуоз разбора поисковых запросов",
    "Маэстро разбора запросов",
]
Used for fine-tuning instruction phrases:
[
    "Преобразование запросов в JSON, соответствие схеме, обеспечение правильного написания.",
    "Анализ и структурирование запросов в JSON, поддержание схемы, проверка орфографии.",
    "Организация запросов в JSON, соблюдение схемы, верификация орфографии.",
    "Декодирование запросов в JSON, следование схеме, исправление орфографии.",
    "Разбор запросов в JSON, соответствие схеме, правильное написание.",
    "Преобразование запросов в структурированный JSON, соответствие схеме и орфографии.",
    "Реструктуризация запросов в JSON, соответствие схеме, точное написание.",
    "Перестановка запросов в JSON, строгое соблюдение схемы, поддержание орфографии.",
    "Гармонизация запросов с JSON схемой, обеспечение точности написания.",
    "Эффективное преобразование запросов в JSON, соответствие схеме, правильная орфография."
]
import json

from json import JSONDecodeError

from transformers import AutoTokenizer, AutoModelForCausalLM

from transformers import StoppingCriteria

class EosListStoppingCriteria(StoppingCriteria):
    def __init__(self, eos_sequence = [2]):
        self.eos_sequence = eos_sequence

    def __call__(self, input_ids: torch.LongTensor, scores: torch.FloatTensor, **kwargs) -> bool:
        last_ids = input_ids[:,-len(self.eos_sequence):].tolist()
        return self.eos_sequence in last_ids

INSTRUCTION_TEMPLATE = """<s>system: Эксперт по разбору поисковых запросов</s>
<s>user: Преобразование запросов в JSON, соответствие схеме, обеспечение правильного написания.
Категория: {0}
Схема: ```{1}```
Запрос: {2}
<s>bot:
"""


def parse(
        query: str,
        company_category: str,
        filter_schema: dict,
        model: AutoModelForCausalLM,
        tokenizer: AutoTokenizer
):
    input_text = INSTRUCTION_TEMPLATE.format(
      company_category,
      json.dumps(filter_schema),
      query
    )
    input_ids = tokenizer.encode(input_text, return_tensors='pt')

    # Generating text
    output = model.generate(input_ids.to('cuda'),
                            max_new_tokens=1024,
                            do_sample=True,
                            temperature=0.05
    )
    try:
        generated = tokenizer.decode(output[0]).replace('<s> ', '<s>').split('<s>bot:\n')[-1].replace('</s>', '').strip()
        parsed = json.loads(generated)
    except JSONDecodeError as e:
        parsed = dict()

    return parsed
Again, this model was fine-tuned for following the zero-shot query parsing instructions. So, all ethical biases are inherited by the original model.
Model was fine-tuned to be able to work with the unknown company domain and filters schema. But, can be better with the training company categories:
Artificial Intelligence and Machine Learning, Automotive, Automotive Dealerships, Banking Services, Books and Media, Cloud Computing Services, Cloud-based Development Environments, Collaborative Development Environments, Commercial Real Estate, Continuous Integration/Continuous Deployment, Credit Services, Customer Support Services, Customer Support and Feedback, Cybersecurity Software, Data Analytics and Business Intelligence, Dating Apps, Digital and Mobile Banking, Documentation and Knowledge Sharing, E-commerce Platforms, Eco-Friendly and Sustainable Properties, Educational Institutions, Electronics, Enterprise Software Development, Entertainment and Media Platforms, Event Planning Services, Fashion and Apparel, Financial Planning and Advisory, Food and Grocery, Game Development, Government Services, Health and Beauty, Healthcare Providers, Home and Garden, Image Stock Platforms, Insurance Services, International Real Estate, Internet of Things (IoT) Development, Investment Services, Issue Tracking and Bug Reporting, Job Recruitment Agencies, Land Sales and Acquisitions, Legal Services, Logistics and Supply Chain Management, Luxury and High-End Properties, Market Research Firms, Mobile App Development, Mortgage and Real Estate Services, Payment Processing, Pet Supplies, Professional Social Networks, Project Management Tools, Property Management, Real Estate Consulting, Real Estate Development, Real Estate Investment, Residential Real Estate, Restaurants and Food Delivery Services, Retail Stores (Online and Offline), Risk Management and Compliance, Social Networks, Sports and Outdoors, Task and Time Management, Taxation Services, Team Communication and Chat Tools, Telecommunication Companies, Toys and Games, Travel and Booking Agencies, Travelers and Consumers, User Interface/User Experience Design, Version Control Systems, Video Hosting and Portals, Web Development```
Known limitations:
1-2 -> 1 - 2.5 -> 5 years.<>= and theirs HTML versions <, >, &eq;..0 for floats and integers.0 or remove 0 for integers with a char postfix: 10M -> 1m.list of positions exactly 7 openings available result can be
{'Name': 'Job_Type.Exact_Match', 'Value': 'Full Time'}.The list will be extended in the future.
Use the code below to get started with the model.
MODEL_ID = 'EmbeddingStudio/query-parser-saiga-mistral-7b-lora'
Initialize tokenizer:
from transformers import AutoTokenizer

tokenizer = AutoTokenizer.from_pretrained(
    MODEL_ID,
    trust_remote_code=True,
    add_prefix_space=True,
    use_fast=False,
)
Initialize model:
import torch

from peft import LoraConfig
from transformers import AutoModelForCausalLM, BitsAndBytesConfig

peft_config = LoraConfig(
      lora_alpha=16,
      lora_dropout=0.1,
      r=64,
      bias="none",
      task_type="CAUSAL_LM",
)

bnb_config = BitsAndBytesConfig(
    load_in_4bit=True,
    load_4bit_use_double_quant=True,
    bnb_4bit_quant_type="nf4",
    bnb_4bit_compute_dtype=torch.bfloat16,
)

device_map = {"": 0}

model = AutoModelForCausalLM.from_pretrained(
  MODEL_ID,
  quantization_config=bnb_config,
  device_map=device_map,
  torch_dtype=torch.float16
)
Use for parsing:
import json

from json import JSONDecodeError

from transformers import StoppingCriteria

class EosListStoppingCriteria(StoppingCriteria):
    def __init__(self, eos_sequence = [2]):
        self.eos_sequence = eos_sequence

    def __call__(self, input_ids: torch.LongTensor, scores: torch.FloatTensor, **kwargs) -> bool:
        last_ids = input_ids[:,-len(self.eos_sequence):].tolist()
        return self.eos_sequence in last_ids

INSTRUCTION_TEMPLATE = """<s>system: Эксперт по разбору поисковых запросов</s>
<s>user: Преобразование запросов в JSON, соответствие схеме, обеспечение правильного написания.
Категория: {0}
Схема: ```{1}```
Запрос: {2}
<s>bot:
"""


def parse(
        query: str,
        company_category: str,
        filter_schema: dict,
        model: AutoModelForCausalLM,
        tokenizer: AutoTokenizer
):
    input_text = INSTRUCTION_TEMPLATE.format(
      company_category,
      json.dumps(filter_schema),
      query
    )
    input_ids = tokenizer.encode(input_text, return_tensors='pt')

    # Generating text
    output = model.generate(input_ids.to('cuda'),
                            max_new_tokens=1024,
                            do_sample=True,
                            temperature=0.05
    )
    try:
        generated = tokenizer.decode(output[0]).replace('<s> ', '<s>').split('<s>bot:\n')[-1].replace('</s>', '').strip()
        parsed = json.loads(generated)
    except JSONDecodeError as e:
        parsed = dict()

    return parsed

category = 'Mobile App Development'
query = 'приложение для новогодней акции, дедлайн 31 декабря'
schema = [{"Name": "Project-Budget", "Representations": [{"Name": "Budget-in-USD", "Type": "float", "Examples": [1000.0, 5000.0, 10000.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}, {"Name": "Budget-in-EUR", "Type": "float", "Examples": [850.0, 4250.0, 8500.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}, {"Name": "Budget-in-JPY", "Type": "float", "Examples": [110000.0, 550000.0, 1100000.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}, {"Name": "Budget-in-AUD", "Type": "float", "Examples": [1300.0, 6500.0, 13000.0, "The project is currently on hold", "The project is currently on hold", "The project is currently on hold"]}]}, {"Name": "Project-Duration", "Representations": [{"Name": "Duration-in-Minutes", "Type": "int", "Examples": [43200, 259200, 525600, 5, 5, 5]}]}, {"Name": "Project-End-Date", "Representations": [{"Name": "Day-Month-Year", "Type": "str", "Examples": ["01 January 2022", "15 February 2023", "31 December 2024", "01 января 2022 года", "15 февраля 2023 года", "31 декабря 2024"], "Pattern": ["dd Month YYYY", "дд Месяц ГГГГ"]}]}, {"Name": "Project-Start-Date", "Representations": [{"Name": "Day-Month-Year", "Type": "str", "Examples": ["01 January 2022", "15 February 2023", "31 December 2024", "01 января 2022 года", "15 февраля 2023 года", "31 декабря 2024"], "Pattern": ["dd Month YYYY", "дд Месяц ГГГГ"]}, {"Name": "Month-Day-Year", "Type": "str", "Examples": ["January 01 2022", "February 15 2023", "December 31 2024", "01 января 2022 года", "15 февраля 2023", "31 декабря 2024"], "Pattern": ["Month dd YYYY", "Месяц dd ГГГГ"]}, {"Name": "Month-Day-Year", "Type": "str", "Examples": ["01-01-2022", "02-15-2023", "12-31-2024", "01.01.2022", "15-02-2023", "31-12-2024"], "Pattern": ["mm-dd-YYYY", "mm-dd-YYYY"]}]}]

output = parse(query, category, schema)
print(output)

# [out]: [{"Value": "приложение для новогодней акции, дедлайн 31 декабря", "Name": "Correct"}, {"Name": "Project-End-Date.Day-Month-Year", "Value": "31 декабря текущего года"}]
We used synthetically generated query parsing instructions:
Warning: EmbeddingStudio team aware you that generated queries weren't enough curated, and will be curated later once we finish our product market fit stage
As we are trying to fine-tune LLM to follow zero-shot query parsing instructions, so we want to test:
For these purposes we:
Automotive, Educational Institutions, Enterprise Software Development, Payment Processing, Professional Social Networks.We used GPT-4 Turbo to generate several possible filters for 63 company categroies. For each filter we also generated some possible representations. For examples filter Date can be represented as dd/mm/YYYY, YYYY-mm-dd, as words 2024 Янв 17, etc.
We also used GPT-4 Turbo for generation of search queries and theirs parsed version. Main principles were:
For the generation instructions we used following ideas:
Zero-Shot query parser should be schema agnostic. Cases like snake_case, CamelCase, http-headers-like should not ruin generation process.
Zero-Shot query parser should be spelling errors insensitive.
Training instructions should be in the following order:
So LLM can be used in the following way: just generate embedding of category -> schema part, so inference will be faster.
We assume, that schema agnostic termin means something wider, like to be able to work not only with JSONs, but also with HTML, Markdown, YAML, etc. We are working on it.
So, what was our approach as an attempt to achieve these abilities:
Correct, which contains a corrected version of a search query.Warning: EmbeddingStudio team ask you to curate datasets on your own precisely.
All details in Training Hyperparameters
The preprocessing steps are not detailed in the provided code. Typically, preprocessing involves tokenization, normalization, data augmentation, and handling of special tokens. In this training setup, the tokenizer was configured with add_prefix_space=True and use_fast=False, which might indicate special considerations for tokenizing certain languages or text formats.
| Hyperparameter | Value | Description |
|---|---|---|
| Training Regime | Mixed Precision (bfloat16) | Utilizes bfloat16 for efficient memory usage and training speed. |
| Model Configuration | Causal Language Model | Incorporates LoRA (Low-Rank Adaptation) for training efficiency. |
| Quantization Configuration | Bits and Bytes (BnB) | Uses settings like load_in_4bit and bnb_4bit_quant_type for model quantization. |
| Training Environment | CUDA-enabled Device | Indicates GPU acceleration for training. |
| Learning Rate | 0.003 | Determines the step size at each iteration while moving toward a minimum of a loss function. |
| Warmup Ratio | 0.03 | Fraction of total training steps used for the learning rate warmup. |
| Optimizer | Paged AdamW (32-bit) | Optimizes the training process with efficient memory usage. |
| Gradient Accumulation Steps | 2 | Reduces memory consumption and allows for larger effective batch sizes. |
| Max Grad Norm | 0.3 | Maximum norm for the gradients. |
| LR Scheduler Type | Cosine | Specifies the learning rate schedule. |
| PEFT Configurations | LoraConfig | Details like lora_alpha, lora_dropout, and r for LoRA adaptations. |
| Training Dataset Segmentation | Train and Test Sets | Segmentation of the dataset for training and evaluation. |
| Max Sequence Length | 1024 | Maximum length of the input sequences. |
All information is provided in Training Data section.
Our zero-shot search query parsing model is designed to extract structured information from unstructured search queries with high precision. The primary metric for evaluating our model's performance is the True Positive (TP) rate, which is assessed using a specialized token-wise Levenshtein distance. This approach is aligned with our goal to achieve semantic accuracy in parsing user queries.
levenshtein_tokenwise function, which calculates the distance between predicted and actual key-value pairs at a token level. We consider a Levenshtein distance of 0.25 or less as acceptable for matching.| Category | Recall | Precision | F1 | Accuracy |
|---|---|---|---|---|
| Educational Institutions [+] | 0.74 | 0.71 | 0.73 | 0.57 |
| Enterprise Software Development [+] | 0.80 | 0.73 | 0.76 | 0.62 |
| Professional Social Networks [+] | 0.82 | 0.72 | 0.76 | 0.62 |
| Automotive [+] | 0.77 | 0.64 | 0.70 | 0.54 |
| Payment Processing [+] | 0.80 | 0.73 | 0.76 | 0.62 |
| Continuous Integration/Continuous Deployment | 0.85 | 0.83 | 0.84 | 0.72 |
| Digital and Mobile Banking | 0.79 | 0.83 | 0.81 | 0.68 |
| Web Development | 0.93 | 0.73 | 0.82 | 0.69 |
| Banking Services | 0.74 | 0.79 | 0.76 | 0.62 |
| Customer Support and Feedback | 0.88 | 0.93 | 0.90 | 0.83 |
| Video Hosting and Portals | 0.86 | 0.88 | 0.87 | 0.77 |
| Cloud Computing Services | 0.72 | 0.62 | 0.67 | 0.50 |
| Health and Beauty | 0.78 | 0.81 | 0.79 | 0.66 |
| Game Development | 0.65 | 0.62 | 0.63 | 0.46 |
| Artificial Intelligence and Machine Learning | 0.80 | 0.83 | 0.82 | 0.69 |
| Social Networks | 0.92 | 0.82 | 0.87 | 0.76 |
| Mobile App Development | 0.89 | 0.88 | 0.88 | 0.79 |
| Customer Support Services | 0.81 | 0.80 | 0.81 | 0.68 |
| Commercial Real Estate | 0.91 | 0.80 | 0.85 | 0.74 |
| Cloud-based Development Environments | 0.90 | 0.82 | 0.86 | 0.75 |
| Event Planning Services | 0.92 | 0.69 | 0.79 | 0.65 |
| Project Management Tools | 0.88 | 0.83 | 0.86 | 0.75 |
| Version Control Systems | 0.70 | 0.67 | 0.69 | 0.52 |
| Automotive Dealerships | 0.60 | 0.67 | 0.63 | 0.46 |
| Insurance Services | 0.81 | 0.60 | 0.69 | 0.53 |
| Telecommunication Companies | 0.68 | 0.73 | 0.71 | 0.55 |
| Image Stock Platforms | 0.95 | 0.91 | 0.93 | 0.87 |
| Toys and Games | 0.79 | 0.79 | 0.79 | 0.65 |
| Books and Media | 0.74 | 0.74 | 0.74 | 0.58 |
| Residential Real Estate | 0.78 | 0.63 | 0.69 | 0.53 |
| Legal Services | 0.91 | 0.83 | 0.87 | 0.76 |
| Job Recruitment Agencies | 0.84 | 0.73 | 0.78 | 0.64 |
| International Real Estate | 0.97 | 0.84 | 0.90 | 0.81 |
| Dating Apps | 0.92 | 0.84 | 0.88 | 0.79 |
| Home and Garden | 0.70 | 0.59 | 0.64 | 0.47 |
| User Interface/User Experience Design | 0.84 | 0.73 | 0.78 | 0.64 |
| Logistics and Supply Chain Management | 0.78 | 0.69 | 0.73 | 0.57 |
| Sports and Outdoors | 0.80 | 0.72 | 0.76 | 0.61 |
| Team Communication and Chat Tools | 0.71 | 0.61 | 0.66 | 0.49 |
| Mortgage and Real Estate Services | 0.77 | 0.67 | 0.71 | 0.55 |
| Taxation Services | 0.67 | 0.64 | 0.66 | 0.49 |
| Electronics | 0.79 | 0.53 | 0.63 | 0.47 |
| Travelers and Consumers | 0.91 | 0.86 | 0.89 | 0.80 |
| Financial Planning and Advisory | 0.90 | 0.85 | 0.88 | 0.78 |
| Real Estate Consulting | 0.77 | 0.69 | 0.73 | 0.57 |
| Property Management | 0.86 | 0.72 | 0.79 | 0.65 |
| Government Services | 0.96 | 0.93 | 0.94 | 0.89 |
| E-commerce Platforms | 0.93 | 0.89 | 0.91 | 0.83 |
| Data Analytics and Business Intelligence | 0.96 | 0.88 | 0.92 | 0.85 |
| Documentation and Knowledge Sharing | 0.84 | 0.77 | 0.80 | 0.67 |
| Real Estate Investment | 0.79 | 0.73 | 0.76 | 0.62 |
| Eco-Friendly and Sustainable Properties | 0.85 | 0.72 | 0.78 | 0.64 |
| Task and Time Management | 0.91 | 0.87 | 0.89 | 0.80 |
| Issue Tracking and Bug Reporting | 0.70 | 0.57 | 0.63 | 0.46 |
| Restaurants and Food Delivery Services | 0.80 | 0.72 | 0.76 | 0.61 |
| Luxury and High-End Properties | 0.93 | 0.77 | 0.84 | 0.73 |
| Food and Grocery | 0.85 | 0.60 | 0.70 | 0.54 |
| Entertainment and Media Platforms | 0.80 | 0.85 | 0.83 | 0.70 |
| Real Estate Development | 0.86 | 0.74 | 0.79 | 0.66 |
| Market Research Firms | 0.90 | 0.82 | 0.86 | 0.75 |
| Investment Services | 0.76 | 0.86 | 0.81 | 0.67 |
| Collaborative Development Environments | 0.72 | 0.62 | 0.66 | 0.50 |
| Retail Stores (Online and Offline) | 0.78 | 0.71 | 0.75 | 0.60 |
| Fashion and Apparel | 0.68 | 0.72 | 0.70 | 0.54 |
| Healthcare Providers | 0.68 | 0.61 | 0.64 | 0.48 |
| Travel and Booking Agencies | 0.80 | 0.72 | 0.76 | 0.61 |
| Credit Services | 0.94 | 0.94 | 0.94 | 0.88 |
| Land Sales and Acquisitions | 0.90 | 0.76 | 0.83 | 0.70 |
| Internet of Things (IoT) Development | 0.90 | 0.92 | 0.91 | 0.83 |
| Risk Management and Compliance | 0.74 | 0.77 | 0.75 | 0.60 |
| Pet Supplies | 0.85 | 0.70 | 0.77 | 0.62 |
| Aggregate | 0.82 | 0.75 | 0.78 | 0.65 |
| Category | Recall | Precision | F1 | Accuracy |
|---|---|---|---|---|
| Educational Institutions [+] | 0.74 | 0.71 | 0.73 | 0.57 |
| Enterprise Software Development [+] | 0.80 | 0.73 | 0.76 | 0.62 |
| Professional Social Networks [+] | 0.82 | 0.72 | 0.76 | 0.62 |
| Automotive [+] | 0.77 | 0.64 | 0.70 | 0.54 |
| Payment Processing [+] | 0.80 | 0.73 | 0.76 | 0.62 |
| Aggregate | 0.78 | 0.71 | 0.74 | 0.59 |
Carbon emissions can be estimated using the Machine Learning Impact calculator presented in Lacoste et al. (2019).
load_in_4bit and bnb_4bit_quant_type for model quantization.[To be added]
[To be added]
EmbeddingStudio is an innovative open-source framework designed to seamlessly convert a combined "Embedding Model + Vector DB" into a comprehensive search engine. With built-in functionalities for clickstream collection, continuous improvement of search experiences, and automatic adaptation of the embedding model, it offers an out-of-the-box solution for a full-cycle search engine.
(*) - features in development
EmbeddingStudio is highly customizable, so you can bring your own:
For more details visit GitHub Repo.