
Downloads · 30 days
40
1% of all-time downloads
DiscoResearch/Llama3-DiscoLeo-Instruct-8B-32k-v0.1
Llama3-DiscoLeo-Instruct-8B-32k-v0.1 is a text generation model from DiscoResearch. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama3.
DiscoResearch/Llama3-DiscoLeo-Instruct-8B-32k-v0.1 is the result of a joint effort between DiscoResearch and Occiglot with support from the DFKI (German Research Center for Artificial Intelligence) and hessian.Ai.
Downloads · 30 days
40
1% of all-time downloads
All-time downloads
5.1K
Public
Parameters
8B
16.1 GB on disk
Likes
14
Public
Click a slice to open those files.
.safetensors16.1 GB · 100%
From the Hugging Face model README
DiscoResearch/Llama3-DiscoLeo-Instruct-8B-32k-v0.1 is the result of a joint effort between DiscoResearch and Occiglot with support from the DFKI (German Research Center for Artificial Intelligence) and hessian.Ai. Occiglot kindly handled data preprocessing, filtering, and deduplication as part of their latest dataset release, as well as sharing their compute allocation at hessian.Ai's 42 Supercomputer.
DiscoResearch/Llama3_DiscoLeo_Instruct_8B_32k_v0.1 is an instruction tuned version of our long-context Llama3-German-8B-32k. The base model was derived from Meta's Llama3-8B through continuous pretraining on 65 billion high-quality German tokens, similar to previous LeoLM or Occiglot models. For the long-context version we trained on an additional 100 million tokens at 32k context length, using a rope_theta value of 1.5e6 and a learning rate of 1.5e-5 with a batch size of 256*8192 and otherwise equal hyperparameters to the base model. We finetuned this checkpoint on the German Instruction dataset from DiscoResearch created by Jan-Philipp Harries and Daniel Auras (DiscoResearch, ellamind).
Llama3_DiscoLeo_Instruct_8B_32k_v0.1 uses the Llama-3 chat template, which can be easily used with transformer's chat templating. See below for a usage example.
The model was full-fintuned with axolotl on the hessian.Ai 42 with 32,768 context-length, learning rate 2e-5 and batch size of 16.
We evaluated the model using a suite of common English Benchmarks and their German counterparts with GermanBench.
In the below image and corresponding table, you can see the benchmark scores for the different instruct models compared to Metas instruct version. All checkpoints are available in this collection.
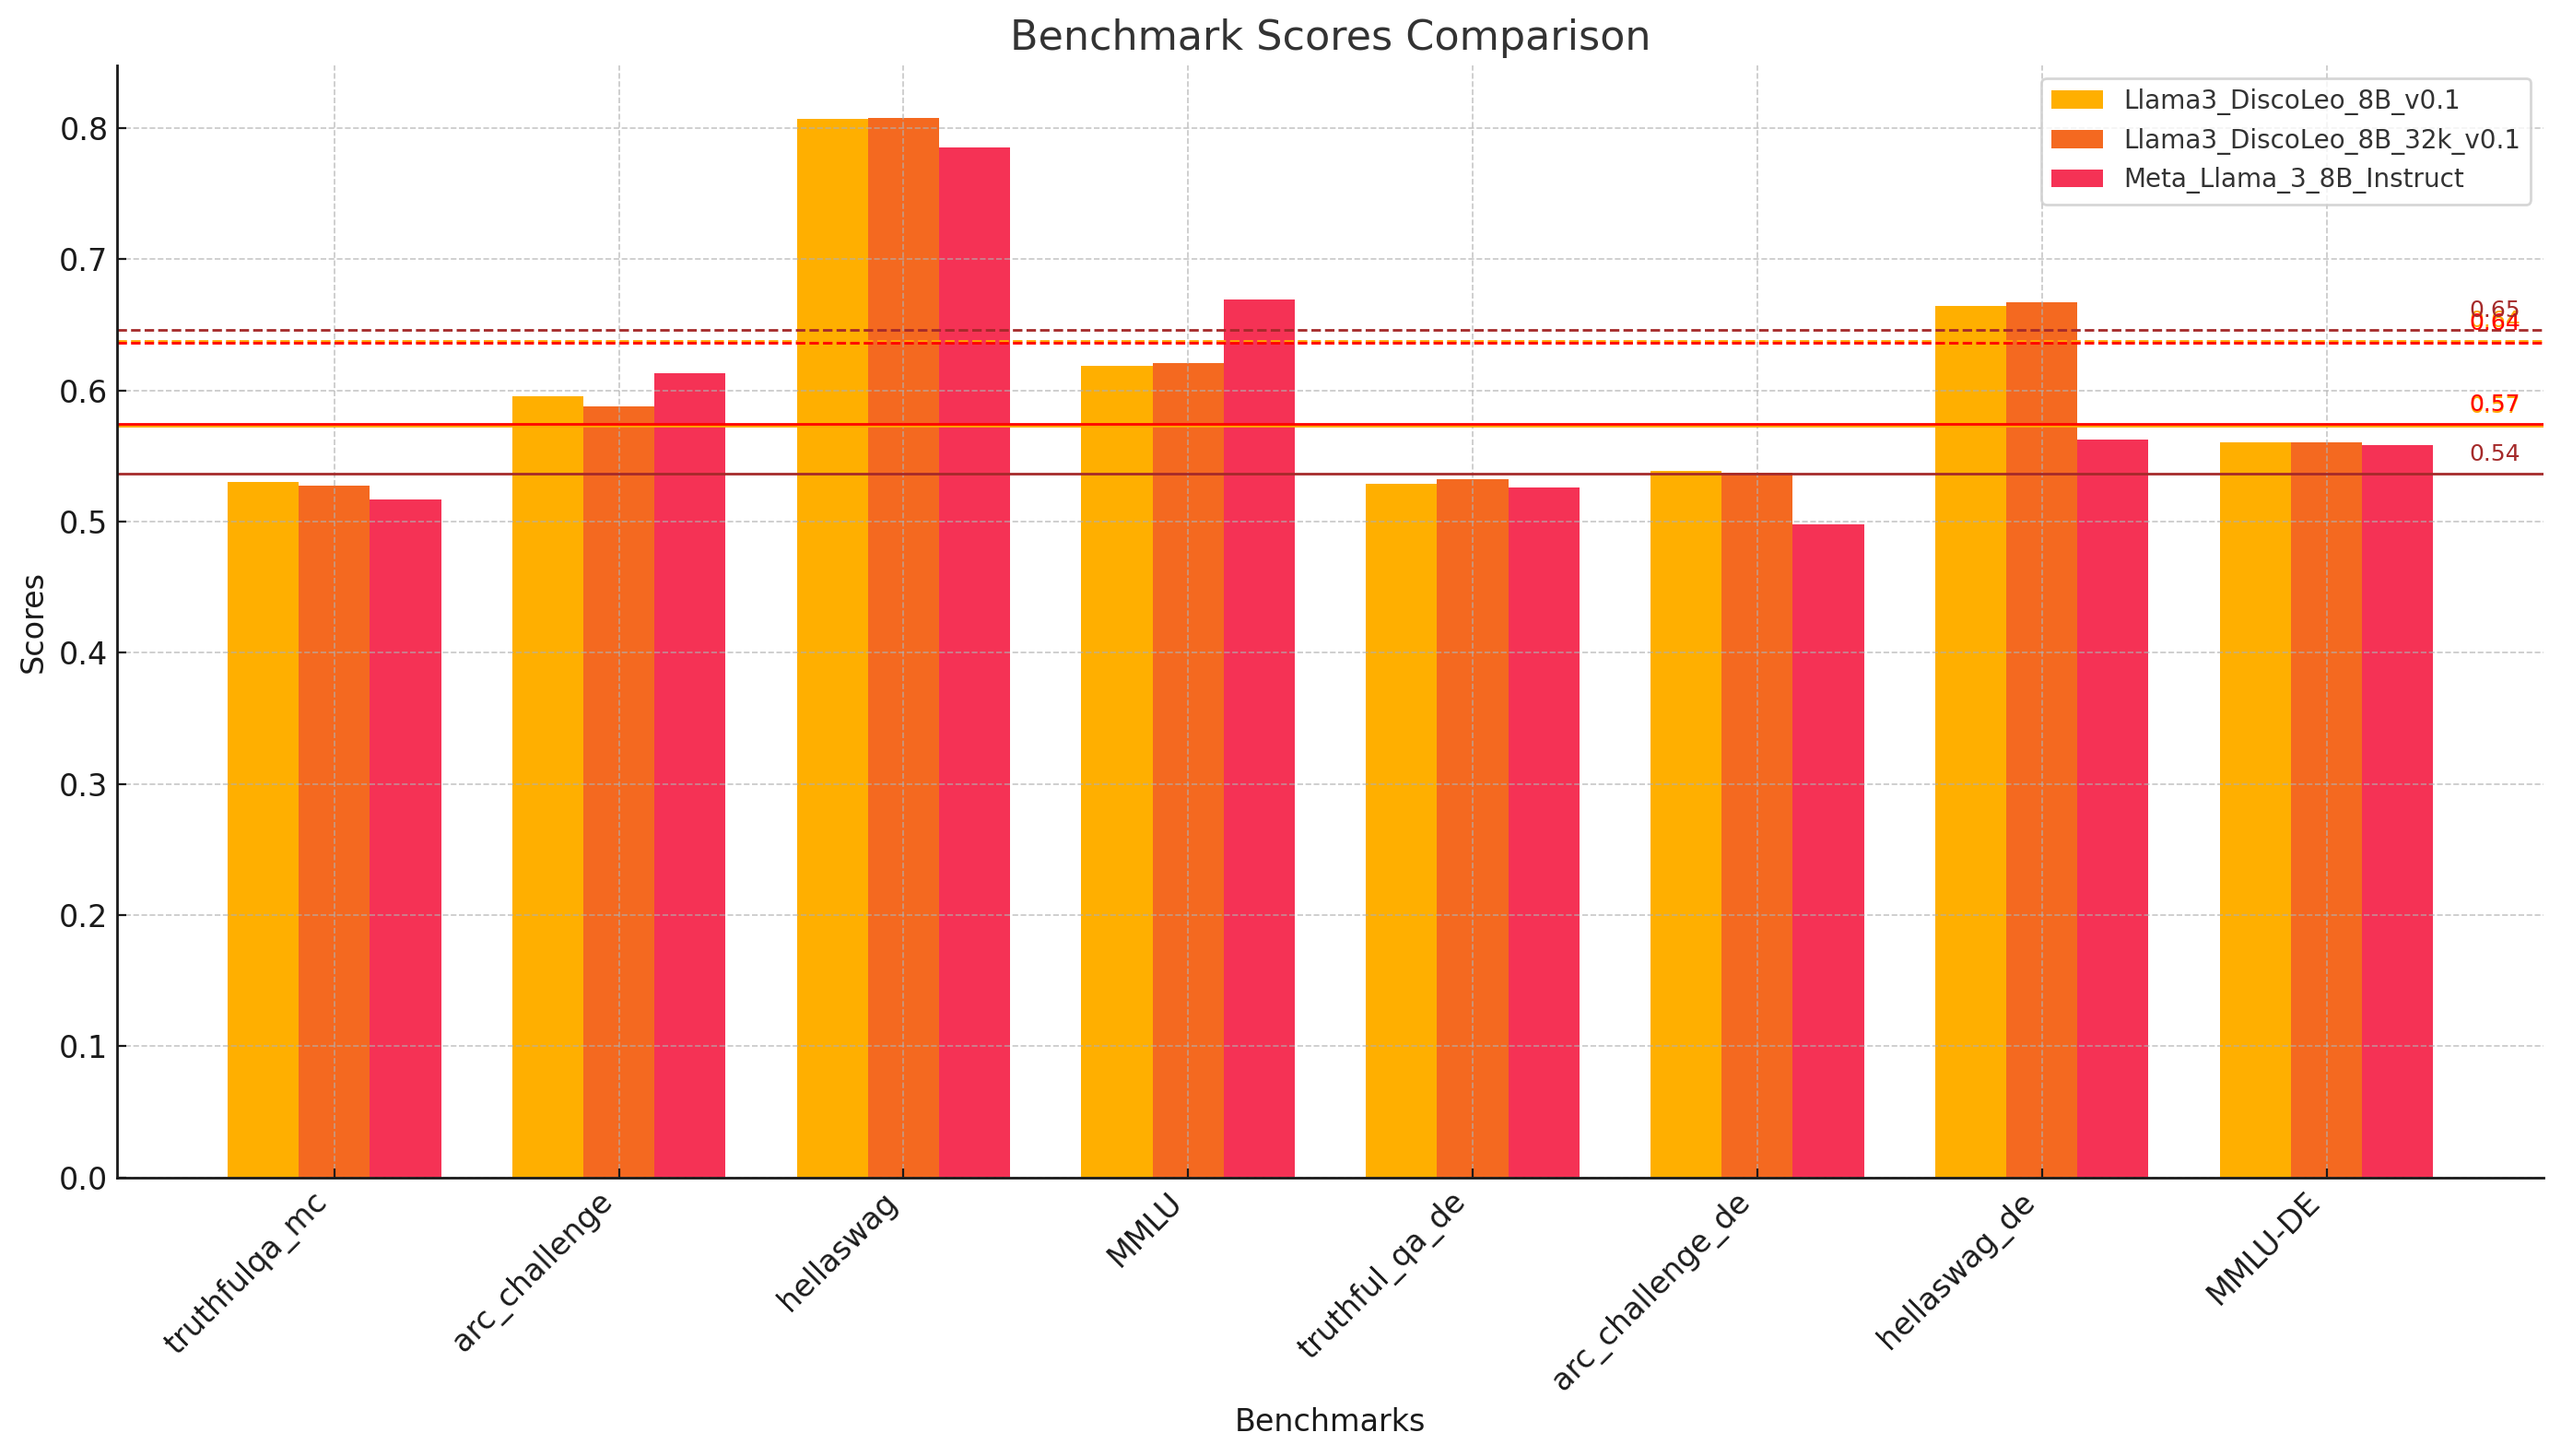
| Model | truthful_qa_de | truthfulqa_mc | arc_challenge | arc_challenge_de | hellaswag | hellaswag_de | MMLU | MMLU-DE | mean |
|---|---|---|---|---|---|---|---|---|---|
| meta-llama/Meta-Llama-3-8B-Instruct | 0.47498 | 0.43923 | 0.59642 | 0.47952 | 0.82025 | 0.60008 | 0.66658 | 0.53541 | 0.57656 |
| DiscoResearch/Llama3-German-8B | 0.49499 | 0.44838 | 0.55802 | 0.49829 | 0.79924 | 0.65395 | 0.62240 | 0.54413 | 0.57743 |
| DiscoResearch/Llama3-German-8B-32k | 0.48920 | 0.45138 | 0.54437 | 0.49232 | 0.79078 | 0.64310 | 0.58774 | 0.47971 | 0.55982 |
| DiscoResearch/Llama3-DiscoLeo-Instruct-8B-v0.1 | 0.53042 | 0.52867 | 0.59556 | 0.53839 | 0.80721 | 0.66440 | 0.61898 | 0.56053 | 0.60552 |
| DiscoResearch/Llama3-DiscoLeo-Instruct-8B-32k-v0.1 | 0.52749 | 0.53245 | 0.58788 | 0.53754 | 0.80770 | 0.66709 | 0.62123 | 0.56238 | 0.60547 |
We release DiscoLeo-8B in the following configurations:
DARE-TIES Merge with Llama3-InstructHere's how to use the model with transformers:
from transformers import AutoModelForCausalLM, AutoTokenizer
import torch

device="cuda"

model = AutoModelForCausalLM.from_pretrained(
    "DiscoResearch/Llama3-DiscoLeo-Instruct-8B-32k-v0.1",
    torch_dtype="auto",
    device_map="auto"
)
tokenizer = AutoTokenizer.from_pretrained("DiscoResearch/Llama3-DiscoLeo-Instruct-8B-32k-v0.1")

prompt = "Schreibe ein Essay über die Bedeutung der Energiewende für Deutschlands Wirtschaft"
messages = [
    {"role": "system", "content": "Du bist ein hilfreicher Assistent."},
    {"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True
)
model_inputs = tokenizer([text], return_tensors="pt").to(device)

generated_ids = model.generate(
    model_inputs.input_ids,
    max_new_tokens=512
)
generated_ids = [
    output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)
]

response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
The model was trained and evaluated by Björn Plüster (DiscoResearch, ellamind) with data preparation and project supervision by Manuel Brack (DFKI, TU-Darmstadt). Initial work on dataset collection and curation was performed by Malte Ostendorff and Pedro Ortiz Suarez. Instruction tuning was done with the DiscoLM German dataset created by Jan-Philipp Harries and Daniel Auras (DiscoResearch, ellamind). We extend our gratitude to LAION and friends, especially Christoph Schuhmann and Jenia Jitsev, for initiating this collaboration.
The model training was supported by a compute grant at the 42 supercomputer which is a central component in the development of hessian AI, the AI Innovation Lab (funded by the Hessian Ministry of Higher Education, Research and the Art (HMWK) & the Hessian Ministry of the Interior, for Security and Homeland Security (HMinD)) and the AI Service Centers (funded by the Federal Ministry of Education and Research (BMBF)). The curation of the training data is partially funded by the German Federal Ministry for Economic Affairs and Climate Action (BMWK) through the project OpenGPT-X (project no. 68GX21007D).