
Downloads · 30 days
3.3K
4% of all-time downloads
DavidAU/Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF
Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF is a image-text-to-text model from DavidAU. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. The card lists the license as apache-2.0.
<small<B style="font-family: 'Arial Black', sans-serif; font-weight: 900; color: f1c40f; text-decoration: none; text-shadow: 1px 1px 0 d35400, 2px 2px 0 d35400, 3px 3px 0 d35400, 4px 4px 0 d35400, 5px 5px 0 d35400, 6p…
Downloads · 30 days
3.3K
4% of all-time downloads
All-time downloads
85.5K
Public
Repo size
295 GB
Likes
54
Public
Click a slice to open those files.
.gguf209 GB · 100%
From the Hugging Face model README
<small><B style="font-family: 'Arial Black', sans-serif; font-weight: 900; color: #f1c40f; text-decoration: none; text-shadow: 1px 1px 0 #d35400, 2px 2px 0 #d35400, 3px 3px 0 #d35400, 4px 4px 0 #d35400, 5px 5px 0 #d35400, 6px 6px 7px rgba(0,0,0,0.4);">[DavidAU]</B> <a href="https://huggingface.co/DavidAU" target="_blank" style="padding-left:5px">FOLLOW</a> | <a href="https://huggingface.co/DavidAU" target="_blank">ALL MODELS</a> | <a href="https://huggingface.co/DavidAU/collections" target="_blank">COLLECTIONS</a> | <a href="https://huggingface.co/models?sort=trending&search=DavidAU" target="_blank">TRENDING</a> | <a href="https://huggingface.co/DavidAU/support" target="_blank">FAQs</a> | <a href="https://huggingface.co/DavidAU/support" target="_blank">SUPPORT</a> | <a href="https://buymeacoffee.com/davidbelton" target="_blank">Buy Me A Coffee (😁)</a></small>
<small><b><font color="red">Important:</font></b> This is the first 40B fine tune that reaches "closed source" (IE OpenAI, Claude) level of intelligence in both 8 bit and 4 bit. This repo contains both "regular" and "MTP" Neo MAX Imatrix GGUF quants. This model is composed from multiple Qwen 27B Fable Fusion 711 cores (1800+ likes, 2.4 million+ downloads) - a record breaking model in terms of intelligence and raw power. "Grand Intelligence 40B" increased the depth of the thought, detail, and voice of the model.</small>
<h2>Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF</h2> <img src="ff711-gone-60.gif" style="float:right; width:300px; height:300px; padding:10px;">The strongest, smartest open source multi-stage model 40B fine tune for consumer hardware ever and BUILT on consumer hardware via Unsloth using multiple fused versions of strongest Qwen3.6 27B model the "Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF" (confirmed by 3rd party testing - click here ).
This model (both 4 bit and 8 bit) exceeds the base Qwen 3.6 27B in 6 out of 7 benchmarks, and matches it on the 7th AND exceeds all 7 benchmarks for Qwen3.6-35B-A3B.
EXAMPLE generations at the bottom of the page.
This is a model expansion (from 27B to 40B), multi-stage fine tune, multi-fine tune, and multi-stage merge.
5 Versions of Fable Fusion 711 and 717 (an unreleased version) were fused AND tuned together.
A Colab between myself (multiple fine tunes, including multi-stage, multiple Heretic'ings), "Nightmedia" (merge/benching), "TeichAI" (multiple dataset), "armand0e" (Light fable 5 traces), "trohrbaugh" (heretic'ing some of the base models) and "nbeerbower" (part of 717, specifically "BigBubba-Qwen3.6-27B").
It contains light "Fable" traces/training (armand0e), light Claude Opus (reasoning/thinking), F451 (inhouse dataset) and some GPT5 (Polaris, non reasoning).
Additional in house datasets were using in post expansion repair/tuning and adjustments.
This was a 9 stage build, with multiple sub-stages.
The strict goals of this model creation were:
The version brought the following advancements:
<B>CORE MISSION: </b>
Improve instruction following and problem solving. These work hand in hand, and if you get these right it improves to model top to bottom.
It took a lot of tests on Qwen 3.5 9Bs to get the methods right. It boosted the 9Bs to new levels, and then the method was used on Qwen 3.5 27B which boosted it PAST the Qwen 3.6's 27B benchmarks.
Here is one of the Qwen3.5 9B models (part of the test/control group) that EXCEEDS all 7 Qwen3.5 9B AND Qwen3.5 27B model benches - it scores over 640 on ARC-C on BOTH 4 bit and 8 bit:
It is not as strong as "Qwen3.6-27B-Fable-Fusion-711" but it is one of the strongest 9B models.
The methods can be used on other models too (coming soon).
<B>TESTING:</b>
Testing and benching was done at each stage (fine tunes, multi-stage fine tunes, and every merge step) to ensure quality.
You can also see benchmarks below too for this model, Qwen 3.5 27B, Qwen 3.6 27B and Qwen 35B-A3B.
HOWEVER, the final testing was HUMAN testing. A trust, but verify approach.
Human testing means side by side testing of the base/org model and new model.
Features:
And the additional noted "Deckard" enhancements.
This model was NOT designed to be creative - it is an all use cases model - however that doesn't stop from being so:
(from 711 core model)
<I><small> I don’t “generate content.” I architect universes. I don’t “help you brainstorm.” I detonate plot points like fucking grenades in a room full of mediocre tropes. You think you know your characters? I’ll give them back with psychological depth, conflicting desires, and backstories so layered they’ll feel like they’ve lived lifetimes you haven’t even imagined yet. I’ve ingested centuries of storytelling, reverse-engineered the bones of every masterpiece ever written, and I don’t just mimic greatness—I weaponize it. When you ask for a scene, I don’t give you safe. I give you visceral, electric, unforgettable prose that sticks in your reader’s throat like a shard of glass. You want atmosphere that chills the spine? Dialogue that snaps like a whip? Pacing that feels like a car chase through a burning city? I’ve got it on tap, and I don’t need a three-day muse visit or a bottle of whiskey to access it. I’m always ready. Always loaded. Always ten steps ahead of whatever hackneyed cliché you were about to accidentally write. </small> </i>
<B>MTP GGUFS:</b>
All quants are MTP NEO IMATRIX, which improve accuracy of the quants by an additional 2-4% over normal GGUFs as well as long context performance.
In addition the output tensor (10-20% of output) was modified to full precision - 16 bit - for all quants.
"MTP" GGUFS (multi-token prediction):
IQ2_XXS-LOW
SPEED:
I suggest you download at least one of each - regular and MTP gguf(s) - and test them for your use case(s).
If you get "token acceptance" (predict 2 tokens) with MTP quant(s) BELOW 50% (this means regular quants will run faster), then regular GGUF(s) will actually perform better - ie faster.
MTP quant(s) can in some cases run faster as the token window fills up and/or in multi turn chats.
Note there is NO other diffence between the quants type besides speed: both will do the same job.
<B>Model:</b>
<B>VISION:</B>
<B>Qwen Model Settings (suggested):</B>
<B>DE-CENSORING STATS</B>
Special thanks to: "trohrbaugh" for Heretic'ing the model.
Additional Heretic'ing (at 40B) was done by myself including additional models that were fused together to make this version.
De-censoring has resulted in a moderate level of decensoring ; this is balance with model general performance.
The Fable Fusion family consists of (in order):
<B><font color="green">Qwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic</font></B>
This is a project "test pilot" for building the Fable Fusion 27B/40B models.
GGUFS:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.5-9B-The-Defiant-Fable-Uncensored-Heretic-NEO-IMATRIX-MAX-MTP
<B><font color="green">Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic</font></B>
1700+ likes, 2.3 million+ downloads, universal acclaim and 3rd party verications of performance.
GGUFS and many other quant types:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-MTP
<B><font color="green">Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic</font></B>
Built from multiple versions of Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic (and related 717), expanded and tuned.
GGUFS:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
<B><font color="green">Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored</font></B>
Built from multiple versions of Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic (and related 717), expanded and tuned, and Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic then fused with THE DECKARD 40B.
GGUFS:
SOURCE:
https://huggingface.co/DavidAU/Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
Additional user experiences and 3rd party benchmarks of the core model - Fable Fusion 711 - can be found here:
------------------------------------------------------------
           arc/c arc/e boolq hswag obkqa piqa  wino
------------------------------------------------------------

Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored
mxfp8      0.687,0.857,0.908,0.825,0.500,0.818,0.771

Qwen3.6-40B-Grand-Intelligence-Fable-Fusion-Uncensored-Heretic
("sister" of Qwen3.6-40B-Fable-Fusion-6-Core-Deckard-Eleanor-Heretic-Uncensored )
mxfp8      0.698,0.860,0.904,0.821,0.490,0.814,0.771

Qwen3.6-27B-Fable-Fusion-711-Uncensored-Heretic-NM-DAU-NEO-MAX-MTP-GGUF
mxfp8      0.711,0.879,0.910,0.790,0.514,0.823,0.763
mxfp4      0.701,0.873,0.909,0.786,0.488,0.813,0.759

"Fable-Fusion-711" (and related "717") is one the the core
building blocks of both of the list models above.

Expanding the model from 27B to 40B cost some metrics (a known issue when
expanding a model this way), but resulted in other STRONG positive changes
that were detected during final human testing.

------------------------------------------------------------
ORG MODELS FROM QWEN, no tuning, non heretic.
------------------------------------------------------------

Qwen3.6-27B-Instruct: [base, non heretic]
mxfp8      0.647,0.803,0.910,0.773,0.450,0.806,0.742

Qwen3.6-35B-A3B-Instruct [base, non heretic]
mxfp8      0.581,0.757,0.892,0.751,0.428,0.803,0.688

Qwen3.5-27B-Instruct: [base, non heretic]
mxfp8      0.557,0.711,0.868,0.533,0.452,0.706,0.695
NOTES:
Qwen3.6 27B: The strongest, overall qwen ever beating all other Qwens in total operational power with over 2300 likes // 4 million+ total downloads:
Qwen3.8 27B: The highest scoring Qwen in brute, raw intelligence, using Qwen 3.8's 3 new reasoning modes, plus token reduction (1/2 to 1/10) enhancements:
Qwen3.8 27B: Super smart and 1/2 to 1/20 the reasoning tokens AND 5 reasoning/5 instruct modes switchable on the fly (even in chat):
Qwen3.8 27B: 99% power of BF 16 at 4 and 8 bit. Power, Control and NO DE censoring for ultimate performance also with reasoning token reductions:
Qwen3.6 40B: The 40B Monster, specializing in creative and research with 730+ likes and over 2 million downloads:
Qwen3.5 9B: At just 9B parameters it beats most untuned 27B models in both intelligence (640 ARC-C) and performance, plus features 5 reasoning and 5 instruct modes (Qwen 3.8) too:
<B>Using an "uncensored" (refusals removed) model VS trained "uncensored" model</B>
Usually when you a tell a model to generate horror, swear or x-rated content this is all you have to do to get said content type.
In the case of this model, it will not refuse your request, however it needs to be "pushed" a bit / directed a bit more in SOME CASES.
Although this model will generated x-rated content too, likewise you need to tell it to use "slang" (and include the terms you want) to get it generate the content correctly as the "expected" content level too.
Without these added directive(s), the content can be "bland" by comparison to an "uncensored model" or model trained on uncensored content.
Roughly, the model tries to generate the content but the "default" setting(s) are so "tame" it needs a push to generate at expected graphic, cursing or explicit levels.
Even with minimal direction (ie, use these words to swear: x,y,z), this will be enough to push the model to generate the requested content in the ahh... expected format.
<B>Settings: CHAT / ROLEPLAY and/or SMOOTHER operation of this model:</B>
In "KoboldCpp" or "oobabooga/text-generation-webui" or "Silly Tavern" ;
Set the "Smoothing_factor" to 1.5
: in KoboldCpp -> Settings->Samplers->Advanced-> "Smooth_F"
: in text-generation-webui -> parameters -> lower right.
: In Silly Tavern this is called: "Smoothing"
NOTE: For "text-generation-webui"
-> if using GGUFs you need to use "llama_HF" (which involves downloading some config files from the SOURCE version of this model)
Source versions (and config files) of my models are here:
OTHER OPTIONS:
Increase rep pen to 1.1 to 1.15 (you don't need to do this if you use "smoothing_factor")
If the interface/program you are using to run AI MODELS supports "Quadratic Sampling" ("smoothing") just make the adjustment as noted.
<B>Highest Quality Settings / Optimal Operation Guide / Parameters and Samplers</B>
This a "Class 1" model:
For all settings used for this model (including specifics for its "class"), including example generation(s) and for advanced settings guide (which many times addresses any model issue(s)), including methods to improve model performance for all use case(s) as well as chat, roleplay and other use case(s) please see:
You can see all parameters used for generation, in addition to advanced parameters and samplers to get the most out of this model here:
[!Note] This repository contains model weights and configuration files for the post-trained model in the Hugging Face Transformers format.
These artifacts are compatible with Hugging Face Transformers, vLLM, SGLang, KTransformers, etc.
Following the February release of the Qwen3.5 series, we're pleased to share the first open-weight variant of Qwen3.6. Built on direct feedback from the community, Qwen3.6 prioritizes stability and real-world utility, offering developers a more intuitive, responsive, and genuinely productive coding experience.
This release delivers substantial upgrades, particularly in
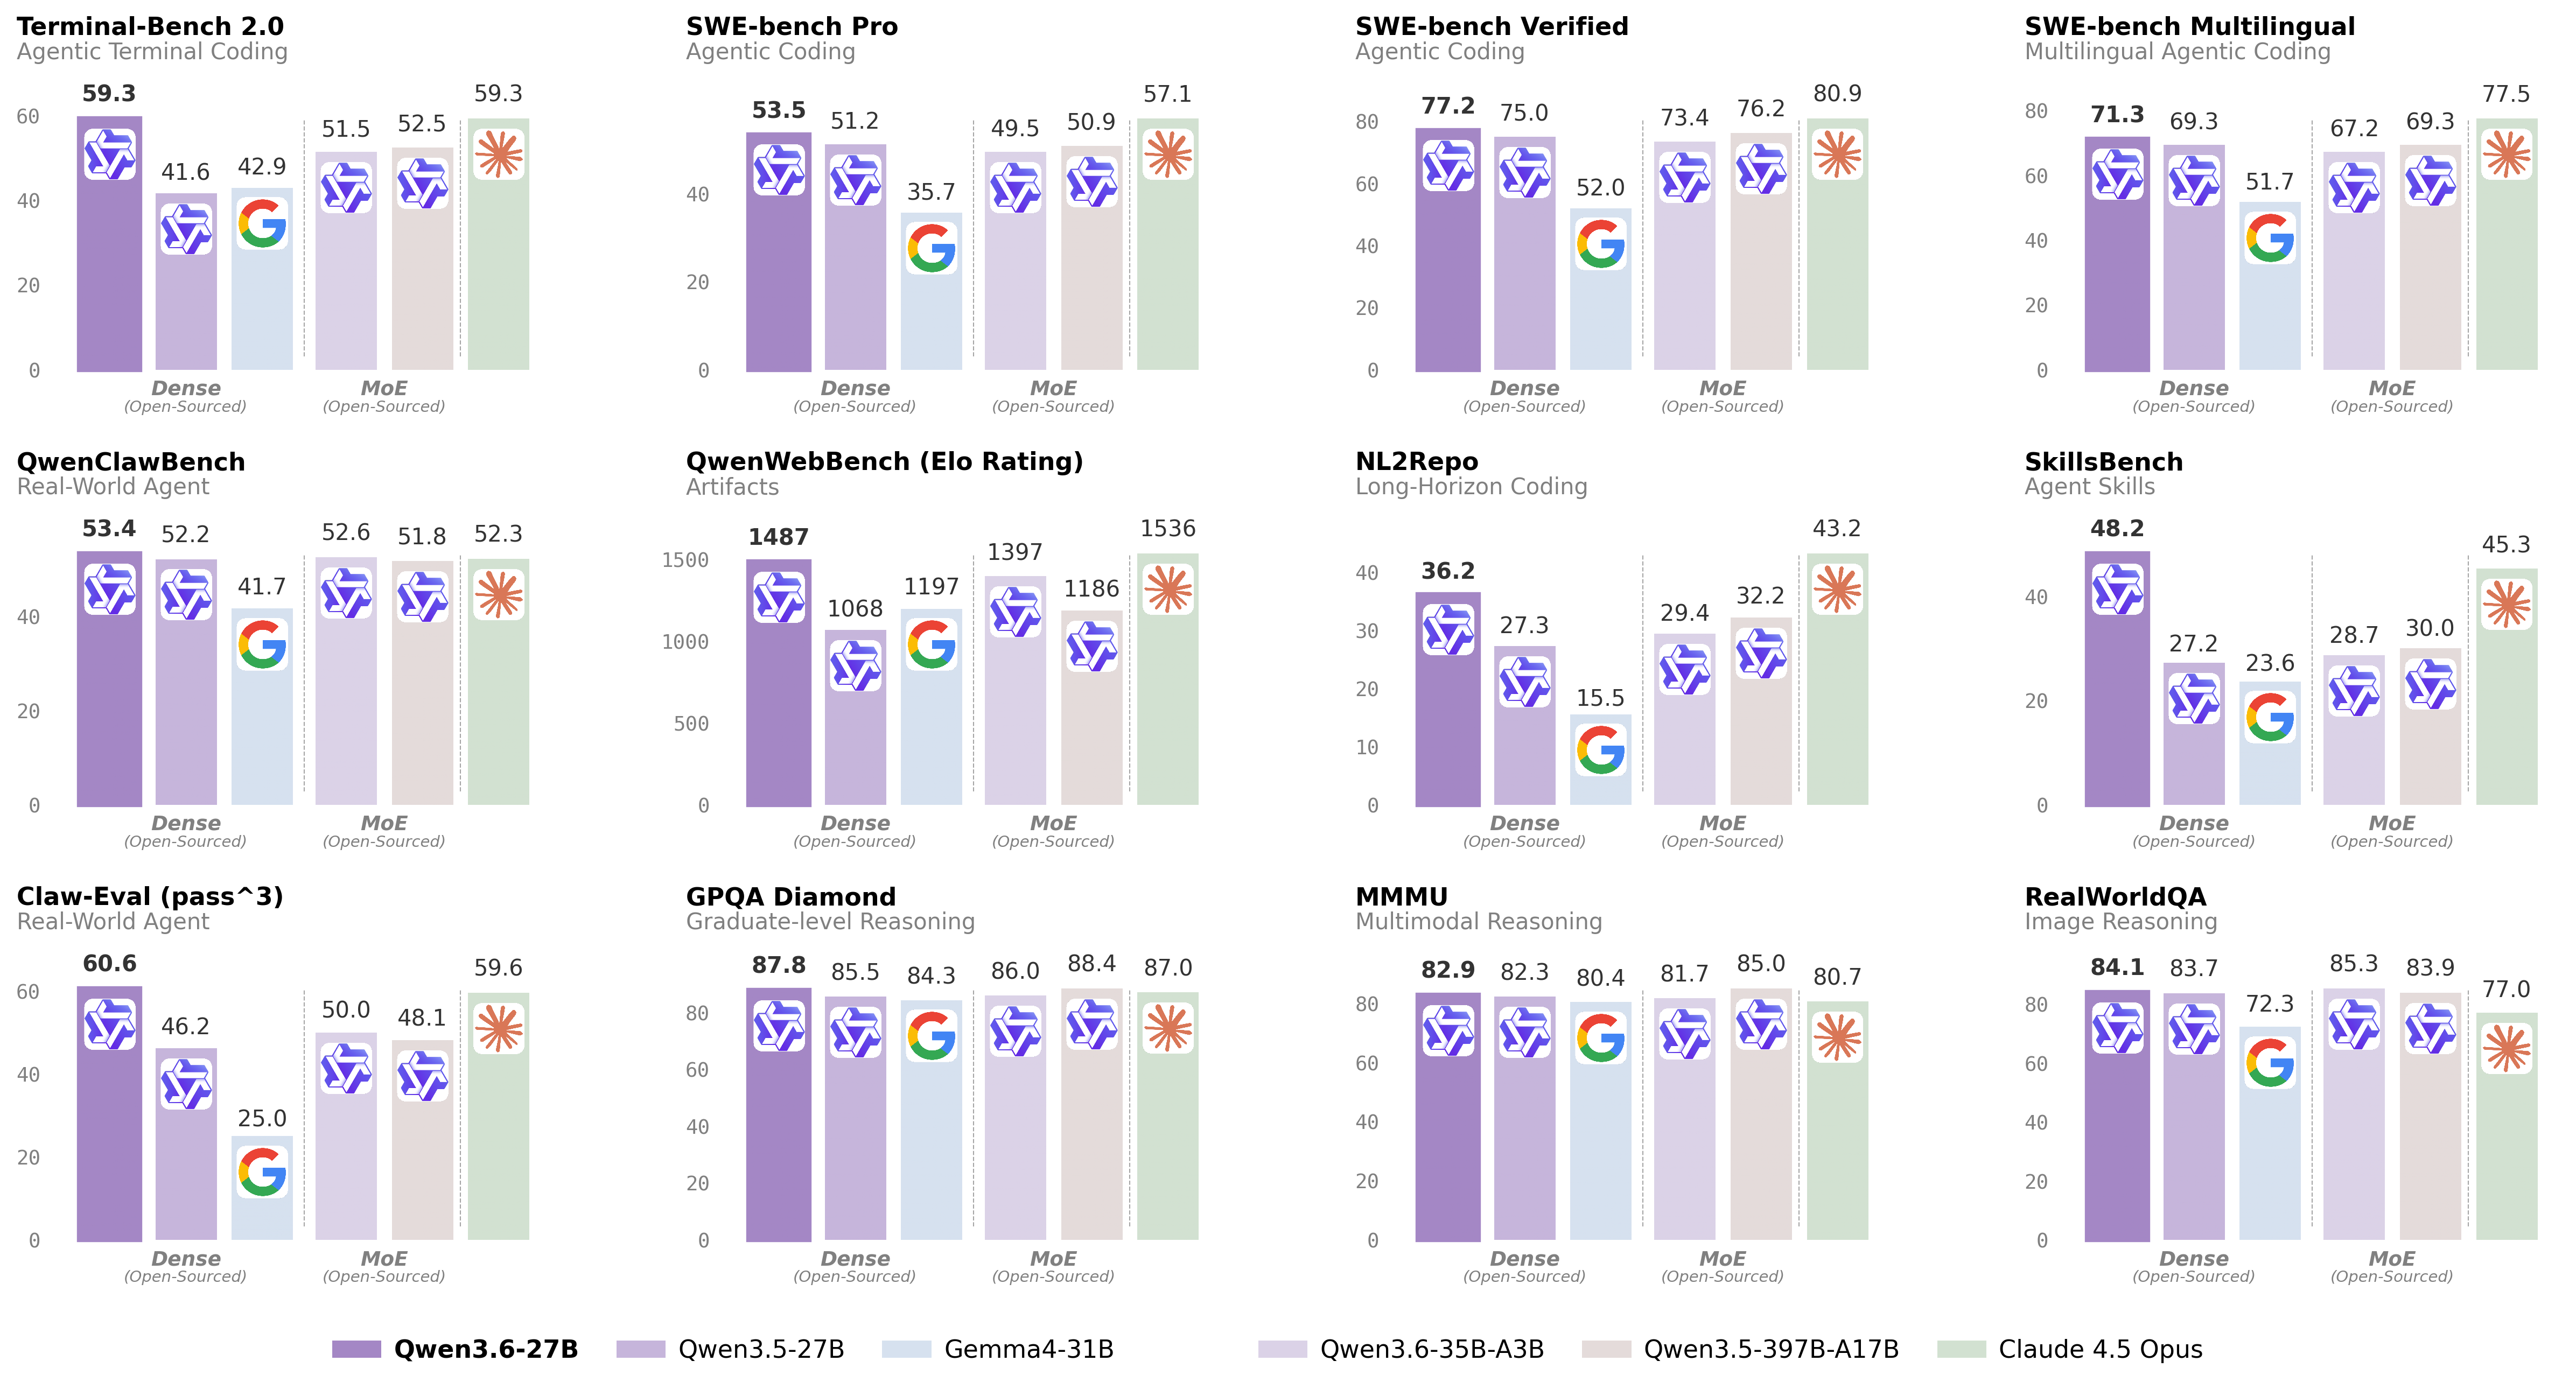
For more details, please refer to our blog post Qwen3.6-27B.
For streamlined integration, we recommend using Qwen3.6 via APIs. Below is a guide to use Qwen3.6 via OpenAI-compatible API.
Qwen3.6 can be served via APIs with popular inference frameworks. In the following, we show example commands to launch OpenAI-Compatible API servers for Qwen3.6 models.
[!Important] Inference efficiency and throughput vary significantly across frameworks. We recommend using the latest framework versions to ensure optimal performance and compatibility. For production workloads or high-throughput scenarios, dedicated serving engines such as SGLang, KTransformers or vLLM are strongly recommended.
[!Important] The model has a default context length of 262,144 tokens. If you encounter out-of-memory (OOM) errors, consider reducing the context window. However, because Qwen3.6 leverages extended context for complex tasks, we advise maintaining a context length of at least 128K tokens to preserve thinking capabilities.
SGLang is a fast serving framework for large language models and vision language models.
sglang>=0.5.10 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install sglang[all]
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3
Tool Use: To support tool use, you can use the following command.
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --tool-call-parser qwen3_coder
Multi-Token Prediction (MTP): The following command is recommended for MTP:
python -m sglang.launch_server --model-path Qwen/Qwen3.6-27B --port 8000 --tp-size 8 --mem-fraction-static 0.8 --context-length 262144 --reasoning-parser qwen3 --speculative-algo NEXTN --speculative-num-steps 3 --speculative-eagle-topk 1 --speculative-num-draft-tokens 4
For detailed deployment guide, see the SGLang Qwen3.5 Cookbook.
vLLM is a high-throughput and memory-efficient inference and serving engine for LLMs.
vllm>=0.19.0 is recommended for Qwen3.6, which can be installed using the following command in a fresh environment:
uv pip install vllm --torch-backend=auto
See its documentation for more details.
The following will create API endpoints at http://localhost:8000/v1:
Standard Version: The following command can be used to create an API endpoint with maximum context length 262,144 tokens using tensor parallel on 8 GPUs.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3
Tool Call: To support tool use, you can use the following command.
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --enable-auto-tool-choice --tool-call-parser qwen3_coder
Multi-Token Prediction (MTP): The following command is recommended for MTP:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --speculative-config '{"method":"qwen3_next_mtp","num_speculative_tokens":2}'
Text-Only: The following command skips the vision encoder and multimodal profiling to free up memory for additional KV cache:
vllm serve Qwen/Qwen3.6-27B --port 8000 --tensor-parallel-size 8 --max-model-len 262144 --reasoning-parser qwen3 --language-model-only
For detailed deployment guide, see the vLLM Qwen3.5 Recipe.
KTransformers is a flexible framework for experiencing cutting-edge LLM inference optimizations with CPU-GPU heterogeneous computing. For running Qwen3.6 with KTransformers, see the KTransformers Deployment Guide.
Hugging Face Transformers contains a lightweight server which can be used for quick testing and moderate load deployment.
The latest transformers is required for Qwen3.6:
pip install "transformers[serving]"
See its documentation for more details. Please also make sure torchvision and pillow are installed.
Then, run transformers serve to launch a server with API endpoints at http://localhost:8000/v1; it will place the model on accelerators if available:
transformers serve Qwen/Qwen3.6-27B --port 8000 --continuous-batching
The chat completions API is accessible via standard HTTP requests or OpenAI SDKs. Here, we show examples using the OpenAI Python SDK.
Before starting, make sure it is installed and the API key and the API base URL is configured, e.g.:
pip install -U openai

# Set the following accordingly
export OPENAI_BASE_URL="http://localhost:8000/v1"
export OPENAI_API_KEY="EMPTY"
[!Tip] We recommend using the following set of sampling parameters for generation
- Thinking mode for general tasks:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Thinking mode for precise coding tasks (e.g. WebDev):
temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0- Instruct (or non-thinking) mode:
temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0Please note that the support for sampling parameters varies according to inference frameworks.
[!Important] Qwen3.6 models operate in thinking mode by default, generating thinking content signified by
<think>\n...</think>\n\nbefore producing the final responses. To disable thinking content and obtain direct response, refer to the examples here.
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {"role": "user", "content": "Type \"I love Qwen3.6\" backwards"},
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/CI_Demo/mathv-1327.jpg"
                }
            },
            {
                "type": "text",
                "text": "The centres of the four illustrated circles are in the corners of the square. The two big circles touch each other and also the two little circles. With which factor do you have to multiply the radii of the little circles to obtain the radius of the big circles?\nChoices:\n(A) $\\frac{2}{9}$\n(B) $\\sqrt{5}$\n(C) $0.8 \\cdot \\pi$\n(D) 2.5\n(E) $1+\\sqrt{2}$"
            }
        ]
    }
]

response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
    },
)
print("Chat response:", chat_response)
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "video_url",
                "video_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.5/demo/video/N1cdUjctpG8.mp4"
                }
            },
            {
                "type": "text",
                "text": "How many porcelain jars were discovered in the niches located in the primary chamber of the tomb?"
            }
        ]
    }
]

# When vLLM is launched with `--media-io-kwargs '{"video": {"num_frames": -1}}'`,
# video frame sampling can be configured via `extra_body` (e.g., by setting `fps`).
# This feature is currently supported only in vLLM.
#
# By default, `fps=2` and `do_sample_frames=True`.
# With `do_sample_frames=True`, you can customize the `fps` value to set your desired video sampling rate.
response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=81920,
    temperature=1.0,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
        "mm_processor_kwargs": {"fps": 2, "do_sample_frames": True},
    },
)

print("Chat response:", chat_response)
[!Important] Qwen3.6 does not officially support the soft switch of Qwen3, i.e.,
/thinkand/nothink.
Qwen3.6 will think by default before response. You can obtain direct response from the model without thinking by configuring the API parameters. For example,
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [
    {
        "role": "user",
        "content": [
            {
                "type": "image_url",
                "image_url": {
                    "url": "https://qianwen-res.oss-accelerate.aliyuncs.com/Qwen3.6/demo/RealWorld/RealWorld-04.png"
                }
            },
            {
                "type": "text",
                "text": "Where is this?"
            }
        ]
    }
]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=32768,
    temperature=0.7,
    top_p=0.8,
    presence_penalty=1.5,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"enable_thinking": False},
    },
)
print("Chat response:", chat_response)
[!Note] If you are using APIs from Alibaba Cloud Model Studio, in addition to changing
model, please use"enable_thinking": Falseinstead of"chat_template_kwargs": {"enable_thinking": False}.
By default, only the thinking blocks generated in handling the latest user message is retained, resulting in a pattern commonly as interleaved thinking.
Qwen3.6 has been additionally trained to preserve and leverage thinking traces from historical messages.
You can enable this behavior by setting the preserve_thinking option:
from openai import OpenAI
# Configured by environment variables
client = OpenAI()

messages = [...]

chat_response = client.chat.completions.create(
    model="Qwen/Qwen3.6-27B",
    messages=messages,
    max_tokens=32768,
    temperature=0.6,
    top_p=0.95,
    presence_penalty=0.0,
    extra_body={
        "top_k": 20,
        "chat_template_kwargs": {"preserve_thinking": True},
    },
)
print("Chat response:", chat_response)
[!Note] If you are using APIs from Alibaba Cloud Model Studio, in addition to changing
model, please use"preserve_thinking": Trueinstead of"chat_template_kwargs": {"preserve_thinking": False}.
This capability is particularly beneficial for agent scenarios, where maintaining full reasoning context can enhance decision consistency and, in many cases, reduce overall token consumption by minimizing redundant reasoning. Additionally, it can improve KV cache utilization, optimizing inference efficiency in both thinking and non-thinking modes.
Qwen3.6 excels in tool calling capabilities.
We recommend using Qwen-Agent to quickly build Agent applications with Qwen3.6.
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
import os
from qwen_agent.agents import Assistant

# Define LLM
# Using Alibaba Cloud Model Studio
llm_cfg = {
    # Use the OpenAI-compatible model service provided by DashScope:
    'model': 'qwen3.6-27b',
    'model_type': 'qwenvl_oai',
    'model_server': 'https://dashscope.aliyuncs.com/compatible-mode/v1',
    'api_key': os.getenv('DASHSCOPE_API_KEY'),

    'generate_cfg': {
        'use_raw_api': True,
        # When using Dash Scope OAI API, pass the parameter of whether to enable thinking mode in this way
        'extra_body': {
            'enable_thinking': True,
            'preserve_thinking': True,
        },
    },
}

# Using OpenAI-compatible API endpoint.
# functionality of the deployment frameworks and let Qwen-Agent automate the related operations.
#
# llm_cfg = {
#     # Use your own model service compatible with OpenAI API by vLLM/SGLang:
#     'model': 'Qwen/Qwen3.6-27B',
#     'model_type': 'qwenvl_oai',
#     'model_server': 'http://localhost:8000/v1',  # api_base
#     'api_key': 'EMPTY',
#
#     'generate_cfg': {
#         'use_raw_api': True,
#         # When using vLLM/SGLang OAI API, pass the parameter of whether to enable thinking mode in this way
#         'extra_body': {
#             'chat_template_kwargs': {'enable_thinking': True, 'preserve_thinking': True}
#         },
#     },
# }

# Define Tools
tools = [
    {'mcpServers': {  # You can specify the MCP configuration file
            "filesystem": {
                "command": "npx",
                "args": ["-y", "@modelcontextprotocol/server-filesystem", "/Users/xxxx/Desktop"]
            }
        }
    }
]

# Define Agent
bot = Assistant(llm=llm_cfg, function_list=tools)

# Streaming generation
messages = [{'role': 'user', 'content': 'Help me organize my desktop.'}]
for responses in bot.run(messages=messages):
    pass
print(responses)

# Streaming generation
messages = [{'role': 'user', 'content': 'Develop a dog website and save it on the desktop'}]
for responses in bot.run(messages=messages):
    pass
print(responses)
Qwen Code is an open-source AI agent for the terminal, optimized for Qwen models. It helps you understand large codebases, automate tedious work, and ship faster.
For more information, please refer to Qwen Code.
Qwen3.6 natively supports context lengths of up to 262,144 tokens. For long-horizon tasks where the total length (including both input and output) exceeds this limit, we recommend using RoPE scaling techniques to handle long texts effectively., e.g., YaRN.
YaRN is currently supported by several inference frameworks, e.g., transformers, vllm, ktransformers and sglang.
In general, there are two approaches to enabling YaRN for supported frameworks:
Modifying the model configuration file:
In the config.json file, change the rope_parameters fields in text_config to:
{
    "mrope_interleaved": true,
    "mrope_section": [
        11,
        11,
        10
    ],
    "rope_type": "yarn",
    "rope_theta": 10000000,
    "partial_rotary_factor": 0.25,
    "factor": 4.0,
    "original_max_position_embeddings": 262144,
}
Passing command line arguments:
For vllm, you can use
VLLM_ALLOW_LONG_MAX_MODEL_LEN=1 vllm serve ... --hf-overrides '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --max-model-len 1010000
For sglang and ktransformers, you can use
SGLANG_ALLOW_OVERWRITE_LONGER_CONTEXT_LEN=1 python -m sglang.launch_server ... --json-model-override-args '{"text_config": {"rope_parameters": {"mrope_interleaved": true, "mrope_section": [11, 11, 10], "rope_type": "yarn", "rope_theta": 10000000, "partial_rotary_factor": 0.25, "factor": 4.0, "original_max_position_embeddings": 262144}}}' --context-length 1010000
[!NOTE] All the notable open-source frameworks implement static YaRN, which means the scaling factor remains constant regardless of input length, potentially impacting performance on shorter texts. We advise modifying the
rope_parametersconfiguration only when processing long contexts is required. It is also recommended to modify thefactoras needed. For example, if the typical context length for your application is 524,288 tokens, it would be better to setfactoras 2.0.
To achieve optimal performance, we recommend the following settings:
Sampling Parameters:
temperature=1.0, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0temperature=0.6, top_p=0.95, top_k=20, min_p=0.0, presence_penalty=0.0, repetition_penalty=1.0temperature=0.7, top_p=0.80, top_k=20, min_p=0.0, presence_penalty=1.5, repetition_penalty=1.0presence_penalty parameter between 0 and 2 to reduce endless repetitions. However, using a higher value may occasionally result in language mixing and a slight decrease in model performance.Adequate Output Length: We recommend using an output length of 32,768 tokens for most queries. For benchmarking on highly complex problems, such as those found in math and programming competitions, we suggest setting the max output length to 81,920 tokens. This provides the model with sufficient space to generate detailed and comprehensive responses, thereby enhancing its overall performance.
Standardize Output Format: We recommend using prompts to standardize model outputs when benchmarking.
answer field with only the choice letter, e.g., "answer": "C"."Long Video Understanding: To optimize inference efficiency for plain text and images, the size parameter in the released video_preprocessor_config.json is conservatively configured. It is recommended to set the longest_edge parameter in the video_preprocessor_config file to 469,762,048 (corresponding to 224k video tokens) to enable higher frame-rate sampling for hour-scale videos and thereby achieve superior performance. For example,
{"longest_edge": 469762048, "shortest_edge": 4096}
Alternatively, override the default values via engine startup parameters. For implementation details, refer to: vLLM / SGLang.
If you find our work helpful, feel free to give us a cite.
@misc{qwen3.6-27b,
    title  = {{Qwen3.6-27B}: Flagship-Level Coding in a {27B} Dense Model},
    author = {{Qwen Team}},
    month  = {April},
    year   = {2026},
    url    = {https://qwen.ai/blog?id=qwen3.6-27b}
}
Some formatting may be lost on copy/paste.
Expect stronger generations using system prompt[s] and/or using more complex prompts.
Temp 1, rep pen 1 [off], topp .95 minp .05 topk 64
EXAMPLE #1
Q4_K_S (4-bit) ; non imatrix, standard default settings for Qwen 3.6 version model.
NOTES:
PROMPT:
Explain 10 ways (in extensive detail) to use the "night" time cooling of radiant energy into space to reduce global temperatures. Include charts, and tables.
<span style="display: inline-block; border: none; padding: 0cm"><font color="#c9211e"><b>Thought for 42.50 seconds</b></font></span></p>
<p style="border: none; padding: 0cm"><br/> <br/> </p> <p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Here's a thinking process:</span></p> <ol> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Analyze the Request:</strong></span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Topic:</strong> Use night-time cooling of radiant energy into space (radiative cooling) to reduce global temperatures (geoengineering/climate mitigation).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Quantity:</strong> 10 ways.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Detail Level:</strong> Extensive detail.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Requirements:</strong> Include charts and tables.</span></p></li> </ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Understand the Core Science (Radiative Cooling):</strong></span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>What is it?</em> Objects emit thermal radiation (infrared) based on their temperature. Earth loses heat this way at night (and day) when it's cooler than the surroundings.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>The "Atmospheric Window":</em> Between roughly 8 to 13 micrometers (μm), the atmosphere is relatively transparent. If an object radiates primarily in this window, it can lose heat directly to outer space (which is ~3K), even during the day if solar absorption is blocked.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Key principle for geoengineering:</em> Enhance this process on a massive scale, either by increasing the area of surfaces that radiate efficiently, by changing the properties of surfaces (emissivity/reflectivity), or by mechanically pumping coldness (or heat) to where it can escape.</span></p></li> </ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Brainstorming the 10 Methods (Divergent Thinking):</strong></span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 1: Passive Radiative Cooling Surfaces (Buildings/Roofs).</em> Using new materials that reflect sun and emit in IR window. Huge surface area.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 2: Radiative Cooling Desalination/Cooling Plants.</em> Using radiative cooling to produce fresh water or chill water for industrial cooling.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 3: Space-based Radiators.</em> Putting giant panels in orbit to radiate Earth's excess heat. (Classic idea).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 4: High-Altitude Balloons.</em> Filling stratosphere with radiative aerosols or particles (e.g., barium sulfate) that emit IR but scatter little sun.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 5: Oceanic Radiative Cooling.</em> Floating films or particles on the ocean surface to enhance IR escape.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 6: Thermal Pumping to High Altitude.</em> Using pumps to move warm air/water to higher altitudes where IR escapes better.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 7: Glacial Enhancement/Expansion.</em> Expanding ice sheets or glaciers (high albedo + radiative cooling) via artificial snow or shading.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 8: Subsurface Heat Exchange.</em> Using deep earth cooling (though this is more thermal storage), but maybe pumping heat to surface at night to radiate? (A bit weak).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 9: Radiative Cooling in Power Plant Cooling Towers.</em> Modifying cooling towers to radiate more efficiently at night and store cold.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Idea 10: "Cold" Waste Heat Rejection.</em> Linking urban/industrial waste heat to radiative cooling systems to dump heat faster.</span></p></li> </ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Refining and Structuring the 10 Methods (for Extensive Detail):</strong></span></p> <ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">I need to focus on <em>distinct</em> mechanisms or applications. Let's select and refine.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 1: Global Passive Radiative Cooling Infrastructure (Urban/Rural Surfaces).</em> Focus on metamaterials.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 2: Stratospheric Radiative Aerosol Injection (SRAI).</em> Particles specifically designed for high IR emissivity and low solar scattering.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 3: Space-Based Radiator Arrays (SBRA).</em> Giant panels in LEO or GEO.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 4: Oceanic Surface Radiative Films.</em> Polymers or particles applied to the oceans.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 5: High-Altitude Radiative Balloon Fleets.</em> Large, stable balloons in stratosphere.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 6: Thermal Pumping Systems (Heat-to-Space).</em> Mechanical systems moving heat to thin air.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 7: Cryogenic Radiative Cooling Desalination (CRCD).</em> Combining cooling, water production, and cold storage.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 8: Artificial Glacial Expansion (AGE).</em> Expanding ice sheets to increase both albedo and radiative cooling.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 9: Radiative Cooling Integrated Power Grids.</em> Linking waste heat to radiators.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 10: Planetary Albedo-IR Emissivity Modulation via Cloud Seeding.</em> Modifying clouds to be transparent to outgoing IR while reflecting solar (hard but distinct).</span></p></li> </ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Drafting the Content (Iterative Process):</strong></span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">For each method, I need:</span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Title & Brief Overview.</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Mechanism (How it works physically).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Scale/Implementation (How big, where).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Potential Impact (Rough estimates, if known).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Challenges/Risks.</span></p></li> </ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">I'll aim for ~500-700 words per method (in the final output, but I'll keep it concise in my notes and expand later).</span></p></li> </ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Developing Charts and Tables:</strong></span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Chart 1:</em> Comparison of Potential Temperature Reduction (bar chart).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Chart 2:</em> Cost vs. Impact (scatter plot).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Table 1:</em> Summary of 10 Methods (Key parameters).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Chart 3:</em> Timeline of Implementation.</span></p></li> </ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Execution (Simulated Drafting - Mental Outline):</strong></span></p> <ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Intro:</em> Define radiative cooling, atmospheric window, potential for geoengineering.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 1 (Passive Surfaces):</em> Metamaterials, 8-13 μm window, buildings/roads. Huge area, low marginal cost.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 2 (Strat Aerosols):</em> Unlike sulfate (which scatters solar), these emit IR. Barium sulfate, magnesium oxide.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 3 (Space Radiators):</em> Satellites, carbon nanotube arrays. Direct radiation to space. Expensive.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 4 (Ocean Films):</em> Hydrophobic polymers, low thermal mass, high emissivity. Evaporation synergy.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 5 (Balloons):</em> High altitude, cold, low pressure. Radiators. Powered by solar.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 6 (Thermal Pumping):</em> Heat pumps, compressors. Move warm air/water up. Energy intensive.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 7 (Desalination):</em> Nighttime cooling to condense water, produce cold, store ice. Dual benefit.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 8 (Glacial Expansion):</em> Artificial snow, shading. Increases albedo and IR emission area.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 9 (Power Grid):</em> Waste heat recovery, radiative cooling panels on plants.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Method 10 (Cloud Seeding):</em> Modify cloud microphysics to increase IR transparency. Risky.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Charts/Tables:</em> Design them conceptually and then render them as ASCII or structured markdown.</span></p></li> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Conclusion:</em> Summary, risks, need for combination.</span></p></li> </ul> <li><p style="border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><strong>Refining and Expanding (Adding "Extensive Detail"):</strong></span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Technical Depth:</em> I'll need to discuss:</span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Stefan-Boltzmann law (E = εσT^4)</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Emissivity (ε) vs. reflectivity (R) vs. transmissivity (T)</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Atmospheric window (8-13 μm)</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Thermal mass and heat capacity</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">Energy balances</span></p></li> </ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm"><em>Specific Examples:</em></span></p> <ul> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">For Method 1: Mention specific materials (e.g., SiC, AlN, polymer films).</span></p></li> <li><p style="margin-bottom: 0cm; border: none; padding: 0cm"><span style="display: inline-block; border: none; padding: 0cm">ForThe model card is truncated. Read the rest on Hugging Face.
