Downloads · 30 days
0
0% of all-time downloads
DaniloTrotta/Kandinsky_2.1
Kandinsky_2.1 is a text-to-image model from DaniloTrotta. Use it when you need an image from a text prompt. It is set up for open_clip. The card lists the license as apache-2.0.
Downloads · 30 days
0
0% of all-time downloads
All-time downloads
386
Public
Repo size
33.7 GB
Likes
0
Public
Click a slice to open those files.
.ckpt12.6 GB · 85%
From the Hugging Face model README
Kandinsky 2.1 inherits best practicies from Dall-E 2 and Latent diffusion, while introducing some new ideas.
As text and image encoder it uses CLIP model and diffusion image prior (mapping) between latent spaces of CLIP modalities. This approach increases the visual performance of the model and unveils new horizons in blending images and text-guided image manipulation.
For diffusion mapping of latent spaces we use transformer with num_layers=20, num_heads=32 and hidden_size=2048.
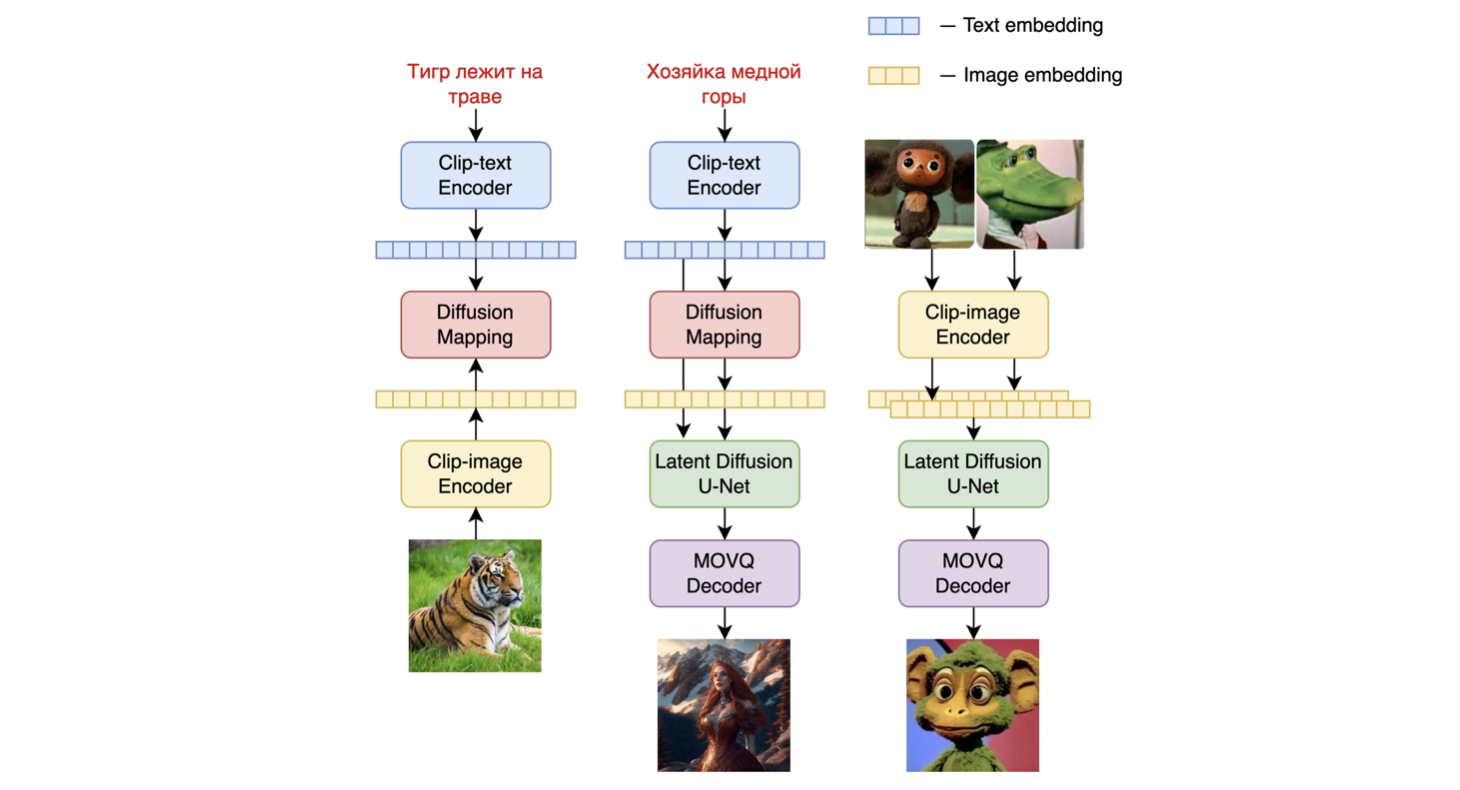
Other architecture parts: