
Downloads · 30 days
33
1% of all-time downloads
CoRal-project/roest-v1-wav2vec2-315m
roest-v1-wav2vec2-315m is a automatic speech recognition model from CoRal-project. Use it when you need speech turned into text. It is set up for transformers. The card lists the license as openrail.
A new improved version is available: CoRal-project/roest-wav2vec2-315m-v2
Downloads · 30 days
33
1% of all-time downloads
All-time downloads
3.5K
Public
Parameters
315M
3.2 GB on disk
Likes
12
Public
Click a slice to open those files.
.bin751 MB · 53%
From the Hugging Face model README
A new improved version is available: CoRal-project/roest-wav2vec2-315m-v2
This is a Danish state-of-the-art speech recognition model, trained by the Alexandra Institute.
Start by installing the required libraries:
$ pip install transformers kenlm pyctcdecode
Next you can use the model using the transformers Python package as follows:
>>> from transformers import pipeline
>>> audio = get_audio()  # 16kHz raw audio array
>>> transcriber = pipeline(model="CoRal-project/roest-wav2vec2-315m-v1")
>>> transcriber(audio)
{'text': 'your transcription'}
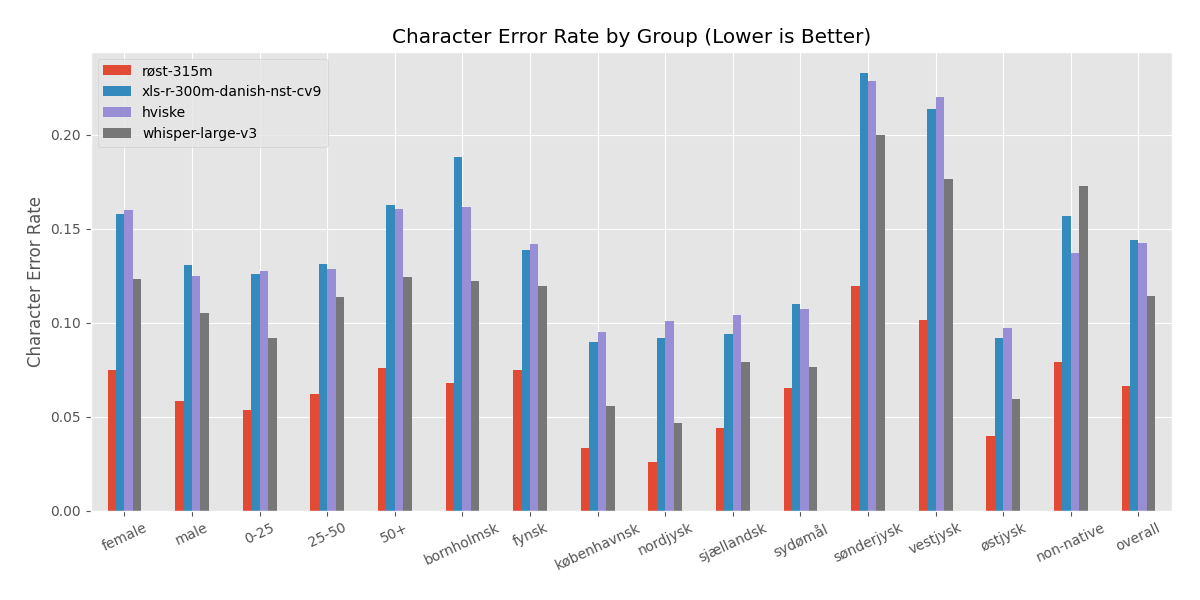
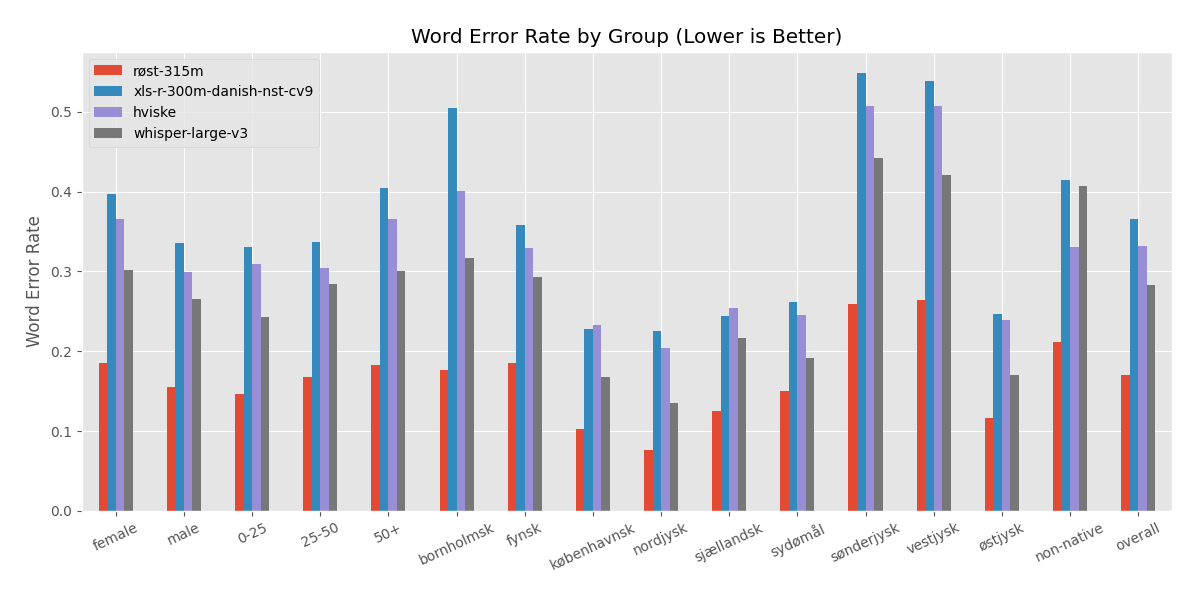
We have evaluated both our and existing models on the CoRal test set as well as the Danish Common Voice 17 test set. To ensure as robust an evaluation as possible, we have bootstrapped the results 1000 times and report here the mean scores along with a 95% confidence interval (lower is better; best scores in bold, second-best in italics):
| Model | Number of parameters | CoRal CER | CoRal WER | Danish Common Voice 17 CER | Danish Common Voice 17 WER |
|---|---|---|---|---|---|
| CoRal-project/roest-wav2vec2-315m-v1 (this model) | 315M | 6.6% ± 0.2% | 17.0% ± 0.4% | 6.6% ± 0.6% | 16.7% ± 0.8% |
| chcaa/xls-r-300m-danish-nst-cv9 | 315M | 14.4% ± 0.3% | 36.5% ± 0.6% | 4.1% ± 0.5% | 12.0% ± 0.8% |
| mhenrichsen/hviske | 1540M | 14.2% ± 0.5% | 33.2% ± 0.7% | 5.2% ± 0.4% | 14.2% ± 0.8% |
| openai/whisper-large-v3 | 1540M | 11.4% ± 0.3% | 28.3% ± 0.6% | 5.5% ± 0.4% | 14.8% ± 0.8% |
| openai/whisper-large-v2 | 1540M | 13.9% ± 0.9% | 32.6% ± 1.2% | 7.2% ± 0.5% | 18.5% ± 0.9% |
| openai/whisper-large | 1540M | 14.5% ± 0.3% | 35.4% ± 0.6% | 9.2% ± 0.5% | 22.9% ± 1.0% |
| openai/whisper-medium | 764M | 17.2% ± 1.3% | 40.5% ± 2.1% | 9.4% ± 0.5% | 24.0% ± 1.0% |
| openai/whisper-small | 242M | 23.4% ± 1.2% | 55.2% ± 2.3% | 15.9% ± 1.0% | 38.9% ± 1.2% |
| openai/whisper-base | 73M | 43.5% ± 3.1% | 89.3% ± 4.6% | 33.4% ± 4.7% | 71.4% ± 7.0% |
| openai/whisper-tiny | 38M | 52.0% ± 2.5% | 103.7% ± 3.5% | 42.2% ± 3.9% | 83.6% ± 2.7% |
This model is the result of four different stages of training:
The first step was trained by Babu et al. (2021) and the second and third step by Nielsen et al. (2024).
The final product is then the combination of the finetuned model along with the n-gram model, and this is what is used when you use the model as mentioned in the Quick Start section above.
This model is intended to be used for Danish automatic speech recognition.
Note that Biometric Identification is not allowed using the CoRal dataset and/or derived models. For more information, see addition 4 in our license.
Røst is both the Danish word for the human voice as well as being the name of one of the cold-water coral reefs in Scandinavia.
The dataset is licensed under a custom license, adapted from OpenRAIL-M, which allows commercial use with a few restrictions (speech synthesis and biometric identification). See license.
The CoRal project is funded by the Danish Innovation Fund and consists of the following partners:
We will submit a research paper soon, but until then, if you use this model in your research or development, please cite it as follows:
@dataset{coral2024,
  author    = {Dan Saattrup Nielsen, Sif Bernstorff Lehmann, Simon Leminen Madsen, Anders Jess Pedersen, Anna Katrine van Zee, Anders Søgaard and Torben Blach},
  title     = {CoRal: A Diverse Danish ASR Dataset Covering Dialects, Accents, Genders, and Age Groups},
  year      = {2024},
  url       = {https://hf.co/datasets/alexandrainst/coral},
}