
Downloads · 30 days
223
2% of all-time downloads
ChristianAzinn/gist-embedding-v0-gguf
gist-embedding-v0-gguf is a feature extraction model from ChristianAzinn. Use it when you need embeddings to search or compare text. It is set up for sentence-transformers. The card lists the license as mit.
Downloads · 30 days
223
2% of all-time downloads
All-time downloads
9.1K
Public
Repo size
1.6 GB
Likes
0
Public
Click a slice to open those files.
.gguf1.6 GB · 100%
From the Hugging Face model README
Model creator: avsolatorio
Original model: GIST-Embedding-v0
GISTEmbed: Guided In-sample Selection of Training Negatives for Text Embedding Fine-tuning
The model is fine-tuned on top of the BAAI/bge-base-en-v1.5 using the MEDI dataset augmented with mined triplets from the MTEB Classification training dataset (excluding data from the Amazon Polarity Classification task).
The model does not require any instruction for generating embeddings. This means that queries for retrieval tasks can be directly encoded without crafting instructions.
Technical paper: GISTEmbed: Guided In-sample Selection of Training Negatives for Text Embedding Fine-tuning
The dataset used is a compilation of the MEDI and MTEB Classification training datasets. Third-party datasets may be subject to additional terms and conditions under their associated licenses. A HuggingFace Dataset version of the compiled dataset, and the specific revision used to train the model, is available:
The dataset contains a task_type key, which can be used to select only the mteb classification tasks (prefixed with mteb_).
The MEDI Dataset is published in the following paper: One Embedder, Any Task: Instruction-Finetuned Text Embeddings.
The MTEB Benchmark results of the GIST embedding model, compared with the base model, suggest that the fine-tuning dataset has perturbed the model considerably, which resulted in significant improvements in certain tasks while adversely degrading performance in some.
The retrieval performance for the TRECCOVID task is of note. The fine-tuning dataset does not contain significant knowledge about COVID-19, which could have caused the observed performance degradation. We found some evidence, detailed in the paper, that thematic coverage of the fine-tuning data can affect downstream performance.
This repo contains GGUF format files for the GIST-Embedding-v0 embedding model.
These files were converted and quantized with llama.cpp PR 5500, commit 34aa045de, on a consumer RTX 4090.
This model supports up to 512 tokens of context.
These files are compatible with llama.cpp as of commit 4524290e8, as well as LM Studio as of version 0.2.19.
| Name | Quant method | Bits | Size | Max RAM required | Use case |
|---|---|---|---|---|---|
| Name | Quant method | Bits | Size | Use case | |
| gist-embedding-v0.Q2_K.gguf | Q2_K | 2 | 54.2 MB | smallest, significant quality loss - not recommended for most purposes | |
| gist-embedding-v0.Q3_K_S.gguf | Q3_K_S | 3 | 58.5 MB | very small, high quality loss | |
| gist-embedding-v0.Q3_K_M.gguf | Q3_K_M | 3 | 64.6 MB | very small, high quality loss | |
| gist-embedding-v0.Q3_K_L.gguf | Q3_K_L | 3 | 69.5 MB | small, substantial quality loss | |
| gist-embedding-v0.Q4_0.gguf | Q4_0 | 4 | 69.8 MB | legacy; small, very high quality loss - prefer using Q3_K_M | |
| gist-embedding-v0.Q4_K_S.gguf | Q4_K_S | 4 | 71 MB | small, greater quality loss | |
| gist-embedding-v0.Q4_K_M.gguf | Q4_K_M | 4 | 74.4 MB | medium, balanced quality - recommended | |
| gist-embedding-v0.Q5_0.gguf | Q5_0 | 5 | 80.4 MB | legacy; medium, balanced quality - prefer using Q4_K_M | |
| gist-embedding-v0.Q5_K_S.gguf | Q5_K_S | 5 | 80.4 MB | large, low quality loss - recommended | |
| gist-embedding-v0.Q5_K_M.gguf | Q5_K_M | 5 | 82.8 MB | large, very low quality loss - recommended | |
| gist-embedding-v0.Q6_K.gguf | Q6_K | 6 | 91.7 MB | very large, extremely low quality loss | |
| gist-embedding-v0.Q8_0.gguf | Q8_0 | 8 | 118 MB | very large, extremely low quality loss - recommended | |
| gist-embedding-v0.Q8_0.gguf | FP16 | 16 | 219 MB | enormous, pretty much the original model - not recommended | |
| gist-embedding-v0.Q8_0.gguf | FP32 | 32 | 436 MB | enormous, pretty much the original model - not recommended |
llama.cppTo compute a single embedding, build llama.cpp and run:
./embedding -ngl 99 -m [filepath-to-gguf].gguf -p 'search_query: What is TSNE?'
You can also submit a batch of texts to embed, as long as the total number of tokens does not exceed the context length. Only the first three embeddings are shown by the embedding example.
texts.txt:
search_query: What is TSNE?
search_query: Who is Laurens Van der Maaten?
Compute multiple embeddings:
./embedding -ngl 99 -m [filepath-to-gguf].gguf -f texts.txt
Download the 0.2.19 beta build from here: Windows MacOS Linux
Once installed, open the app. The home should look like this:

Search for either "ChristianAzinn" in the main search bar or go to the "Search" tab on the left menu and search the name there.

Select your model from those that appear (this example uses bge-small-en-v1.5-gguf) and select which quantization you want to download. Since this model is pretty small, I recommend Q8_0, if not f16/32. Generally, the lower you go in the list (or the bigger the number gets), the larger the file and the better the performance.
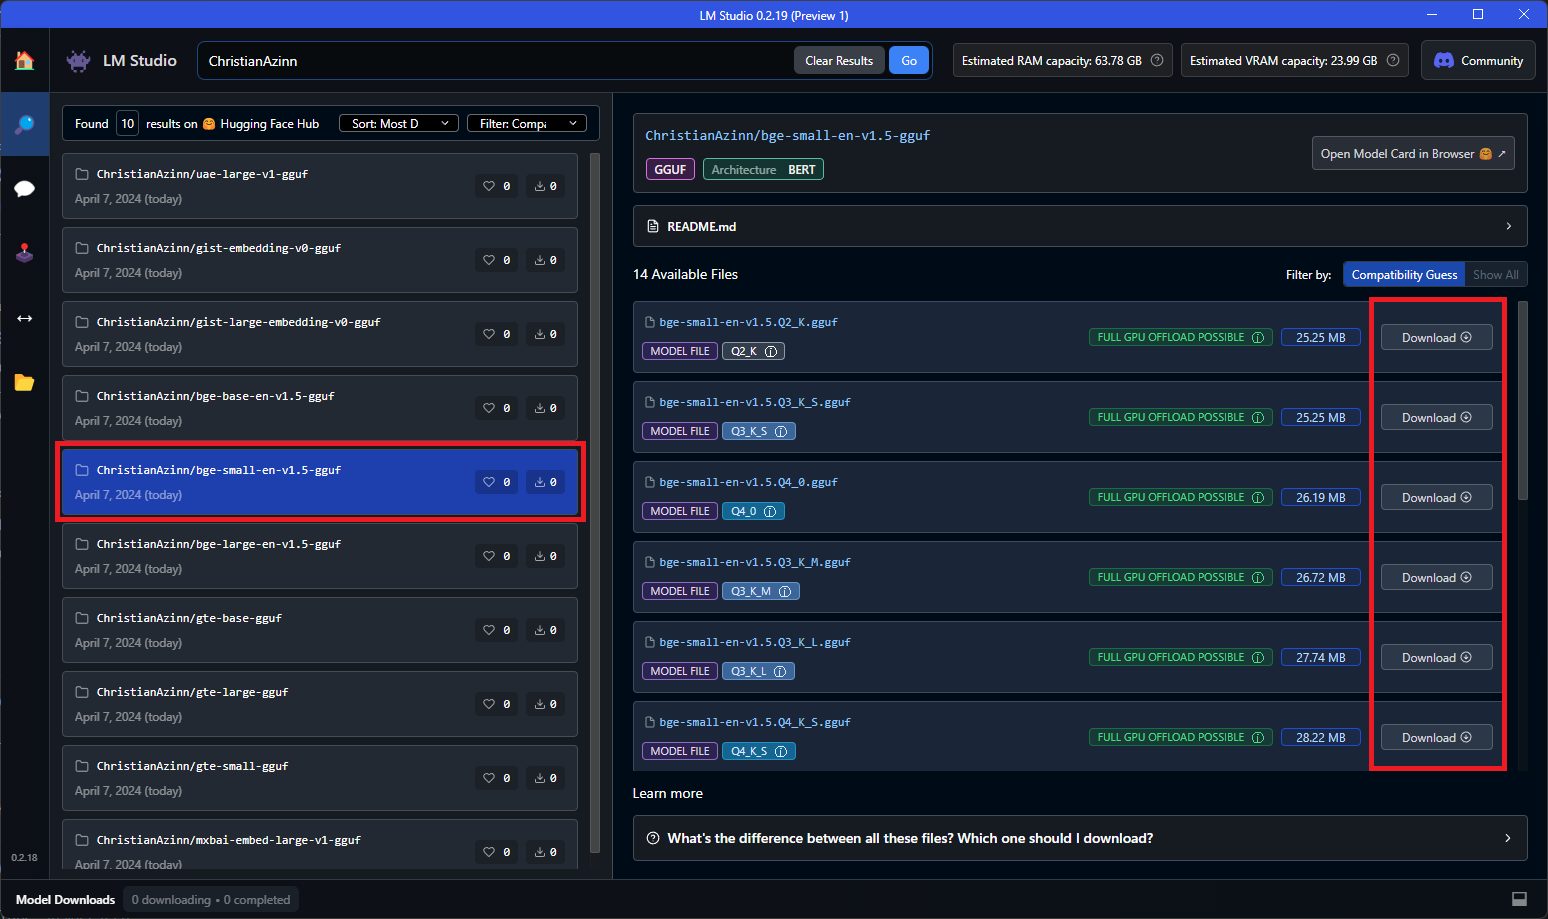
You will see a green checkmark and the word "Downloaded" once the model has successfully downloaded, which can take some time depending on your network speeds.

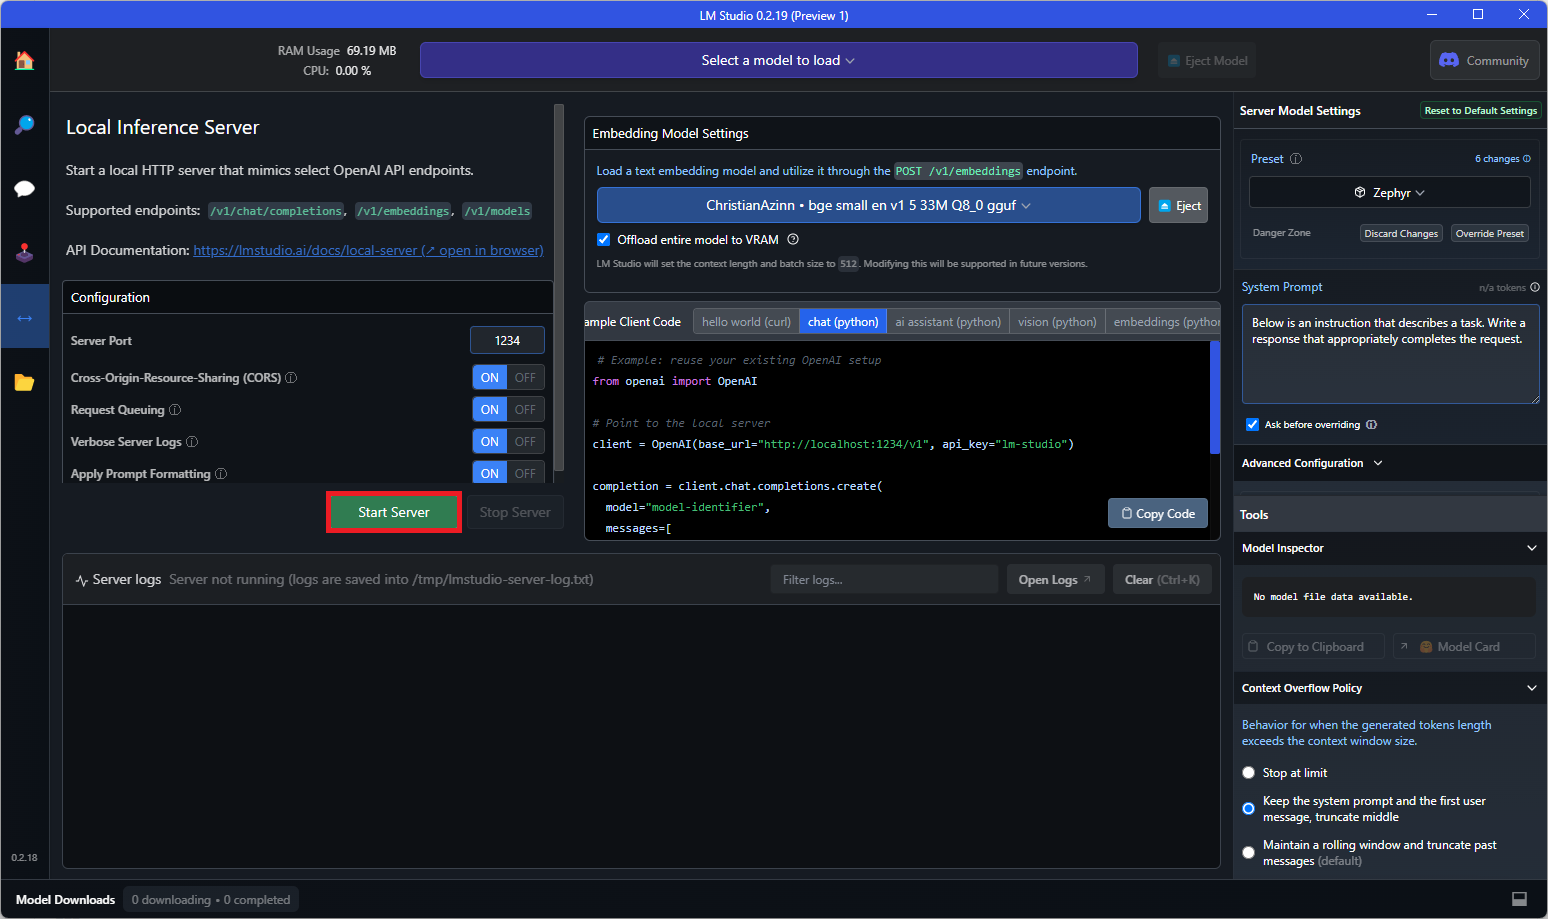
Once this model is finished downloading, navigate to the "Local Server" tab on the left menu and open the loader for text embedding models. This loader does not appear before version 0.2.19, so ensure you downloaded the correct version.

Select the model you just downloaded from the dropdown that appears to load it. You may need to play with configuratios in the right-side menu, such as GPU offload if it doesn't fit entirely into VRAM.

All that's left to do is to hit the "Start Server" button:
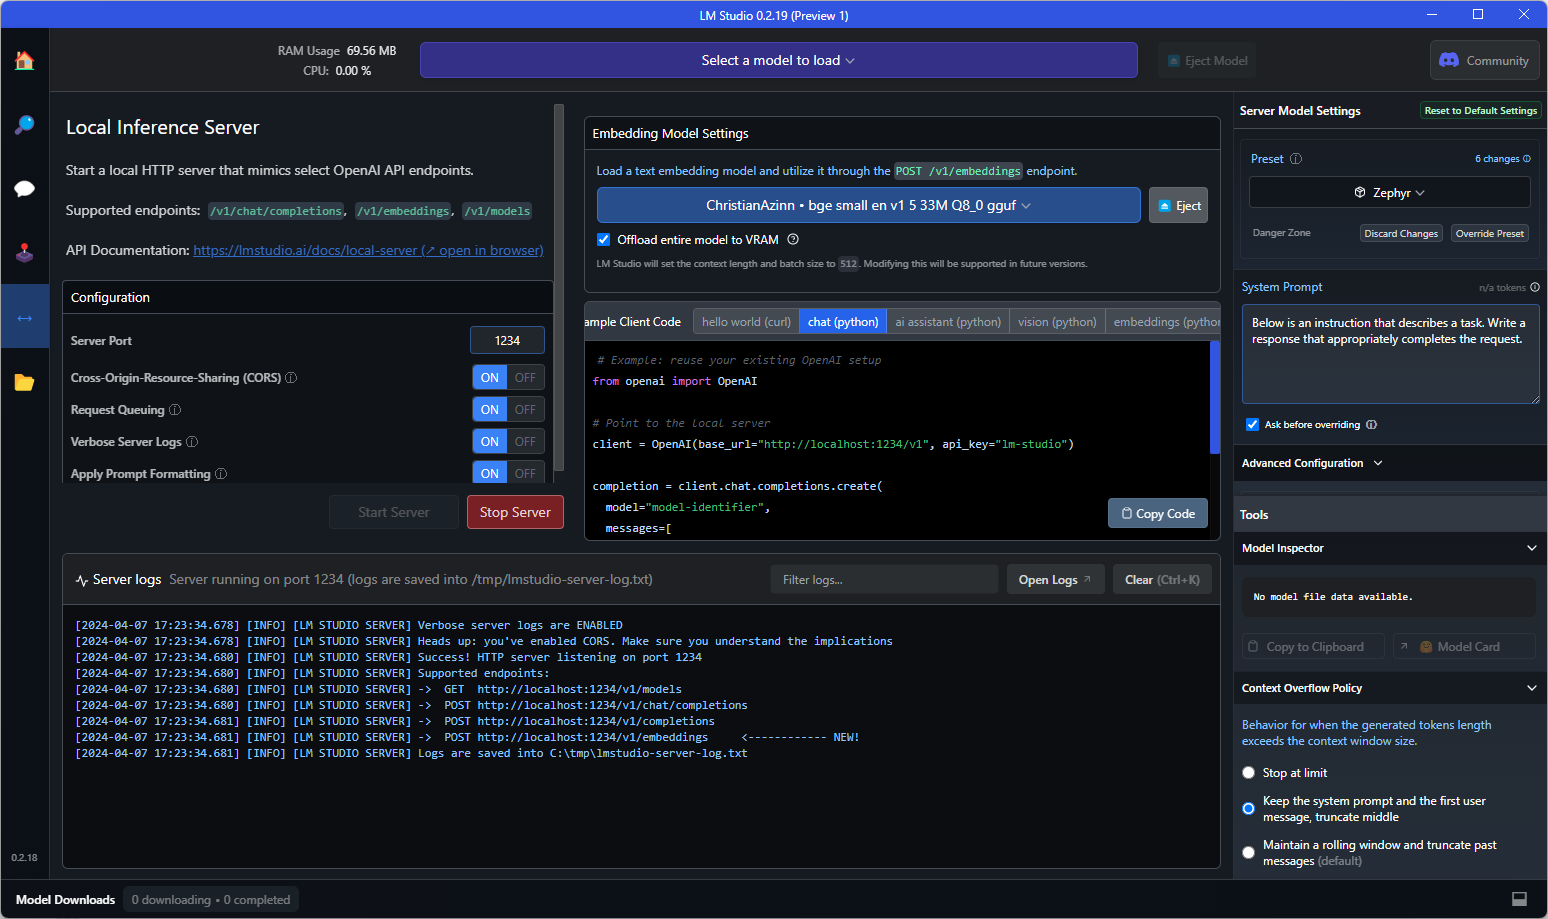
And if you see text like that shown below in the console, you're good to go! You can use this as a drop-in replacement for the OpenAI embeddings API in any application that requires it, or you can query the endpoint directly to test it out.
Example curl request to the API endpoint:
curl http://localhost:1234/v1/embeddings \
  -H "Content-Type: application/json" \
  -d '{
    "input": "Your text string goes here",
    "model": "model-identifier-here"
  }'
For more information, see the LM Studio text embedding documentation.
Thanks to the LM Studio team and everyone else working on open-source AI.
This README is inspired by that of nomic-ai-embed-text-v1.5-gguf, another excellent embedding model, and those of the legendary TheBloke.