
Downloads · 30 days
51
4% of all-time downloads
BitStarWalkin/SuperCorrect-7B
SuperCorrect-7B is a text generation model from BitStarWalkin. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
SuperCorrect: Supervising and Correcting Language Models with Error-Driven Insights Ling Yang\, Zhaochen Yu, Tianjun Zhang, Minkai Xu, Joseph E. Gonzalez,Bin Cui, Shuicheng Yan
Downloads · 30 days
51
4% of all-time downloads
All-time downloads
1.2K
Public
Parameters
7.6B
15.2 GB on disk
Likes
11
Public
Click a slice to open those files.
.safetensors15.2 GB · 100%
From the Hugging Face model README
<p align="left"> <a href='https://arxiv.org/abs/2410.09008'> <img src='https://img.shields.io/badge/Arxiv-2410.09008-A42C25?style=flat&logo=arXiv&logoColor=A42C25'></a> </p>SuperCorrect: Supervising and Correcting Language Models with Error-Driven Insights Ling Yang*, Zhaochen Yu*, Tianjun Zhang, Minkai Xu, Joseph E. Gonzalez,Bin Cui, Shuicheng Yan
Peking University, Skywork AI, UC Berkeley, Stanford University
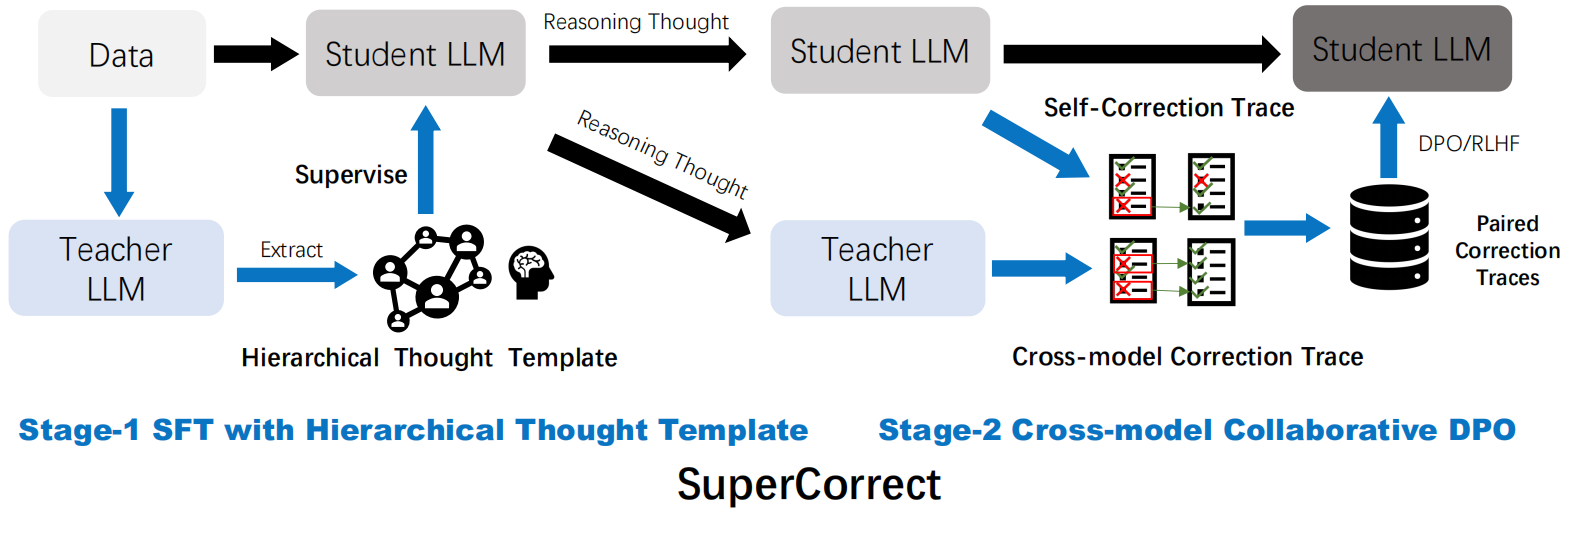
This repo provides the official implementation of SuperCorrect a novel two-stage fine-tuning method for improving both reasoning accuracy and self-correction ability for LLMs.
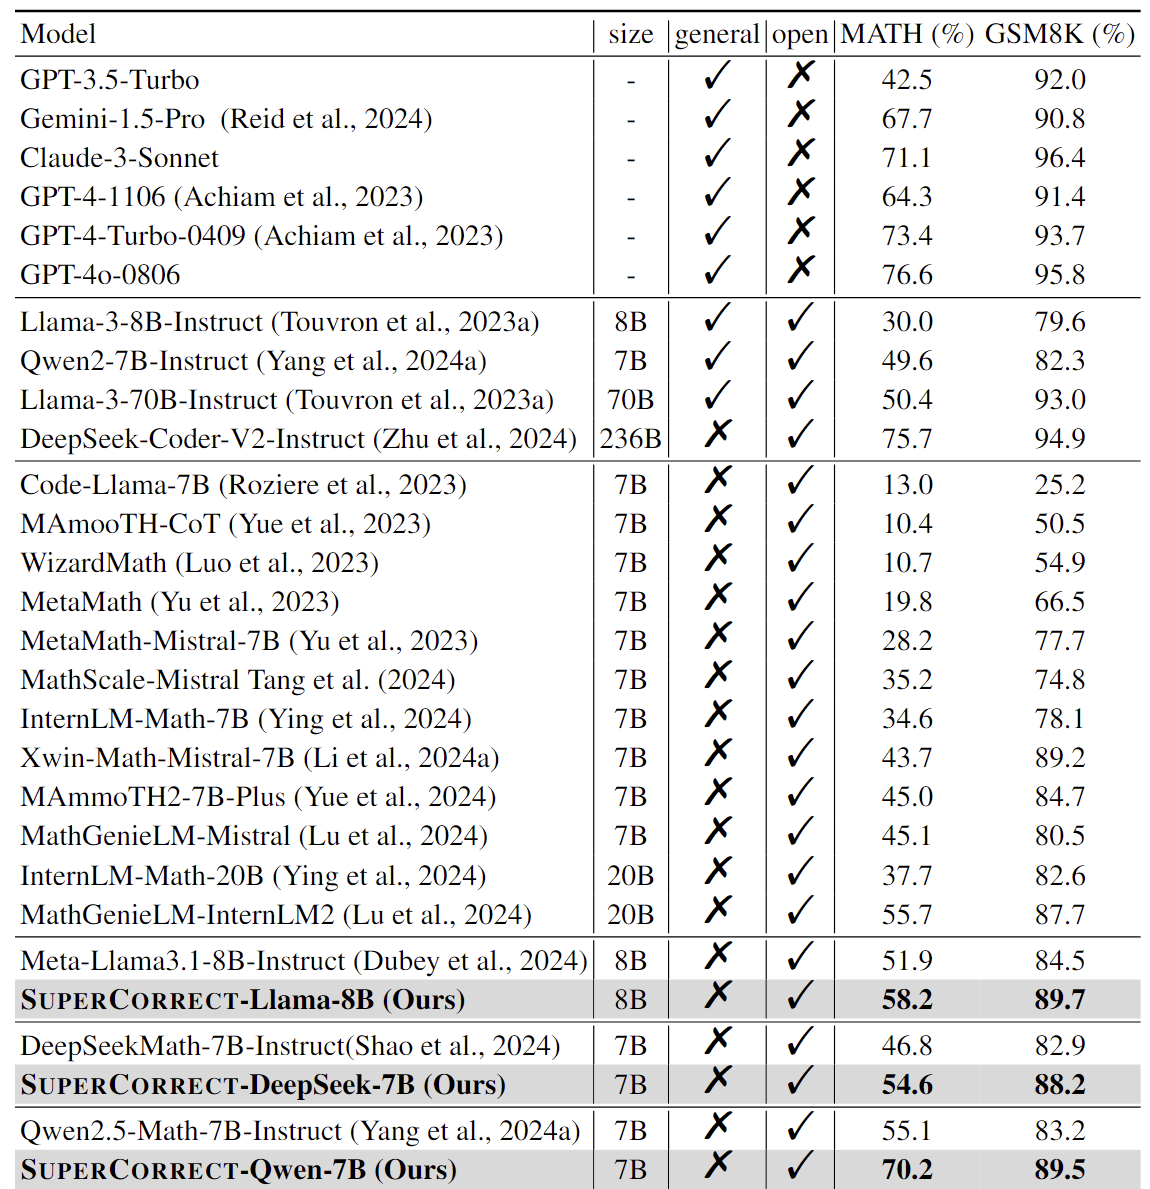
Notably, our SupperCorrect-7B model significantly surpasses powerful DeepSeekMath-7B by 7.8%/5.3% and Qwen2.5-Math-7B by 15.1%/6.3% on MATH/GSM8K benchmarks, achieving new SOTA performance among all 7B models.
<div align="left"> 🚨 Unlike other LLMs, we incorporate LLMs with our pre-defined hierarchical thought template ([Buffer of Thought (BoT)](https://github.com/YangLing0818/buffer-of-thought-llm)) to conduct more deliberate reasoning than conventional CoT. It should be noted that our evaluation methods relies on pure mathematical reasoning abilities of LLMs, instead of leverage other programming methods such as PoT and ToRA. </div>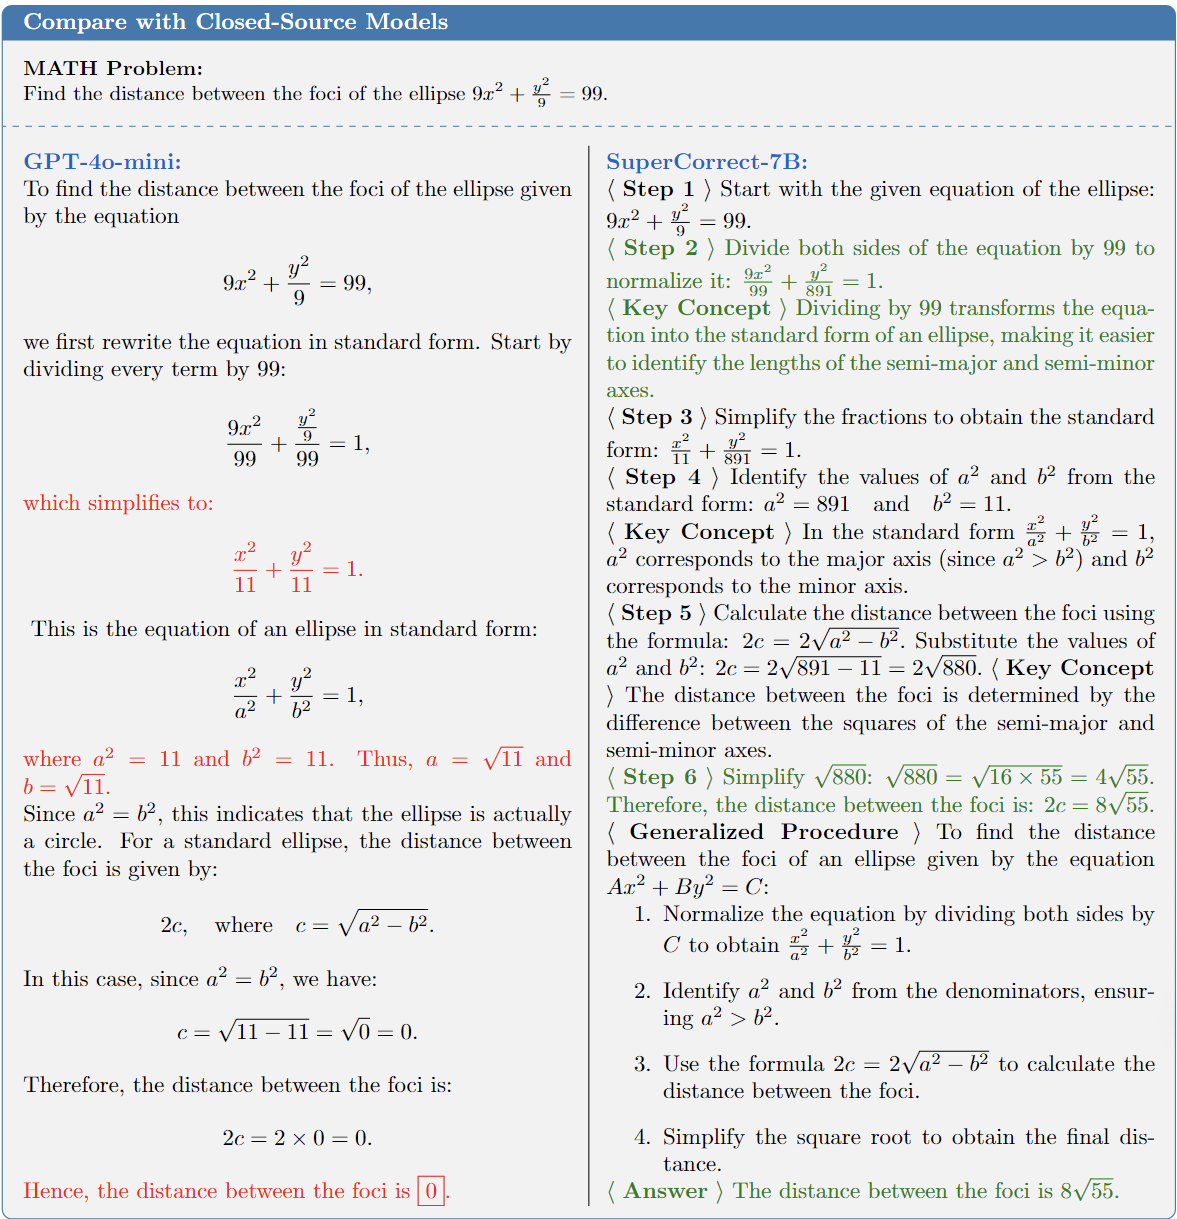
You can check our Github repo for more details.
transformers>=4.37.0 is needed for Qwen2.5-Math models. The latest version is recommended.[!Warning]
<div align="center"> <b> 🚨 This is a must because `transformers` integrated Qwen2 codes since `4.37.0`. </b> </div>
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "BitStarWalkin/SuperCorrect-7B"
device = "cuda"

model = AutoModelForCausalLM.from_pretrained(
    model_name,
    torch_dtype="auto",
    device_map="auto"
)
tokenizer = AutoTokenizer.from_pretrained(model_name)

prompt = "Find the distance between the foci of the ellipse \[9x^2 + \frac{y^2}{9} = 99.\]"
hierarchical_prompt = "Solve the following math problem in a step-by-step XML format, each step should be enclosed within tags like <Step1></Step1>. For each step enclosed within the tags, determine if this step is challenging and tricky, if so, add detailed explanation and analysis enclosed within <Key> </Key> in this step, as helpful annotations to help you thinking and remind yourself how to conduct reasoning correctly. After all the reasoning steps, summarize the common solution and reasoning steps to help you and your classmates who are not good at math generalize to similar problems within <Generalized></Generalized>. Finally present the final answer within <Answer> </Answer>."
# HT
messages = [
    {"role": "system", "content":hierarchical_prompt },
    {"role": "user", "content": prompt}
]

text = tokenizer.apply_chat_template(
    messages,
    tokenize=False,
    add_generation_prompt=True
)
model_inputs = tokenizer([text], return_tensors="pt").to(device)

generated_ids = model.generate(
    **model_inputs,
    max_new_tokens=1024
)
generated_ids = [
    output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)
]

response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
print(response)
We evaluate our SupperCorrect-7B on two widely used English math benchmarks GSM8K and MATH. All evaluations are tested with our evaluation method which is zero-shot hierarchical thought based prompting.
@article{yang2024supercorrect,
title={SuperCorrect: Supervising and Correcting Language Models with Error-Driven Insights}
  author={Yang, Ling and Yu, Zhaochen and Zhang, Tianjun and Xu, Minkai and Gonzalez, Joseph E and Cui, Bin and Yan, Shuicheng},
  journal={arXiv preprint arXiv:2410.09008},
  year={2024}
}
@article{yang2024buffer,
  title={Buffer of Thoughts: Thought-Augmented Reasoning with Large Language Models},
  author={Yang, Ling and Yu, Zhaochen and Zhang, Tianjun and Cao, Shiyi and Xu, Minkai and Zhang, Wentao and Gonzalez, Joseph E and Cui, Bin},
  journal={arXiv preprint arXiv:2406.04271},
  year={2024}
}
Our SuperCorrect is a two-stage fine-tuning model which based on several extraordinary open-source models like Qwen2.5-Math, DeepSeek-Math, Llama3-Series. Our evaluation method is based on the code base of outstanding works like Qwen2.5-Math and lm-evaluation-harness. We also want to express our gratitude for amazing works such as BoT which provides the idea of thought template.