
Downloads · 30 days
20
1% of all-time downloads
AshtonIsNotHere/xlm-roberta-long-base-4096
xlm-roberta-long-base-4096 is a fill-mask model from AshtonIsNotHere. Use it when you need the model to fill a missing word. It is set up for transformers. The card lists the license as apache-2.0.
This is an XLM-RoBERTa longformer model that was pre-trained from the XLM-RoBERTa checkpoint using the Longformer pre-training scheme on the English WikiText-103 corpus.
Downloads · 30 days
20
1% of all-time downloads
All-time downloads
2.5K
Public
Repo size
3.7 GB
Likes
1
Public
Click a slice to open those files.
.bin1.2 GB · 100%
From the Hugging Face model README
This is an XLM-RoBERTa longformer model that was pre-trained from the XLM-RoBERTa checkpoint using the Longformer pre-training scheme on the English WikiText-103 corpus.
This model is identical to markussagen's xlm-r longformer model, the difference being that the weights have been transferred to a Longformer model, in order to enable loading with AutoModel.from_pretrained() without external dependencies.
Note that this model requires a considerable amount of memory to run. The heatmap below should give a relative idea of the amount of memory needed at inference for a target batch and sequence length. N.B. data for this plot was generated by running on a single a100 GPU with 40gb of memory.
<details> <summary>View Inference Memory Plot</summary>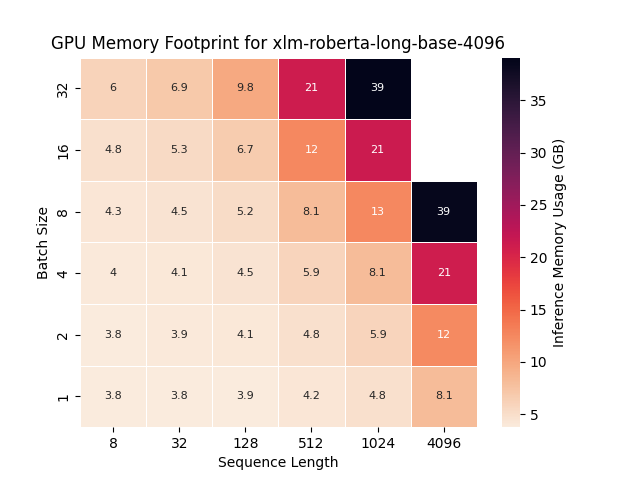
The model can be used as expected to fine-tune on a downstream task.
For instance for QA.
import torch
from transformers import AutoModel, AutoTokenizer
MAX_SEQUENCE_LENGTH = 4096
MODEL_NAME_OR_PATH = "AshtonIsNotHere/xlm-roberta-long-base-4096"
tokenizer = AutoTokenizer.from_pretrained(
    MODEL_NAME_OR_PATH,
    max_length=MAX_SEQUENCE_LENGTH,
    padding="max_length",
    truncation=True,
)
model = AutoModelForQuestionAnswering.from_pretrained(
    MODEL_NAME_OR_PATH,
    max_length=MAX_SEQUENCE_LENGTH,
)