
Downloads · 30 days
130
1% of all-time downloads
Aratako/Qwen1.5-MoE-2x7B
Qwen1.5-MoE-2x7B is a text generation model from Aratako. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as other.
This model is created using MoE (Mixture of Experts) through mergekit based on Qwen/Qwen1.5-7B-Chat and abacusai/Liberated-Qwen1.5-7B without further FT.
Downloads · 30 days
130
1% of all-time downloads
All-time downloads
12.7K
Public
Parameters
12.1B
24.1 GB on disk
Likes
4
Public
Click a slice to open those files.
.safetensors24.1 GB · 100%
From the Hugging Face model README
This model is created using MoE (Mixture of Experts) through mergekit based on Qwen/Qwen1.5-7B-Chat and abacusai/Liberated-Qwen1.5-7B without further FT.
It utilizes a customized script for MoE via mergekit, which is available here.
Due to the structural modifications introduced by MoE, the use of this model requires custom modeling file and custom configuration file. When using the model, please place these files in the same folder as the model.
This model inherits the the tongyi-qianwen license.
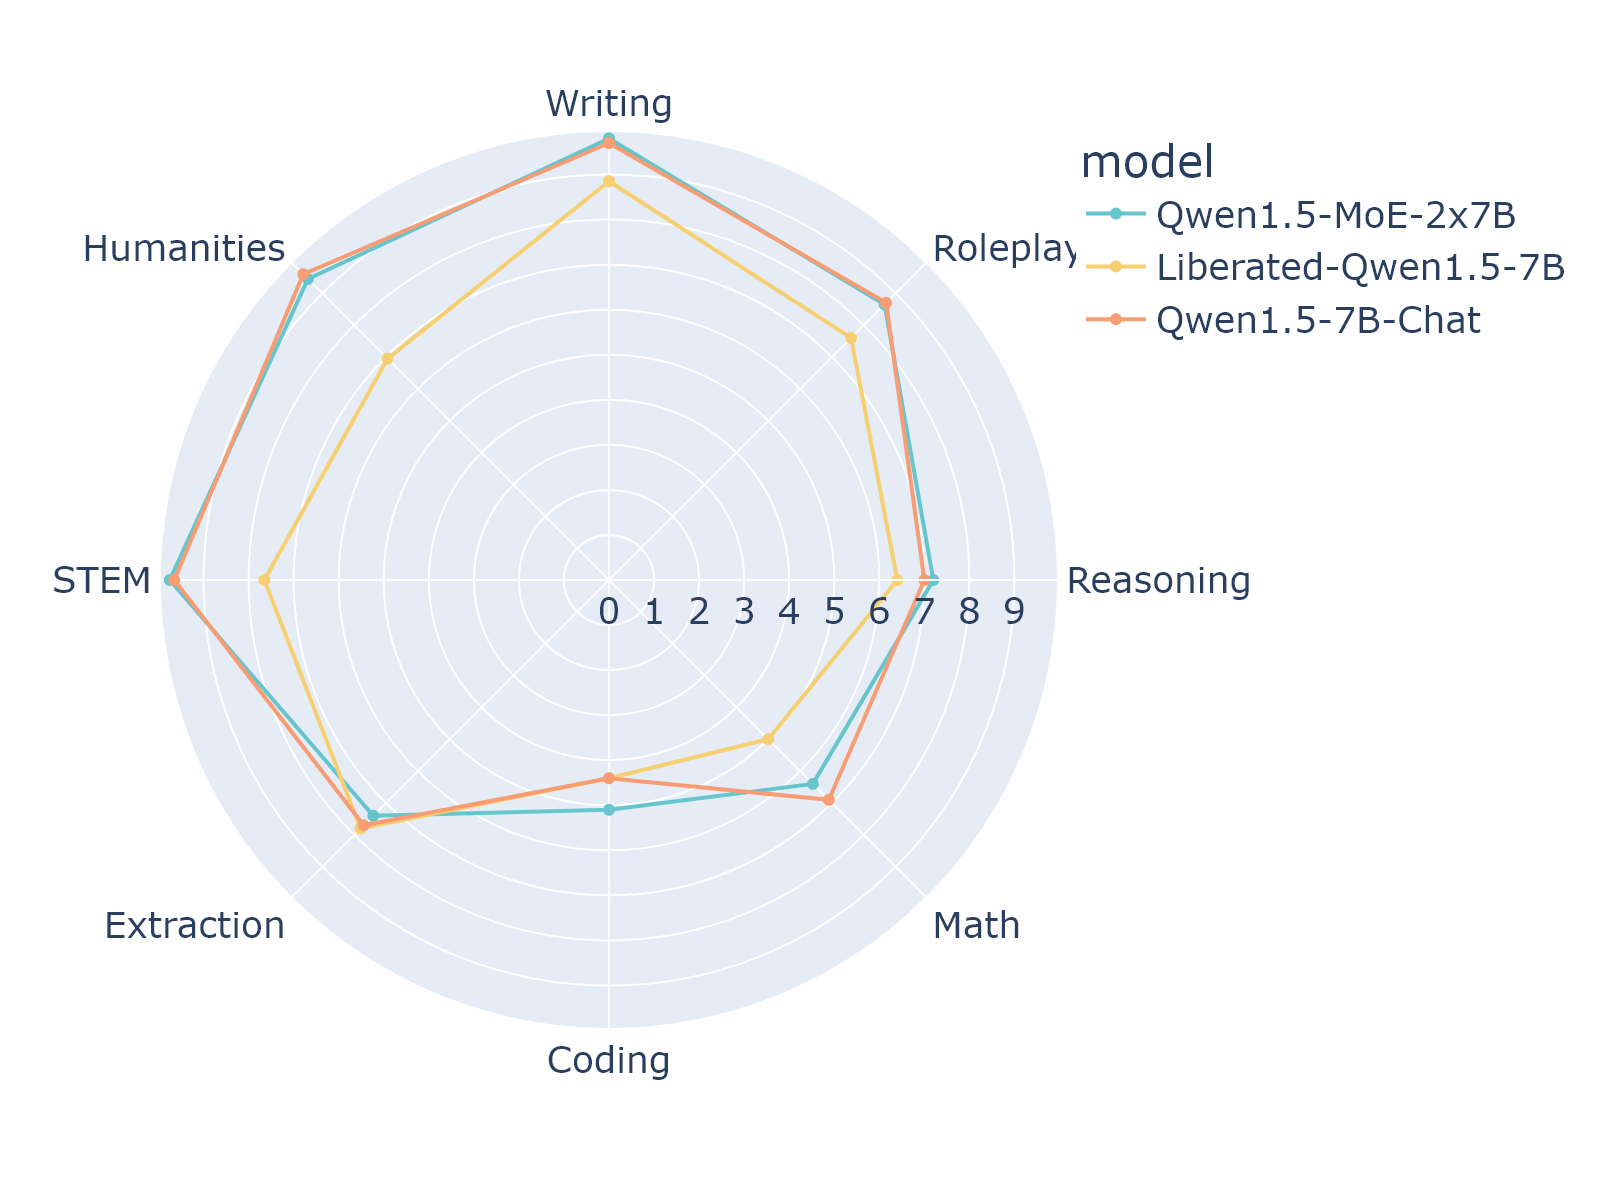
The benchmark score of the mt-bench for this model and the two base models are as follows:
1-turn
| Model | Size | Coding | Extraction | Humanities | Math | Reasoning | Roleplay | STEM | Writing | avg_score |
|---|---|---|---|---|---|---|---|---|---|---|
| Liberated-Qwen1.5-7B | 7B | 4.4 | 7.8 | 6.95 | 5.0 | 6.4 | 7.6 | 7.65 | 8.85 | 6.83125 |
| Qwen1.5-7B-Chat | 7B | 4.4 | 7.7 | 9.6 | 6.9 | 7.0 | 8.7 | 9.65 | 9.7 | 7.95625 |
| This model | 2x7B | 5.1 | 7.4 | 9.45 | 6.4 | 7.2 | 8.65 | 9.75 | 9.8 | 7.96875 |
2-turn
| Model | Size | Coding | Extraction | Humanities | Math | Reasoning | Roleplay | STEM | Writing | avg_score |
|---|---|---|---|---|---|---|---|---|---|---|
| Liberated-Qwen1.5-7B | 7B | 4.4 | 6.2 | 7.1 | 3.0 | 5.7 | 7.4 | 6.3 | 3.5 | 5.450 |
| Qwen1.5-7B-Chat | 7B | 4.5 | 8.0 | 9.9 | 4.9 | 5.0 | 8.9 | 9.4 | 8.4 | 7.375 |
| This model | 2x7B | 4.7 | 7.0 | 10.0 | 4.8 | 4.3 | 8.6 | 9.5 | 7.3 | 7.025 |
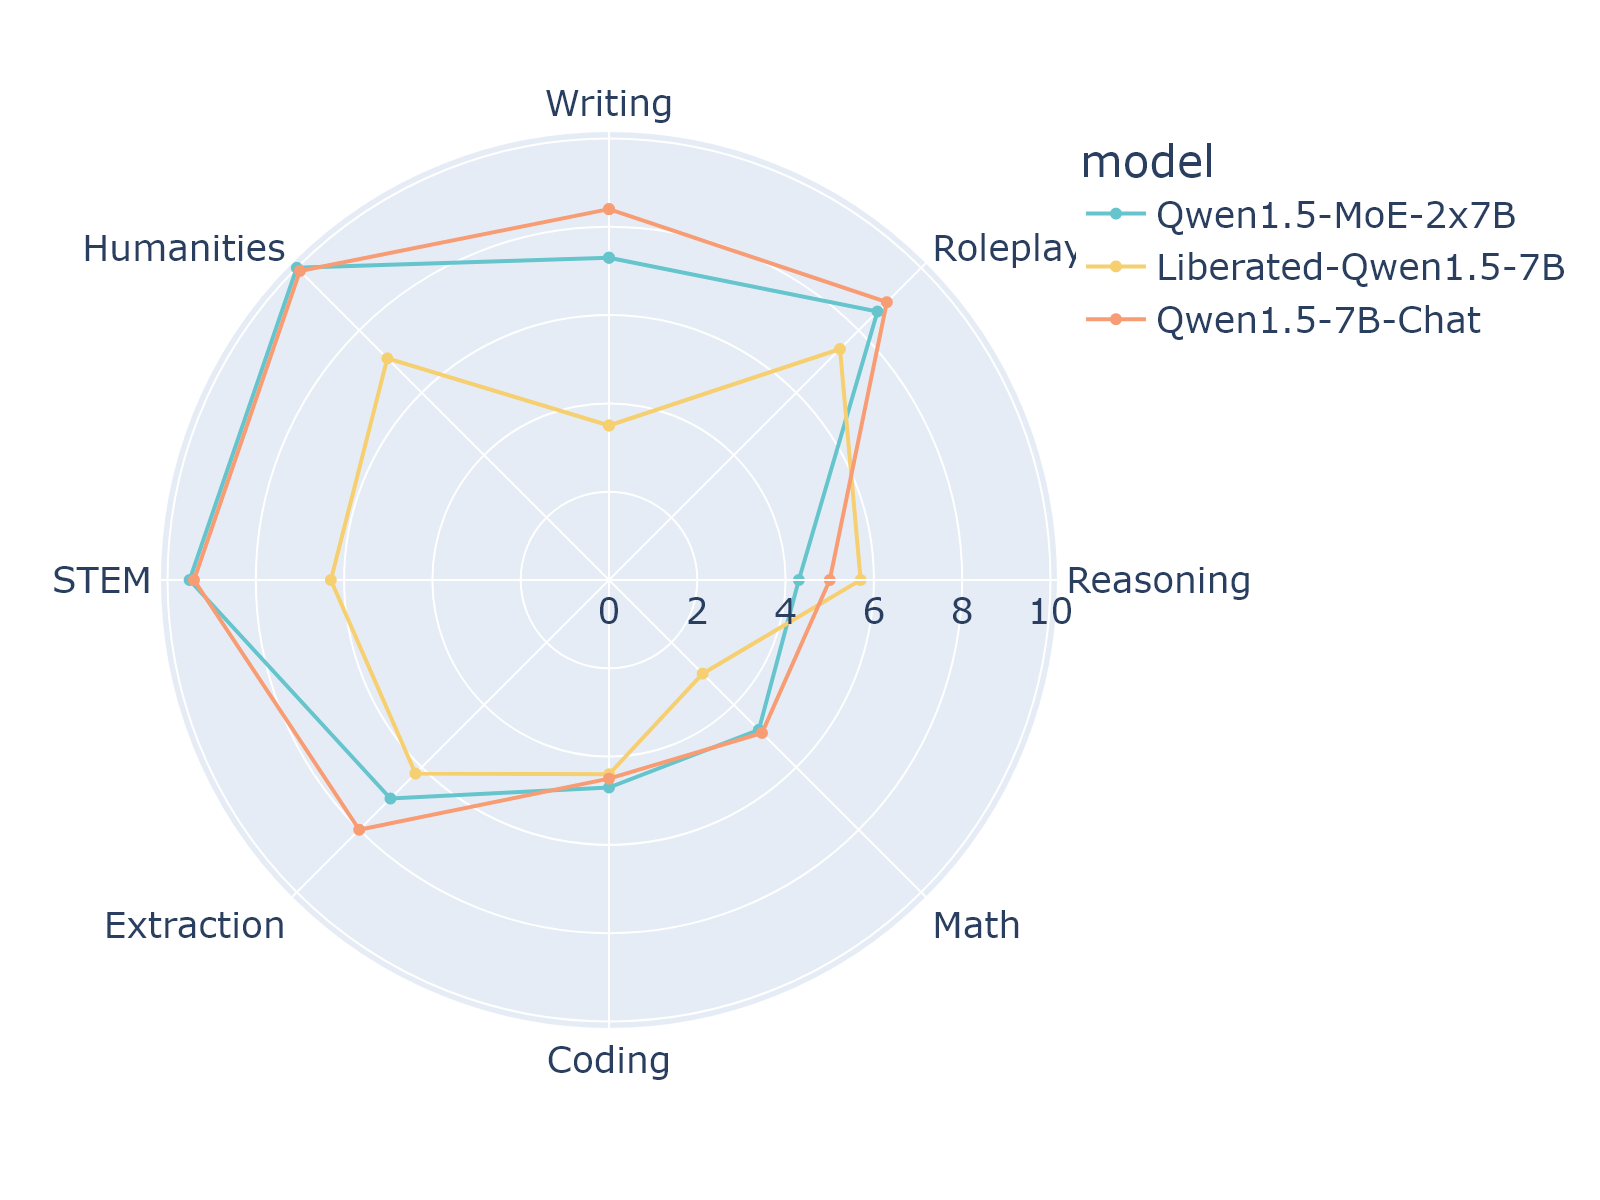
Although the benchmark scores have slightly deteriorated, it seems that this is due to the poor performance of the Liberated-Qwen1.5-7B model used in the merge on mt-bench. I think that doing MoE with models that have better performance or are fine-tuned for specific tasks can yield better results.
base_model: ./Qwen1.5-7B-Chat
gate_mode: random
dtype: bfloat16
experts:
  - source_model: ./Qwen1.5-7B-Chat
    positive_prompts: []
  - source_model: ./Liberated-Qwen1.5-7B
    positive_prompts: []
tokenizer_source: model:./Qwen1.5-7B-Chat