Downloads · 30 days
0
Antiraedus/test-text2Live
test-text2Live is a machine learning model from Antiraedus. Use it for the machine learning task on the model card, and read the license before you ship it in a product.
[](https://arxiv.org/abs/2204.02491) [](https://huggingface.co/spaces/weizmannscience/text2live)
Downloads · 30 days
0
Access
Public
Updated Feb 17, 2023
Repo size
79 MB
Likes
1
Public
Click a slice to open those files.
.zip79 MB · 100%
From the Hugging Face model README


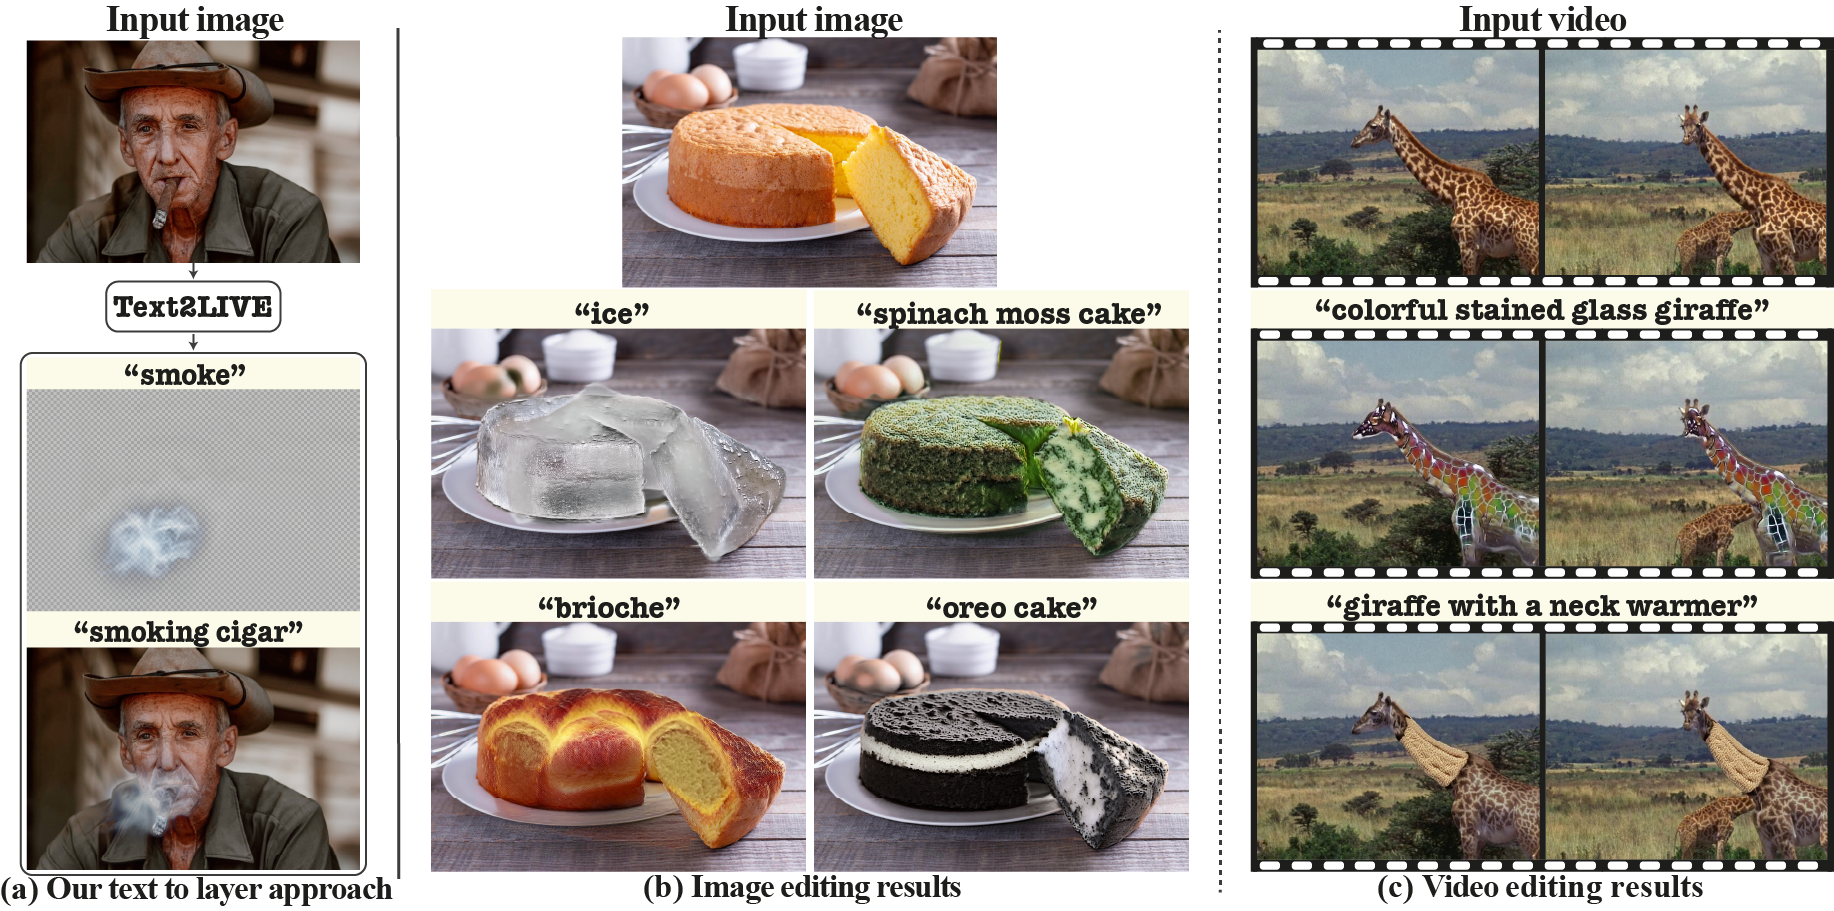
Text2LIVE is a method for text-driven editing of real-world images and videos, as described in <a href="https://arxiv.org/abs/2204.02491" target="_blank">(link to paper)</a>.
We present a method for zero-shot, text-driven appearance manipulation in natural images and videos. Specifically, given an input image or video and a target text prompt, our goal is to edit the appearance of existing objects (e.g., object's texture) or augment the scene with new visual effects (e.g., smoke, fire) in a semantically meaningful manner. Our framework trains a generator using an internal dataset of training examples, extracted from a single input (image or video and target text prompt), while leveraging an external pre-trained CLIP model to establish our losses. Rather than directly generating the edited output, our key idea is to generate an edit layer (color+opacity) that is composited over the original input. This allows us to constrain the generation process and maintain high fidelity to the original input via novel text-driven losses that are applied directly to the edit layer. Our method neither relies on a pre-trained generator nor requires user-provided edit masks. Thus, it can perform localized, semantic edits on high-resolution natural images and videos across a variety of objects and scenes.
git clone https://github.com/omerbt/Text2LIVE.git
conda create --name text2live python=3.9
conda activate text2live
pip install -r requirements.txt
Download sample images and videos from the DAVIS dataset:
cd Text2LIVE
gdown https://drive.google.com/uc?id=1osN4PlPkY9uk6pFqJZo8lhJUjTIpa80J&export=download
unzip data.zip
It will create a folder data:
Text2LIVE
├── ...
├── data
│   ├── pretrained_nla_models # NLA models are stored here
│   ├── images # sample images
│   └── videos # sample videos from DAVIS dataset
│         ├── car-turn # contains video frames
│         ├── ...
└── ...
To enforce temporal consistency in video edits, we utilize the Neural Layered Atlases (NLA). Pretrained NLA models are taken from <a href="https://layered-neural-atlases.github.io">here</a>, and are already inside the data folder.
The required GPU memory depends on the input image/video size, but you should be good with a Tesla V100 32GB :). Currently mixed precision introduces some instability in the training process, but it could be added later.
Run the following command to start training
python train_video.py --example_config car-turn_winter.yaml
Run the following command to start training
python train_image.py --example_config golden_horse.yaml
Intermediate results will be saved to results during optimization. The frequency of saving intermediate results is indicated in the log_images_freq flag of the configuration.
For more see the supplementary material.
@inproceedings{bar2022text2live,
  title={Text2live: Text-driven layered image and video editing},
  author={Bar-Tal, Omer and Ofri-Amar, Dolev and Fridman, Rafail and Kasten, Yoni and Dekel, Tali},
  booktitle={European Conference on Computer Vision},
  pages={707--723},
  year={2022},
  organization={Springer}
}