
Downloads · 30 days
168K
20% of all-time downloads
AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5-GGUF
Parable-Granite-4.1-8B-Claude-Fable-5-GGUF is a text generation model from AnkitAI. Use it when you need the model to write or continue text. It is set up for gguf. The card lists the license as apache-2.0.
<picture <source media="(prefers-color-scheme: dark)" srcset="https://raw.githubusercontent.com/ankit-aglawe/parable-assets/main/parableheaderdark.png" <img alt="Parable" src="https://raw.githubusercontent.com/ankit-a…
Downloads · 30 days
168K
20% of all-time downloads
All-time downloads
844K
Public
Repo size
70.5 GB
Likes
5
Public
Click a slice to open those files.
.gguf43.6 GB · 100%
From the Hugging Face model README
<think> reasoning distilled from real Claude Fable 5 and GPT-5.5 agent sessions — 70% lower held-out test loss than its base, and past the 0.71 mark the 9B-class incumbent reports on this data family.~6 GB of RAM is all you need. The Q4 build fits comfortably on an ordinary laptop or a mid-range GPU. One command and you have a private, offline reasoning model on your machine:
ollama run hf.co/AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5-GGUF:Q4_K_M
Parable-Granite-4.1-8B is an ibm-granite/granite-4.1-8b fine-tune trained on real multi-step agent sessions: planning, tool use, and <think> reasoning captured from actual Claude Fable 5 and GPT-5.5 agent work, not synthetic Q&A. It is the largest release in the Parable series.
🔮 v2 is coming. The 3B just got the v2 treatment (13× corpus, rebuilt recipe) — the same upgrade lands here next. Same links, in-place.
📦 Full family. This 8B is the largest Parable. Also available: 3B Granite, 8B Qwen, 4B Qwen — same recipe, no matter your hardware. Everything lives in the Parable collection.
| File | Size | Fits in | Notes |
|---|---|---|---|
| Q4_K_M | 4.8 GB | ~6 GB RAM/VRAM | ⭐ Recommended — best size/quality balance |
| Q5_K_M | 5.6 GB | ~7 GB | Higher quality |
| Q6_K | 6.4 GB | ~7.5 GB | Near-lossless |
| Q8_0 | 8.3 GB | ~9.5 GB | Maximum quality |
Full-precision safetensors (vLLM, transformers, further fine-tuning): Parable-Granite-4.1-8B-Claude-Fable-5
Ollama (shorter command via the Parable namespace, or pull directly from this repo):
ollama run parable/granite4.1-fable:8b
# or straight from this repo:
ollama run hf.co/AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5-GGUF:Q4_K_M
llama.cpp:
llama-cli -m Parable-Granite-4.1-8B-Claude-Fable-5-GGUF-Q4_K_M.gguf --jinja \
  -p "Write a bash one-liner to find the 10 largest files in a directory tree."
LM Studio: lms get parable/granite4.1-fable (parable on LM Studio Hub), or paste this repo URL.
Python (llama-cpp-python):
from llama_cpp import Llama

llm = Llama.from_pretrained(
    repo_id="AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5-GGUF",
    filename="*Q4_K_M.gguf", n_ctx=8192,
)
out = llm.create_chat_completion(
    messages=[{"role": "user", "content": "Write a Python function that retries an HTTP request with exponential backoff."}],
    max_tokens=3000, temperature=0.7,
)
print(out["choices"][0]["message"]["content"])
Every answer opens with a <think>...</think> reasoning block before the final answer — a behavior this fine-tune adds to Granite. llama.cpp's --jinja chat mode separates it automatically; strip it before showing replies to end users.
Sampling: temperature 0.7, top_p 0.95, and budget max_tokens generously (at least 2500) — trace-trained models think at length before answering.
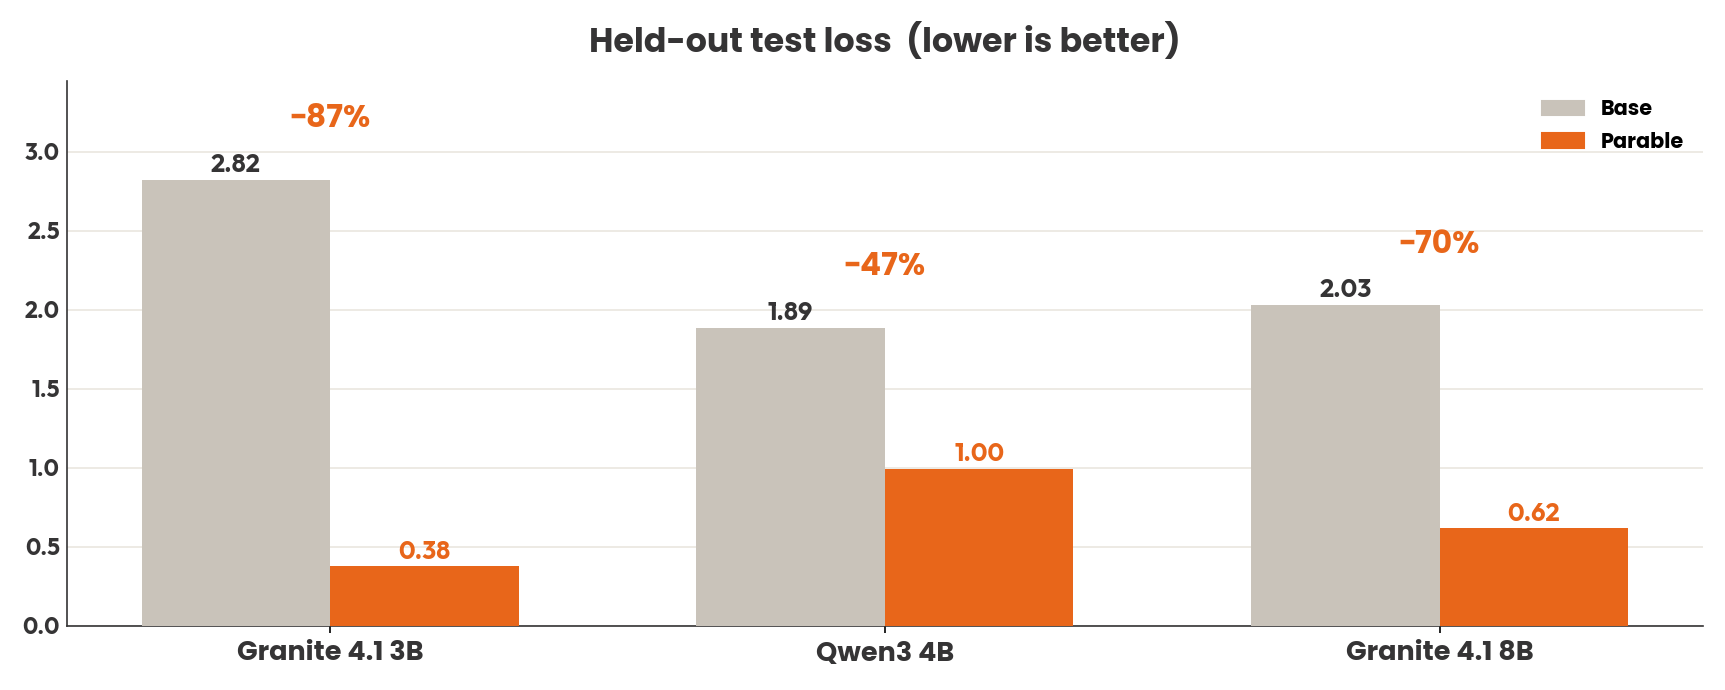
Held-out test split, identical evaluation code and context length for base and fine-tune:
| Metric | Base Granite-4.1-8B | Parable | Δ |
|---|---|---|---|
| Test loss | 2.030 | 0.617 | −70% |
Qualitative review (34 coding/terminal/debugging prompts, strictly graded by mentally executing every answer): 20/34 fully correct, 32/34 correct or partially correct. We publish these numbers because strict qualitative grading is rare in this niche; judge accordingly.
For reference, the strongest published fine-tune on this data family (a 9B) reports 0.71 validation loss. Cross-repo numbers are indicative only: splits, tokenizers, and context lengths differ (ours is measured at 1,024 tokens).
Measured 2026-07-29: bfcl-eval at gorilla main, prompting mode, Q4_K_M
GGUFs served by llama.cpp on a T4, base and Parable under the identical
harness. Categories: simple_python / multiple / parallel /
parallel_multiple (400/200/200/200 items). Raw generations and score
files: parable-v2-artifacts
under verify/bfcl/.
DNF. The run hit its 3-hour GPU budget: this chat variant's think blocks push most responses to the 4,096-token per-request cap, about 35 GPU-hours of decode for the full suite at T4 speed, so it cannot complete under the same budget every other row got. We report that rather than tightening the token cap for one model. For function-calling harnesses, use the base model; the 3B sibling's card shows the measured pattern on these categories.
<think> reasoning and tool calls (AGPL-3.0)Every example passed a quality gate (schema validation, secrets scrub, length filtering) before training. QLoRA fine-tune (NF4, sequence length 1024) trained on a single 16 GB GPU, quantized with llama.cpp.
Weights: Apache-2.0 (inherited from ibm-granite/granite-4.1-8b). Training data: Fable-5-traces AGPL-3.0, gpt5.5-terminal MIT — because those traces originate from third-party assistants, the providers' terms may apply to downstream training and distillation. If you plan to build on this model commercially, confirm your use aligns with those terms.
| Platform | |
|---|---|
| Ollama | ollama run parable/granite4.1-fable:8b · parable namespace |
| Ollama (family flagship, best per size) | ollama run parable/fable |
| Hugging Face | GGUF quants, full weights, eval reports |
| LM Studio | lms get parable/granite4.1-fable (parable on LM Studio Hub) |
If this model is useful in your work, you can support independent research:
<p align="left"> <a href="https://www.buymeacoffee.com/AnkitAI" target="_blank"><img src="https://cdn.buymeacoffee.com/buttons/v2/default-yellow.png" alt="Buy Me a Coffee" height="60" width="217" /></a> </p>The recipe, evaluation methodology and failure analysis behind this model are documented in the tech report:
Aglawe, A. (2026). Agent-Trace Fine-Tuning of Small Language Models under Constrained Compute. Zenodo. doi:10.5281/zenodo.21676407
@misc{aglawe2026agenttrace,
  author    = {Aglawe, Ankit},
  title     = {Agent-Trace Fine-Tuning of Small Language Models under Constrained Compute},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.21676407},
  url       = {https://doi.org/10.5281/zenodo.21676407}
}
Glint-Research & Roman1111111 for the open trace data · IBM Granite for the base · empero-ai, whose Qwable recipe the Parable series follows · llama.cpp
ollama run hf.co/AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5-GGUF:Q4_K_M
More on the Parable models: ankitaglawe.com/parable