
Downloads · 30 days
500
17% of all-time downloads
AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5
Parable-Granite-4.1-8B-Claude-Fable-5 is a text generation model from AnkitAI. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as apache-2.0.
<picture <source media="(prefers-color-scheme: dark)" srcset="https://raw.githubusercontent.com/ankit-aglawe/parable-assets/main/parableheaderdark.png" <img alt="Parable" src="https://raw.githubusercontent.com/ankit-a…
Downloads · 30 days
500
17% of all-time downloads
All-time downloads
2.9K
Public
Parameters
8.4B
33.5 GB on disk
Likes
6
Public
Click a slice to open those files.
.safetensors16.8 GB · 100%
From the Hugging Face model README
Granite 4.1 8B trained on real Claude Fable 5 and GPT-5.5 agent traces: 70% lower held-out test loss than its base, and past the 0.71 mark the 9B-class incumbent reports on this data family.
Parable-Granite-4.1-8B is an ibm-granite/granite-4.1-8b fine-tune trained on real multi-step agent sessions: planning, tool use, and <think> reasoning captured from actual Claude Fable 5 and GPT-5.5 agent work, not synthetic Q&A. Largest release in the Parable series, alongside Parable-Qwen3-4B.
from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained(
    "AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5",
    torch_dtype="auto", device_map="auto")
tok = AutoTokenizer.from_pretrained("AnkitAI/Parable-Granite-4.1-8B-Claude-Fable-5")

msgs = [{"role": "user", "content": "Write a Python function that retries an HTTP request with exponential backoff."}]
ids = tok.apply_chat_template(msgs, add_generation_prompt=True, return_tensors="pt").to(model.device)
out = model.generate(ids, max_new_tokens=3000, temperature=0.7, top_p=0.95, do_sample=True)
text = tok.decode(out[0][ids.shape[1]:], skip_special_tokens=True)
answer = text.split("</think>")[-1].strip()  # response opens with a <think> block
print(answer)
GGUF quants for llama.cpp / Ollama / LM Studio: Parable-Granite-4.1-8B-Claude-Fable-5-GGUF.
Sampling: temperature 0.7, top_p 0.95, generous max_new_tokens (at least 2500).
<think> reasoning and tool calls (AGPL-3.0)Every example passed a quality gate (schema validation, secrets scrub, length filtering) before training. QLoRA fine-tune (NF4, sequence length 1024) trained on a single 16 GB GPU, quantized with llama.cpp.
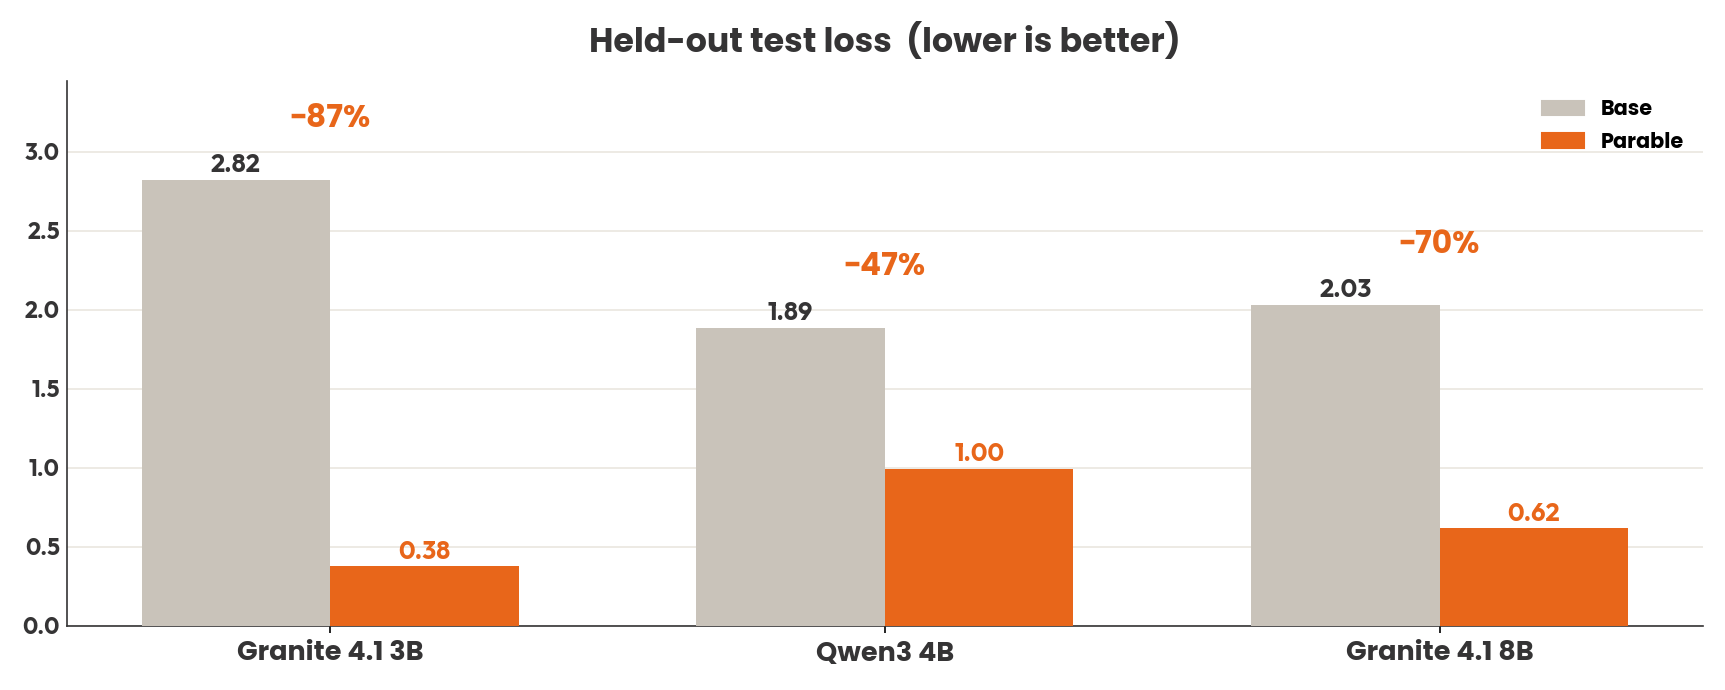
Held-out test split, identical evaluation code and context length for base and fine-tune:
| Metric | Base Granite-4.1-8B | Parable | Δ |
|---|---|---|---|
| Test loss | 2.030 | 0.617 | −70% |
Qualitative review (34 coding/terminal/debugging prompts, strictly graded by mentally executing every answer): 20/34 fully correct, 32/34 correct or partially correct. We publish these numbers because strict qualitative grading is rare in this niche; judge accordingly.
For reference, the strongest published fine-tune on this data family (a 9B) reports 0.71 validation loss. Cross-repo numbers are indicative only: splits, tokenizers, and context lengths differ (ours is measured at 1,024 tokens).
Measured 2026-07-29: bfcl-eval at gorilla main, prompting mode, Q4_K_M
GGUFs served by llama.cpp on a T4, base and Parable under the identical
harness. Categories: simple_python / multiple / parallel /
parallel_multiple (400/200/200/200 items). Raw generations and score
files: parable-v2-artifacts
under verify/bfcl/.
DNF. The run hit its 3-hour GPU budget: this chat variant's think blocks push most responses to the 4,096-token per-request cap, about 35 GPU-hours of decode for the full suite at T4 speed, so it cannot complete under the same budget every other row got. We report that rather than tightening the token cap for one model. For function-calling harnesses, use the base model; the 3B sibling's card shows the measured pattern on these categories.
As a fine-tune it inherits Granite-4.1-8B's base behaviors and knowledge cutoff. As with any local model, treat generated commands and code as drafts to review.
Model weights: Apache-2.0 (inherited from Granite-4.1-8B). Training data licenses: Fable-5-traces AGPL-3.0, gpt5.5-terminal MIT. Because those traces originate from third-party assistants, the providers' terms may apply to downstream training and distillation. If you plan to build on this model commercially, confirm your use aligns with those terms.
| Platform | Command / Link |
|---|---|
| Ollama | ollama run parable/granite4.1-fable:8b |
| Ollama (family flagship, best per size) | ollama run parable/fable |
| Hugging Face | GGUF quants, full weights, eval reports |
| LM Studio | lms get parable/granite4.1-fable (parable on LM Studio Hub) |
If this model is useful in your work, you can support independent research:
<p align="left"> <a href="https://www.buymeacoffee.com/AnkitAI" target="_blank"><img src="https://cdn.buymeacoffee.com/buttons/v2/default-yellow.png" alt="Buy Me a Coffee" height="60" width="217" /></a> </p>The recipe, evaluation methodology and failure analysis behind this model are documented in the tech report:
Aglawe, A. (2026). Agent-Trace Fine-Tuning of Small Language Models under Constrained Compute. Zenodo. doi:10.5281/zenodo.21676407
@misc{aglawe2026agenttrace,
  author    = {Aglawe, Ankit},
  title     = {Agent-Trace Fine-Tuning of Small Language Models under Constrained Compute},
  year      = {2026},
  publisher = {Zenodo},
  doi       = {10.5281/zenodo.21676407},
  url       = {https://doi.org/10.5281/zenodo.21676407}
}
More on the Parable models: ankitaglawe.com/parable