
Downloads · 30 days
104
1% of all-time downloads
AnReu/math_albert
math_albert is a feature extraction model from AnReu. Use it when you need embeddings to search or compare text. It is set up for transformers.
This repository contains our best base model for ARQMath 3. It was initialised from ALBERT-base-v2 and further pre-trained on Math StackExchange in three different stages. We also added more LaTeX tokens to the tokeni…
Downloads · 30 days
104
1% of all-time downloads
All-time downloads
11.3K
Public
Parameters
11.9M
95.8 MB on disk
Likes
3
Public
Click a slice to open those files.
.bin47.5 MB · 49%
How the weights are stored.
F3211.9M · 100%
From the Hugging Face model README
This repository contains our best base model for ARQMath 3. It was initialised from ALBERT-base-v2 and further pre-trained on Math StackExchange in three different stages. We also added more LaTeX tokens to the tokenizer to enable a better tokenization of mathematical formulas. This model is not yet fine-tuned on a specific task. If you are looking for the fine-tuned model, please refer to this page: AnReu/albert-for-arqmath-3
If you are looking for a Math-pre-trained BERT model: Check out our AnReu/math_pretrained_bert which is trained in the same way as this model here.
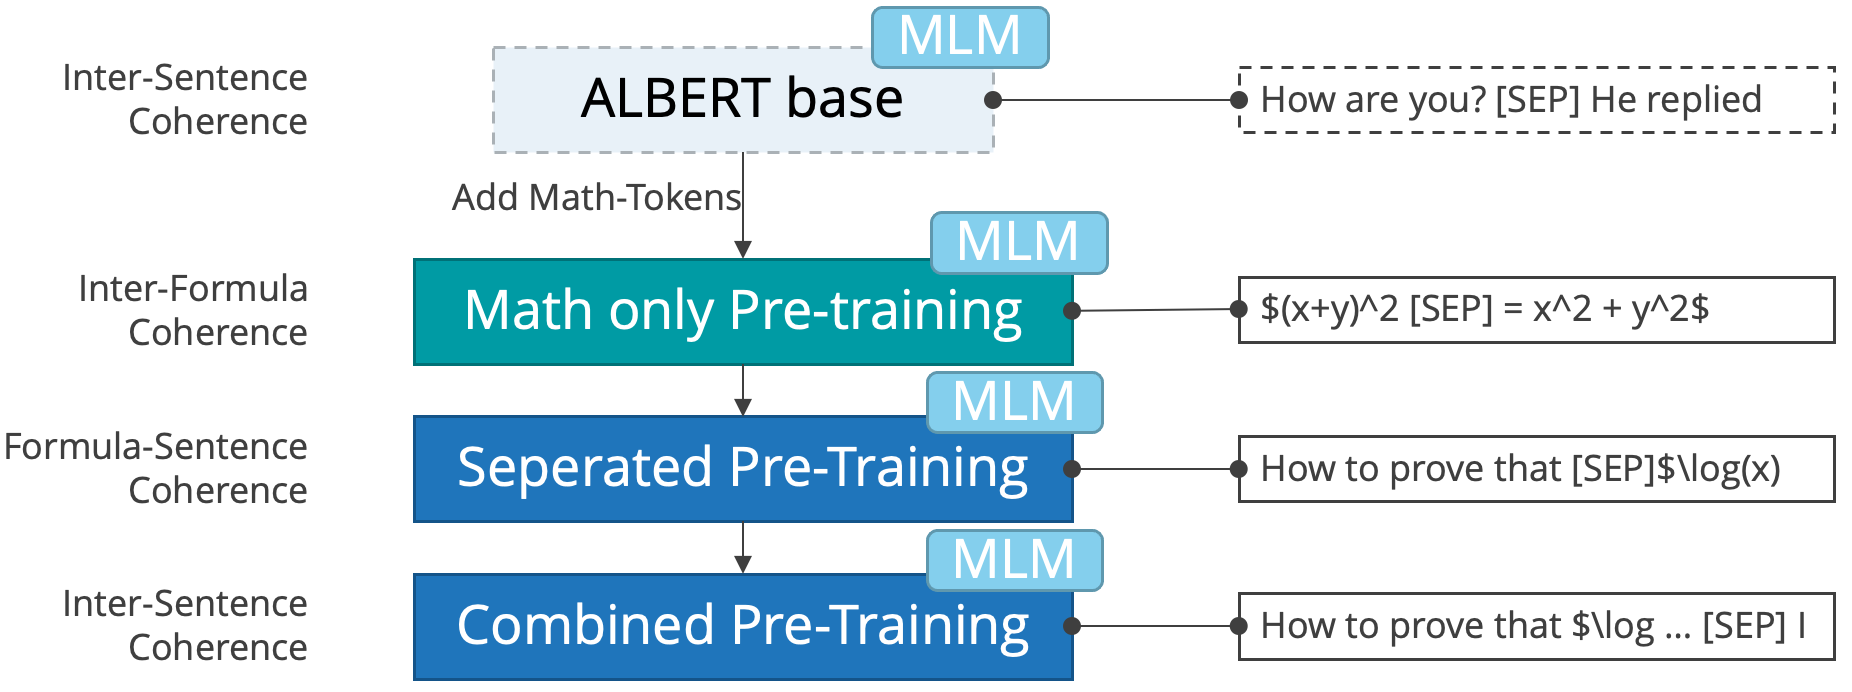
The model was instantiated from ALBERT-base-v2 weights and further pre-trained in three stages using different data for the sentence order prediction. During all three stages, the mask language modelling task was trained simultaneously. In addition, we added around 500 LaTeX tokens to the tokenizer to better cope with mathematical formulas.
The image illustrates the three pre-training stages: First, we train on mathematical formulas only. The SOP classifier predicts which segment contains the left hand side of the formula and which one contains the right hand side. This way we model inter-formula-coherence. The second stages models formula-sentence-coherence, i.e., whether the formula comes first in the original document or whether the natural language part comes first. Finally, we add the inter-sentence-coherence stage that is default for ALBERT. In this stage, sentences were split by a sentence separator.
For further details, please read our paper: http://ceur-ws.org/Vol-3180/paper-07.pdf.
You can use this model to further fine-tune it on any math-aware task you have in mind, e.g., classification, question-answering, etc. . Please note, that the model in this repository is only pre-trained and not fine-tuned. If you are looking for the fine-tuned model, please refer to this page: AnReu/albert-for-arqmath-3
If you find this model useful, consider citing our paper:
@article{reusch2022transformer,
  title={Transformer-Encoder and Decoder Models for Questions on Math},
  author={Reusch, Anja and Thiele, Maik and Lehner, Wolfgang},
  year={2022},
  organization={CLEF}
}