
Downloads · 30 days
0
Alonmarom/basketball-player-value-predictor
basketball-player-value-predictor is a machine learning model from Alonmarom. Use it for the machine learning task on the model card, and read the license before you ship it in a product.
Downloads · 30 days
0
Access
Public
Updated Dec 11, 2025
Repo size
15.8 MB
Likes
0
Public
Click a slice to open those files.
.zip9.4 MB · 46%
From the Hugging Face model README
This project explores a comprehensive dataset of NCAA college basketball players to understand patterns in player efficiency and to build machine learning models that can predict a player's intrinsic value.
The workflow includes:
porpag).We started by analyzing the distribution of the target variable and understanding key correlations.
First, we looked at the spread of player value across the entire dataset.

We examined which statistics are most strongly correlated with player value.

We investigated the relationship between shooting efficiency, usage rate, and value.
Efficiency: A strong positive correlation exists between effective shooting and value.

Usage Rate: We analyzed how volume of play (usg) impacts value.

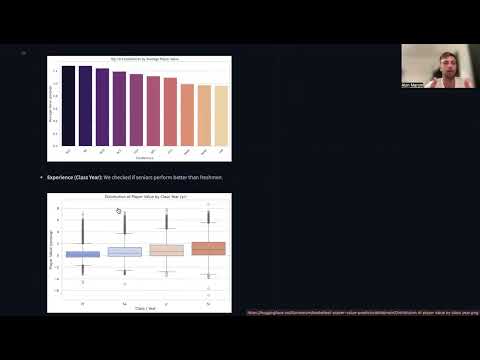
Conference Strength: Major conferences produce higher-valued players on average.

Experience (Class Year): We checked if seniors perform better than freshmen.

We trained a baseline Linear Regression model to predict the exact porpag score.
The scatter plot below shows how well the model's predictions align with reality. Ideally, points should lie on the diagonal red line.

We analyzed which features had the highest positive and negative coefficients in the regression model.

We used K-Means Clustering to identify 5 distinct player archetypes based on their stats.
Using Principal Component Analysis (PCA), we visualized the clusters in 2D space.

To understand the meaning of each group, we analyzed the average player value within each cluster.

We reframed the problem to classify players into three balanced tiers: Low, Mid, and High Value.
We ensured the classes were balanced (approx. 33% each) before training.

We trained three models (Logistic Regression, Random Forest, Gradient Boosting) and compared their RMSE/Error rates.

A visualization of the predicted labels compared to true labels (Confusion Matrix / Prediction Spread).

The Gradient Boosting / Random Forest model was selected as the winner due to superior performance.
What features mattered most to the winning model?

The trained models are hosted on Hugging Face for easy access and reproducibility.
[
random_forest_model.pkl): Predicts exact porpag value.gradient_boosting_classifier.pkl): Predicts player tier (Low/Mid/High).After downloading the .pkl files, you can load them using Python:
import pickle

# Example: Load the classification model
with open("gradient_boosting_classifier.pkl", "rb") as f:
    model = pickle.load(f)

print("Model loaded successfully!")
This analysis demonstrated that NCAA player value is highly predictable using statistical performance metrics. By combining exploratory analysis with advanced machine learning techniques, we established a robust framework for player evaluation.
Key Findings:
porpag).