
Downloads · 30 days
63
5% of all-time downloads
Abdu-GH/AraRest-Arabic-Restaurant-Reviews-Sentiment-Analysis
AraRest-Arabic-Restaurant-Reviews-Sentiment-Analysis is a text classification model from Abdu-GH. Use it when you need a label for a piece of text. It is set up for transformers. The card lists the license as apache-2.0.
This fine-tuned AraBERT model classifies Arabic restaurant reviews as Positive or Negative. It is based on aubmindlab/bert-base-arabertv2 and fine-tuned using Hugging Face Transformers.
Downloads · 30 days
63
5% of all-time downloads
All-time downloads
1.3K
Public
Parameters
135M
2.4 GB on disk
Likes
8
Public
Click a slice to open those files.
.safetensors541 MB · 100%
From the Hugging Face model README
This fine-tuned AraBERT model classifies Arabic restaurant reviews as Positive or Negative.
It is based on aubmindlab/bert-base-arabertv2 and fine-tuned using Hugging Face Transformers.
✅ Trained on Real Restaurant Reviews from the Hugging Face Dataset.
✅ Fine-tuned with Full Training (not LoRA or Adapters).
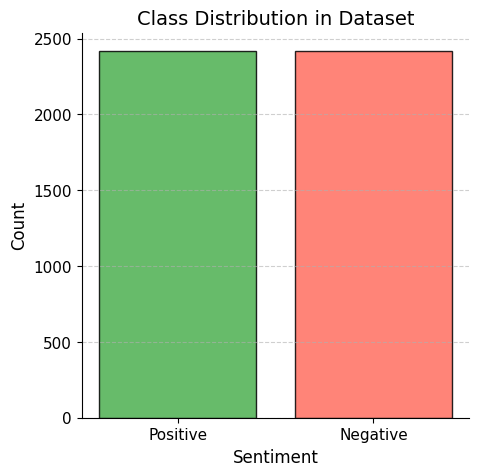
✅ Balanced Dataset (2418 Positive vs. 2418 Negative Reviews).
✅ High Accuracy & Performance for Sentiment Analysis in Arabic.
Run inference directly from the Hugging Face Space:
<p align="center"> <a href="https://huggingface.co/spaces/Abduuu/Arabic-Reviews-Sentiment-Analysis"> <img src="https://huggingface.co/datasets/huggingface/badges/resolve/main/open-in-hf-spaces-lg-dark.svg" alt="Open in HF Spaces" width="280px"> </a> </p>hadyelsahar/ar_res_reviewsإ, أ, آ → ا, ة → ه).aubmindlab/bert-base-arabertv2).The model was fine-tuned using Hugging Face Transformers with the following hyperparameters:
| Metric | Score |
|---|---|
| Eval Loss | 0.354245 |
| Accuracy | 87.40% |
| Precision | 85.28% |
| Recall | 86.33% |
| F1-score | 85.81% |
training_args = TrainingArguments(
    output_dir="./results",
    evaluation_strategy="epoch",
    save_strategy="epoch",
    per_device_train_batch_size=8,
    per_device_eval_batch_size=8,
    num_train_epochs=4,
    weight_decay=1,
    learning_rate=1e-5,
    lr_scheduler_type="cosine",
    warmup_ratio=0.1,
    fp16=True,
    save_total_limit=2,
    gradient_accumulation_steps=2,
    load_best_model_at_end=True,
    max_grad_norm=1.0,
    metric_for_best_model="eval_loss",
    greater_is_better=False,
)
pipeline()from transformers import pipeline
model_name = "Abduuu/ArabReview-Sentiment"
sentiment_pipeline = pipeline("text-classification", model=model_name)
review = "الطعام كان رائعًا والخدمة ممتازة!"
result = sentiment_pipeline(review)
print(result)
✅ Example Output:
[{'label': 'Positive', 'score': 0.91551274061203}]
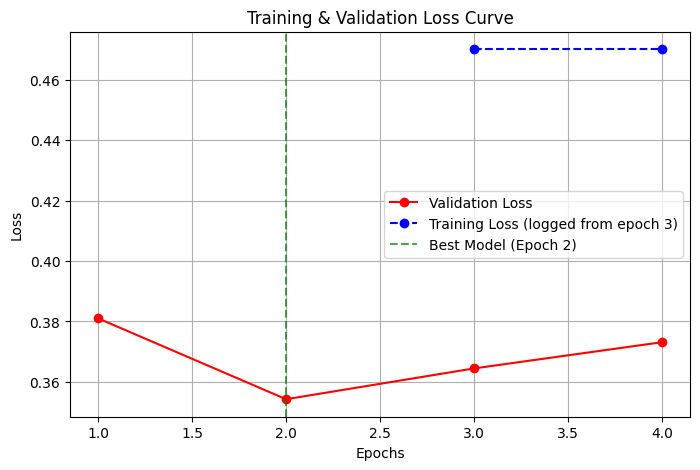
The model was trained for 4 epochs, and the best model was selected at Epoch 2 (lowest validation loss).
For questions or collaborations, feel free to reach out! 🚀