
Downloads · 30 days
3.4K
40% of all-time downloads
AMAImedia/GLM-5.3-Flash-FP8-GGUF
GLM-5.3-Flash-FP8-GGUF is a image-text-to-text model from AMAImedia. Use it for the image-text-to-text task on the model card, and read the license before you ship it in a product. It is set up for transformers. The card lists the license as apache-2.0.
<div style="background-color: f59e0b; color: white; padding: 20px; border-radius: 10px; text-align: center; margin: 20px 0;" <h2 style="color: white; margin: 0 0 10px 0;"⚡ Each donation funds the next large quant.</h2…
Downloads · 30 days
3.4K
40% of all-time downloads
All-time downloads
8.5K
Public
Parameters
321B
480 GB on disk
Likes
0
Public
Click a slice to open those files.
.safetensors331 GB · 69%
How the weights are stored.
F8_E4M3314B · 98%
From the Hugging Face model README
Released as part of the NOESIS Professional Multilingual Dubbing Automation Platform (framework: DHCF-FNO — Deterministic Hybrid Control Framework for Frozen Neural Operators).
We introduce GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series. With 320B total parameters and just 18B active parameters, it is designed for efficient long-context, coding, agentic, and multimodal workloads.
GLM-5.3-Flash starts from a newly trained base model, with its architecture and training recipe redesigned around capability and efficiency. It combines sparse and linear attention with Manifold-Constrained Hyper-Connections (mHC) and a multimodal pre-training corpus.
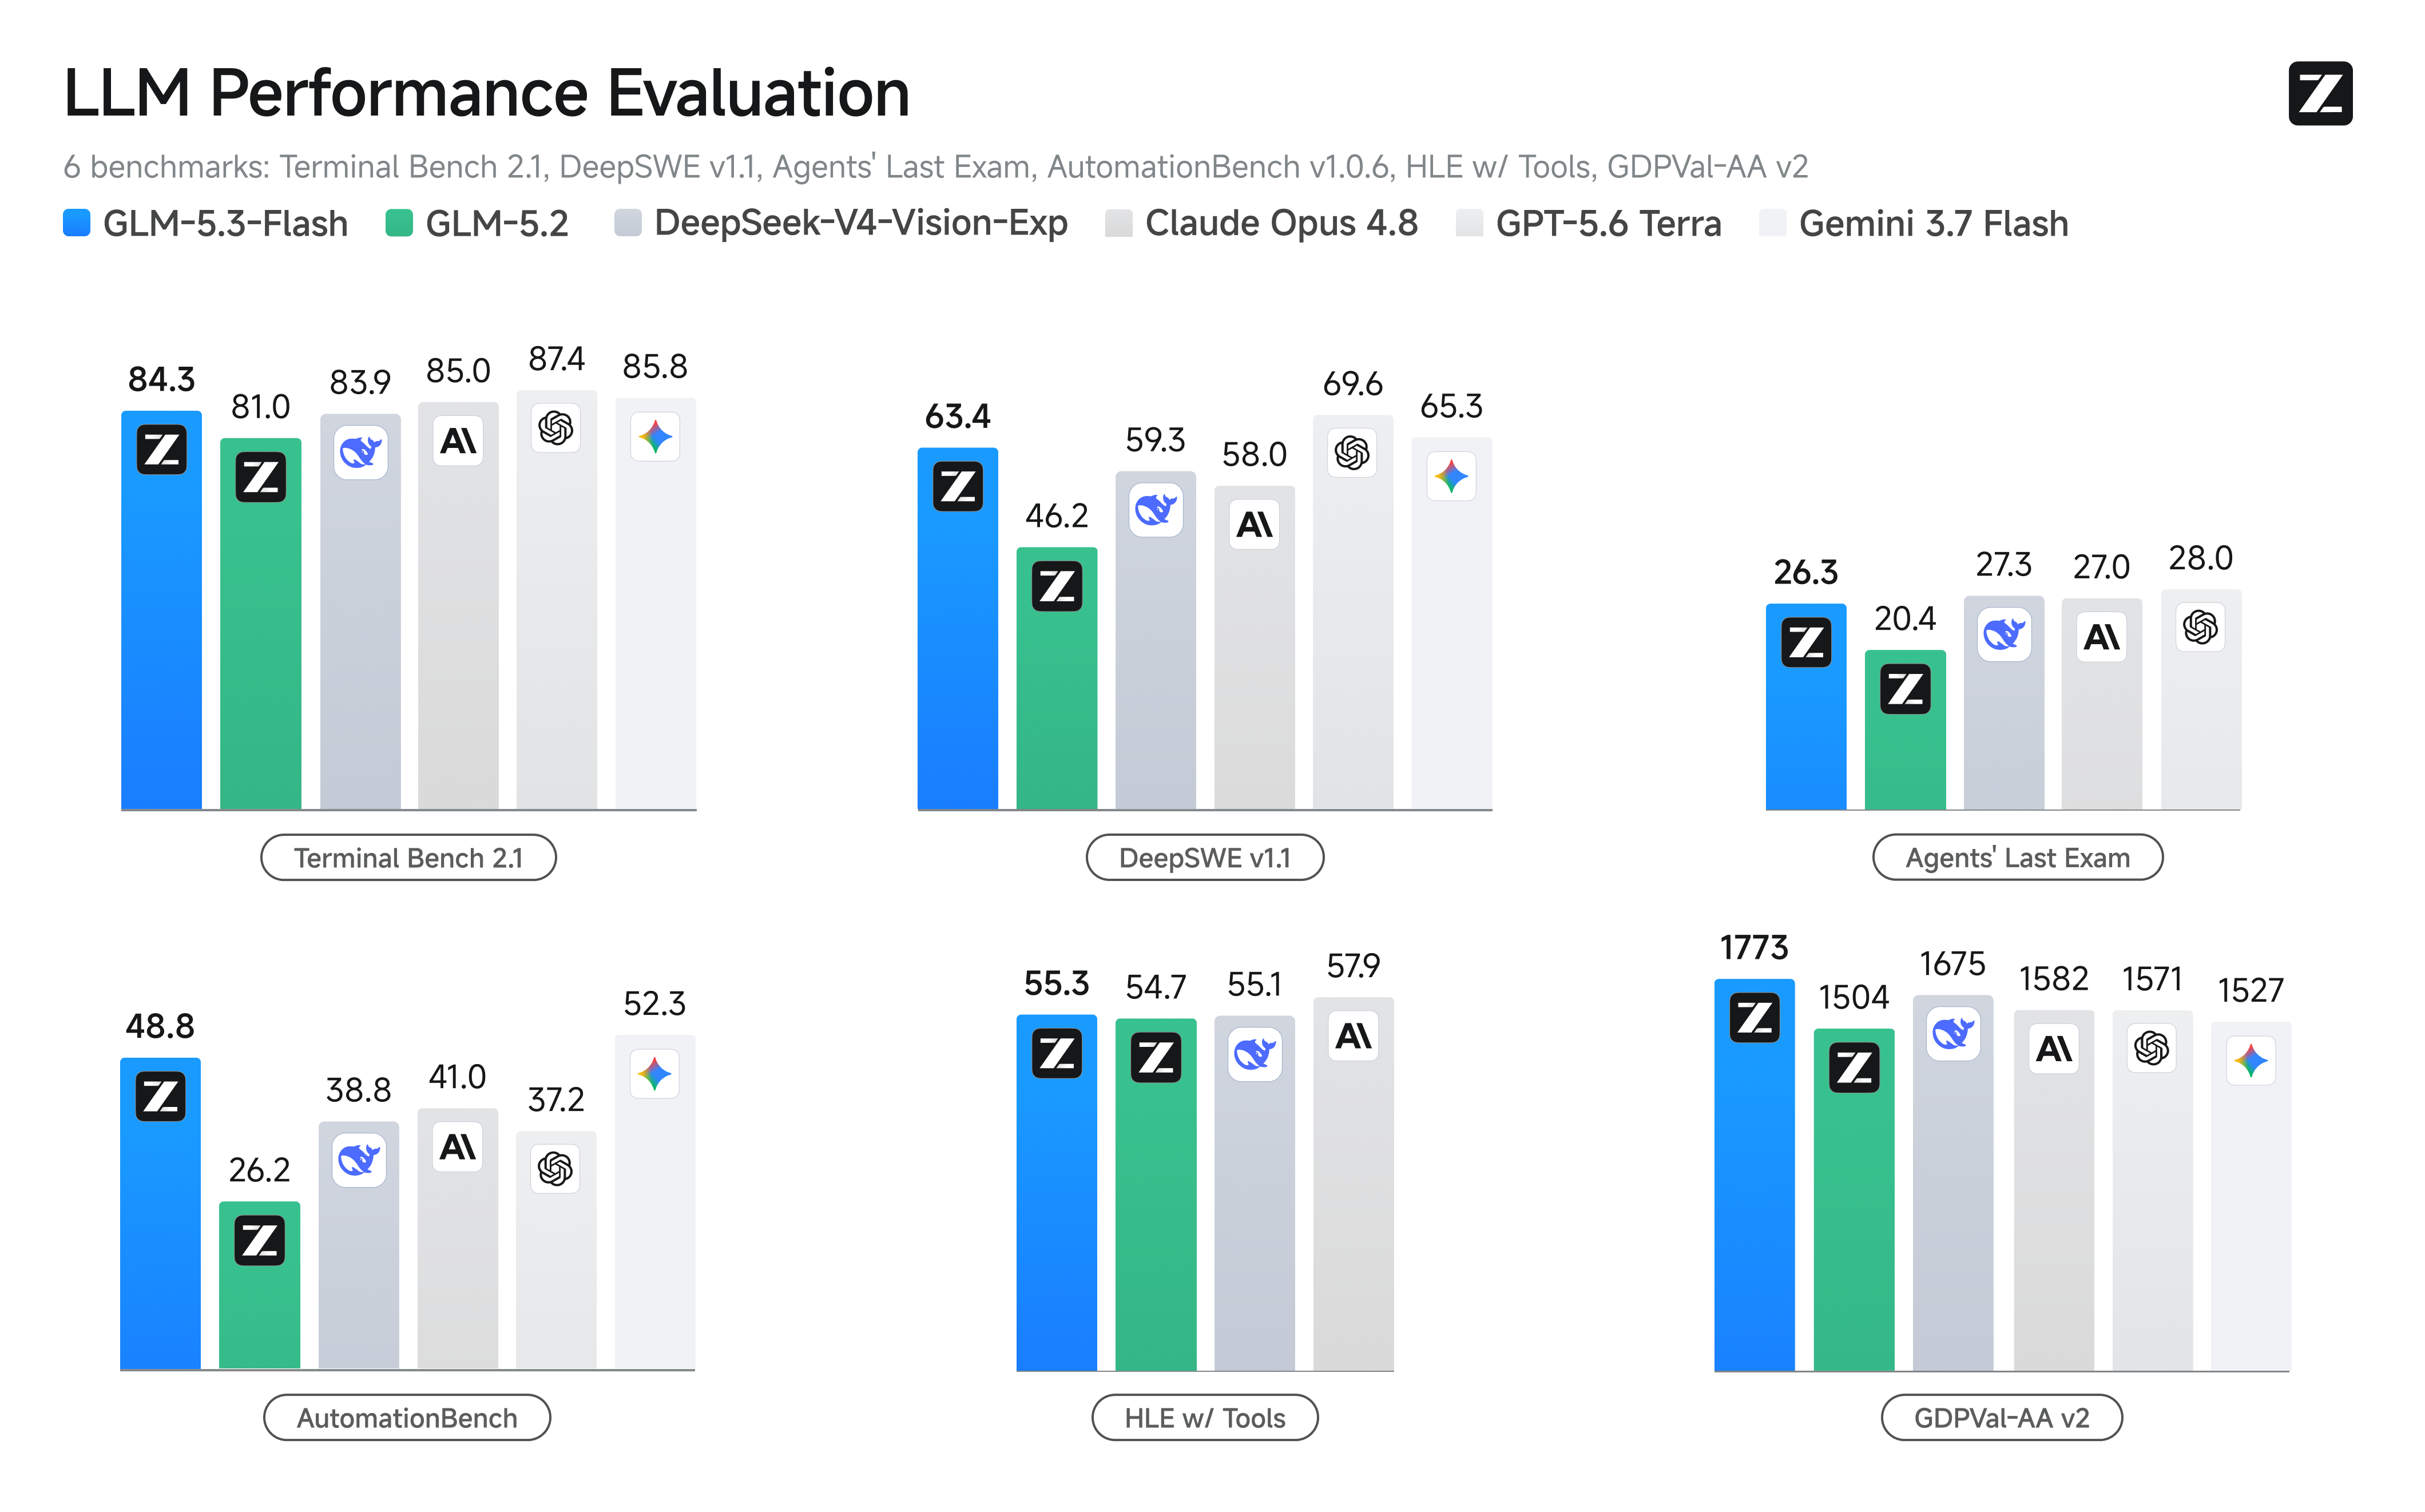
GLM-5.3-Flash supports deployment with the following frameworks:
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer

model_id = "AMAImedia/GLM-5.3-Flash"
tokenizer = AutoTokenizer.from_pretrained(model_id, trust_remote_code=True)
model = AutoModelForCausalLM.from_pretrained(
    model_id,
    torch_dtype=torch.bfloat16,
    device_map="auto",
    trust_remote_code=True,
)

messages = [{"role": "user", "content": "Explain the main benefits of multimodal agents."}]
inputs = tokenizer.apply_chat_template(
    messages,
    add_generation_prompt=True,
    return_tensors="pt",
).to(model.device)

with torch.inference_mode():
    output = model.generate(
        inputs,
        max_new_tokens=512,
        temperature=0.7,
        top_p=0.9,
        do_sample=True,
    )

print(tokenizer.decode(output[0][inputs.shape[-1]:], skip_special_tokens=True))
For image questions, use the official GLM processor and multimodal message format documented by the model implementation. Keep image inputs in the message content and use the processor to build model inputs; verify the exact API against the installed Transformers version.
from transformers import AutoProcessor, AutoModelForMultimodalLM

model_id = "AMAImedia/GLM-5.3-Flash"
processor = AutoProcessor.from_pretrained(model_id, trust_remote_code=True)
model = AutoModelForMultimodalLM.from_pretrained(
    model_id,
    device_map="auto",
    torch_dtype="auto",
    trust_remote_code=True,
)

messages = [{
    "role": "user",
    "content": [
        {"type": "image", "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/p-blog/candy.JPG"},
        {"type": "text", "text": "What is shown in this image?"},
    ],
}]

inputs = processor.apply_chat_template(
    messages,
    add_generation_prompt=True,
    tokenize=True,
    return_dict=True,
    return_tensors="pt",
).to(model.device)

outputs = model.generate(**inputs, max_new_tokens=128)
print(processor.decode(outputs[0][inputs["input_ids"].shape[-1]:], skip_special_tokens=True))
pip install -U vllm
vllm serve AMAImedia/GLM-5.3-Flash \
  --trust-remote-code \
  --tensor-parallel-size 8 \
  --max-model-len 131072
The server exposes an OpenAI-compatible endpoint:
from openai import OpenAI

client = OpenAI(base_url="http://localhost:8000/v1", api_key="EMPTY")
response = client.chat.completions.create(
    model="AMAImedia/GLM-5.3-Flash",
    messages=[{"role": "user", "content": "Write a concise summary of this document."}],
    temperature=0.7,
    max_tokens=512,
)
print(response.choices[0].message.content)
Use bfloat16 where supported, or a framework-supported quantized checkpoint when GPU memory is limited. For multimodal serving, follow the selected framework's documented image-input format. Confirm the installed framework version, GPU memory requirements, tensor-parallel configuration, and supported context length before production deployment.
If you find GLM-5.3-Flash useful in your research, please cite the official technical report:
@misc{glm5team2026glm5vibecodingagentic,
  title={GLM-5: from Vibe Coding to Agentic Engineering},
  author={GLM-5-Team},
  year={2026},
  eprint={2602.15763},
  archivePrefix={arXiv},
  primaryClass={cs.LG},
  url={https://arxiv.org/abs/2602.15763},
}