Downloads · 30 days
670
2% of all-time downloads
AI-Sweden-Models/Llama-3-8B
Llama-3-8B is a text generation model from AI-Sweden-Models. Use it when you need the model to write or continue text. It is set up for transformers. The card lists the license as llama3.
Downloads · 30 days
670
2% of all-time downloads
All-time downloads
44.3K
Public
Parameters
8B
161 GB on disk
Likes
24
Public
Click a slice to open those files.
.safetensors16.1 GB · 100%
From the Hugging Face model README

This is a base model, it can be finetuned to a particular use case.
-----> instruct version here <-----
See the snippet below for usage with Transformers:
import transformers
import torch

model_id = "AI-Sweden-Models/Llama-3-8B"

pipeline = transformers.pipeline(
    task="text-generation",
    model=model_id,
    model_kwargs={"torch_dtype": torch.bfloat16},
    device_map="auto"
)

pipeline(
    text_inputs="Sommar och sol är det bästa jag vet",
    max_length=128,
    repetition_penalty=1.03
)
>>> "Sommar och sol är det bästa jag vet!
Och nu när jag har fått lite extra semester så ska jag njuta till max av allt som våren och sommaren har att erbjuda.
Jag har redan börjat med att sitta ute på min altan och ta en kopp kaffe och läsa i tidningen, det är så skönt att bara sitta där och njuta av livet.

Ikväll blir det grillat och det ser jag fram emot!"
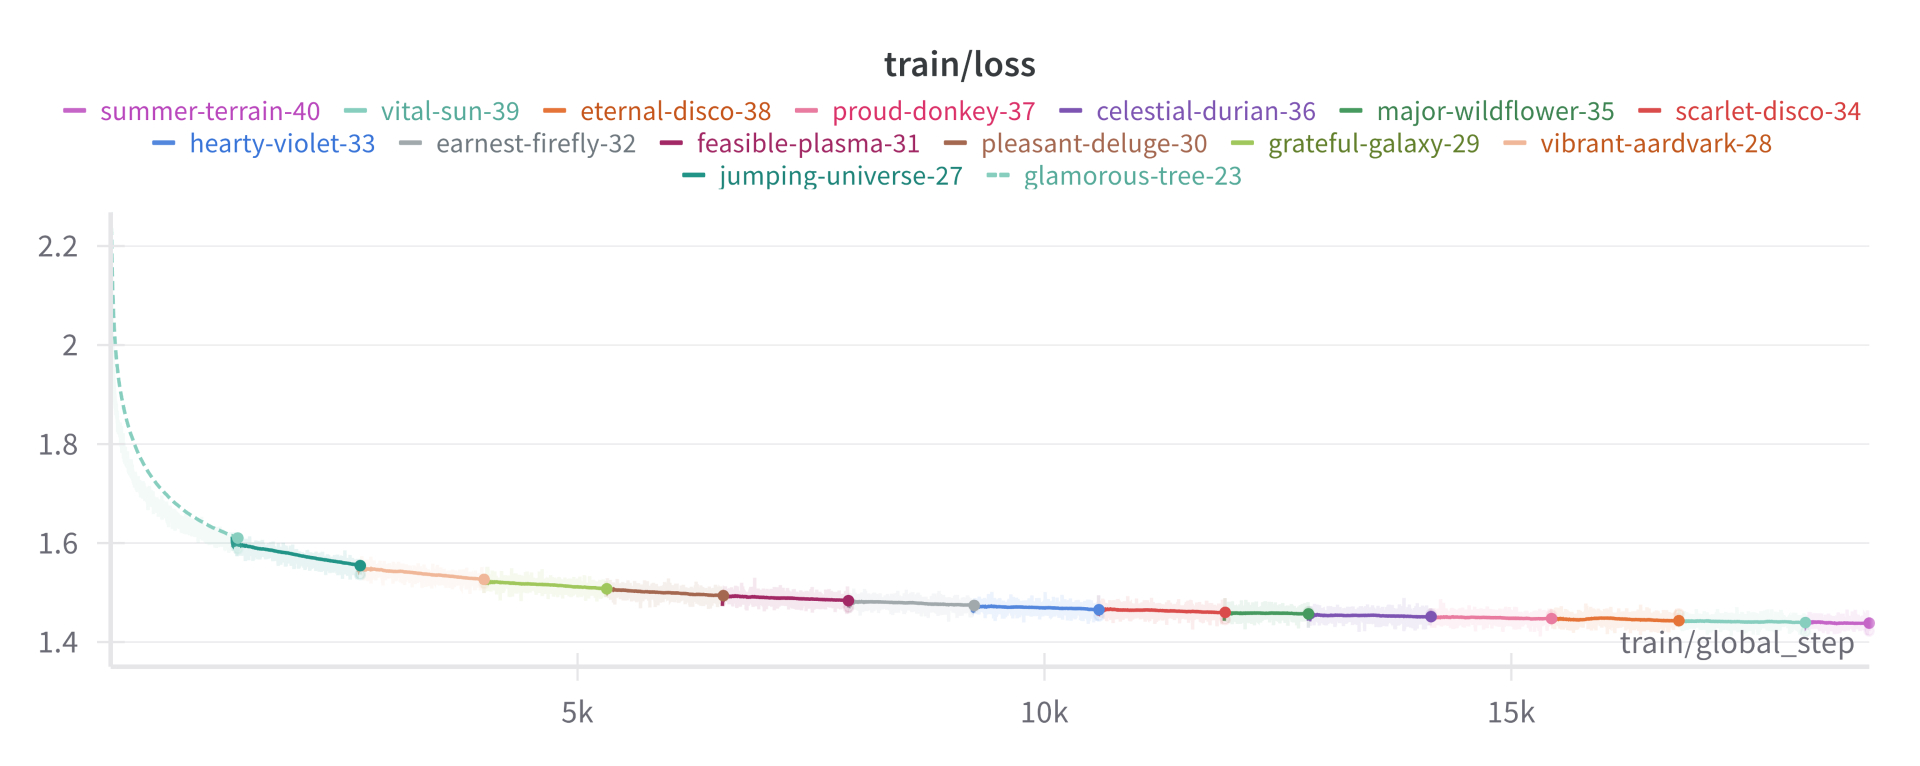
AI-Sweden-Models/Llama-3-8B is a continuation of the pretraining process from meta-llama/Meta-Llama-3-8B.
It was trained on a subset from The Nordic Pile containing Swedish, Norwegian and Danish. The training is done on all model parameters, it is a full finetune.
The training dataset consists of 227 105 079 296 tokens. It was trained on the Rattler supercomputer at the Dell Technologies Edge Innovation Center in Austin, Texas. The training used 23 nodes of a duration of 30 days, where one node contained 4X Nvidia A100 GPUs, yielding 92 GPUs.
learning_rate: 2e-5
warmup_steps: 100
lr_scheduler: cosine
optimizer: adamw_torch_fused
max_grad_norm: 1.0
gradient_accumulation_steps: 16
micro_batch_size: 1
num_epochs: 1
sequence_len: 8192
{
  "zero_optimization": {
    "stage": 2,
    "offload_optimizer": {
      "device": "cpu"
    },
    "contiguous_gradients": true,
    "overlap_comm": true
  },
  "bf16": {
    "enabled": "auto"
  },
  "fp16": {
    "enabled": "auto",
    "auto_cast": false,
    "loss_scale": 0,
    "initial_scale_power": 32,
    "loss_scale_window": 1000,
    "hysteresis": 2,
    "min_loss_scale": 1
  },
  "gradient_accumulation_steps": "auto",
  "gradient_clipping": "auto",
  "train_batch_size": "auto",
  "train_micro_batch_size_per_gpu": "auto",
  "wall_clock_breakdown": false
}